Evaluation
Methodology
- Data. Everything is pinned and checksum-verified: SigmaHQ
07ec293(rules,regression_data,known-FPs.csv), evtx-baseline v0.8.5 (benign), OTRFd9d40ef(Windows, Linux, AWS emulations), Splunk attack_datab4573ed(Linux, CloudTrail), ATT&CK 19.2. See Datasets. - Run. One
benchworkflow run, 37093721154 at commit9906b42with all three jobs green, on cleanubuntu-latestrunners (4 vCPU, 16 GB): thebenchjob (all stages), thebackendjob (OpenSearch) and thereportjob, which joins both and checks that every results file carries that run's id and commit. The run id and commit are stated at the top of the results below and in every file'sprovenance(with package versions and dataset pins). The run asserts that every OTRF archive and regression capture was readable, so the files that endpoint AV quarantines on the development laptop are included. - Technique detected. A rule tagged with the capture's technique or its parent fired on the capture. Sibling sub-techniques are reported separately as "lenient".
- Alerts per host-day. Hits divided by the sum of per-host recording spans (2.55 host-days). The budget is 20 alerts per host-day per rule (10% of a 200/day SOC); the fleet table projects it to N hosts. The recordings are install-day telemetry, so install-related rules are likely noisier here than in steady state.
- Decay ground truth, simulated. A TP-validated rule is broken by a change when its regression captures, replayed through the simulated change, no longer fire it. The static check only sees the benign field inventory, transformed by the same change, so its precision there is partly a soundness property of the transform.
- Decay ground truth, real. OTRF captures that log both Sysmon EID 1 and native Security 4688 are replayed with and without their Sysmon channel; a rule is broken when it fires on them before and on none of them after. The prediction uses the benign inventory with its real Sysmon events dropped. No simulator is involved.
- Intervals and tests. Wilson 95% intervals for proportions, printed as
k/n, p% [lo, hi]; exact McNemar tests for paired comparisons on the same rules or datasets; a bootstrap over rules for the FP-model AUCs and for Cohen's kappa; the "interval over CV repetitions" in the FP model only measures fold-assignment noise. - Exclusions. The 23-rule
rules-placeholderfolder; deprecated rules; 2 rules with unsupported features.
Results
Provenance. Every number below comes from one bench workflow run, 37093721154 at commit 9906b42, with all three jobs green (bench, OpenSearch backend, report) on clean ubuntu runners and fresh, checksum-verified downloads. The results artefact of that run is committed unmodified; each results file records the run id, git SHA, package versions and dataset pins, and python benchmarks/bench.py verify diffs a reproduction against it. Proportions are k/n, p% [Wilson 95% CI]; the full tables are in results/SUMMARY.md and the method is on the Evaluation page.
1. Decay monitor (the novel part)
anvil decay checks every rule's condition for satisfiability against the field inventory observed per log source. It uses benign telemetry only, with no attack data. It is compared with two field-presence checks (the per-field logic of schema validation): per log source, and global (ANVIL 0.1).
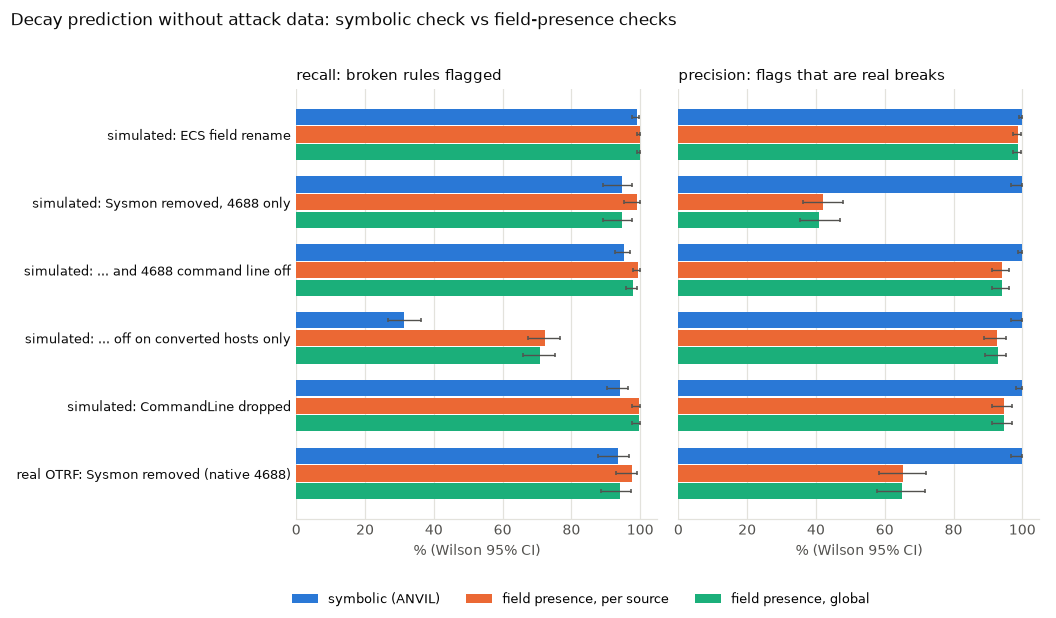
Real change, no simulator. 88 OTRF captures log both Sysmon EID 1 and native Security 4688. 286 Windows rules fire on them; 122 fire on none once the Sysmon channel is dropped from the real captures. The prediction comes from the benign inventory with its real Sysmon events dropped:
| method | flags on the 122 broken rules (recall) | precision | false alarms on the 164 rules that keep firing |
|---|---|---|---|
| symbolic (ANVIL) | 114/122, 93.4% [87.6, 96.6] | 114/114, 100% [96.7, 100] | 0 |
| field presence, per source | 119/122, 97.5% [93.0, 99.2] | 119/182, 65.4% [58.2, 71.9] | 63 |
| field presence, global (0.1) | 115/122, 94.3% [88.6, 97.2] | 115/177, 65.0% [57.7, 71.6] | 62 |
Exact McNemar tests on the same rules: false alarms 0 vs 63 (p = 2.2e-19) and 0 vs 62 (p = 4.3e-19); flags on broken rules 114 vs 119 (5 discordant, p = 0.062) and 114 vs 115 (5 / 6 discordant, p = 1.0). Of the 8 misses, 3 (two WMI-event rules and one file-deletion rule) have no log source in the benign inventory even before the change, so they sit on the floor below and are not counted as worsened; 5 are process-creation rules with a selection whose fields 4688 also carries, which stop firing because the captures' 4688 events do not match them (different values, or a field: null filter that now excludes every event), an effect a field-level check cannot see. Labels here are "fires at all", not "detects its technique".
Simulated changes. Each change is applied to the TP-validated rules' SigmaHQ regression captures (ground truth) and to the benign inventory (prediction). Because the same transform builds both sides, the symbolic check's 100% precision in these rows is partly a soundness property of the transform; the real row above does not have that property. Recall / precision:
| change (broken TP rules) | symbolic (ANVIL) | field presence per source | field presence global (0.1) |
|---|---|---|---|
| Sysmon removed, 4688 only (115) | 109/115, 94.8% [89.1, 97.6] / 109/109, 100% [96.6, 100] | 114/115, 99.1% [95.2, 99.8] / 114/272, 41.9% [36.2, 47.8] | 109/115, 94.8% [89.1, 97.6] / 109/266, 41.0% [35.2, 47.0] |
| ... and 4688 command-line auditing off, fleet-wide (349) | 333/349, 95.4% [92.7, 97.2] / 333/333, 100% [98.9, 100] | 347/349, 99.4% [97.9, 99.8] / 347/369, 94.0% [91.1, 96.0] | 342/349, 98.0% [95.9, 99.0] / 342/363, 94.2% [91.3, 96.2] |
| same, off only on converted hosts (mixed inventory, 349) | 109/349, 31.2% [26.6, 36.3] / 109/109, 100% [96.6, 100] | 252/349, 72.2% [67.3, 76.6] / 252/272, 92.6% [88.9, 95.2] | 247/349, 70.8% [65.8, 75.3] / 247/266, 92.9% [89.1, 95.4] |
| ECS field rename (430) | 426/430, 99.1% [97.6, 99.6] / 426/426, 100% [99.1, 100] | 430/430, 100% [99.1, 100] / 430/435, 98.9% [97.3, 99.5] | 430/430, 100% [99.1, 100] / 430/435, 98.9% [97.3, 99.5] |
| CommandLine dropped (234) | 220/234, 94.0% [90.2, 96.4] / 220/220, 100% [98.3, 100] | 233/234, 99.6% [97.6, 99.9] / 233/246, 94.7% [91.2, 96.9] | 233/234, 99.6% [97.6, 99.9] / 233/246, 94.7% [91.2, 96.9] |
| Hashes dropped (0) | 6 rules flagged, none TP-validated | 47 flagged; 7 have TP evidence and all 7 are false alarms | 54 flagged; same 7 |
No change-induced false alarm on a TP-validated rule. Against per-source presence, the false-alarm difference is significant in every row (exact McNemar, e.g. 0 vs 158 of 345 unbroken rules, p = 5.5e-48, for the Sysmon removal), and presence catches more broken rules in the command-line rows (0 vs 14 discordant, p = 1.2e-4). The symbolic check's weakness is the fleet-union inventory: when only some hosts change (the mixed row), the union still contains the field. The 6 rules it flags for the Hashes change need Hashes on every path, so presence flags them too; they have no regression capture, so they are not scored. On unchanged telemetry, 183 rules (6.4%) are already broken or have no source and are reported separately as the floor; 3 of them are TP-validated (WMI Event Subscription, Important Scheduled Task Deleted/Disabled, and a RedSun EICAR rule), i.e. false alarms before any change. Per-rule flag sets and every test are in results/decay.json.
2. TP replay (recall) on SigmaHQ regression captures
| engine | detected | missed | could not evaluate | detection rate |
|---|---|---|---|---|
| ANVIL engine (1.x) | 463 | 0 | 0 | 463/463, 100% [99.2, 100] |
| ANVIL 0.1 (frozen baseline) | 420 | 14 | 29 | 420/463, 90.7% [87.7, 93.0] |
| pySigma -> SQLite (independent condition/value semantics on ANVIL-routed events) | 461 | 1 | 1 | 461/463, 99.6% [98.4, 99.9] |
This only measures recall, and it was the development acceptance set: most captures hold a single event, so over-matching can barely be detected here. The benign replay and the OpenSearch cross-check test the other direction. On an 1,800-event benign sample, the 1.x engine with log-source routing switched off raises 163 alerts from 16 rules over 5.12M rule evaluations, exactly what the 0.1 engine raises; with routing on it raises 15 alerts from 2 rules over 44k evaluations. So on this sample the whole reduction comes from routing, not from the 1.x value-semantics changes.
3. False positives on clean Windows hosts (evtx-baseline)
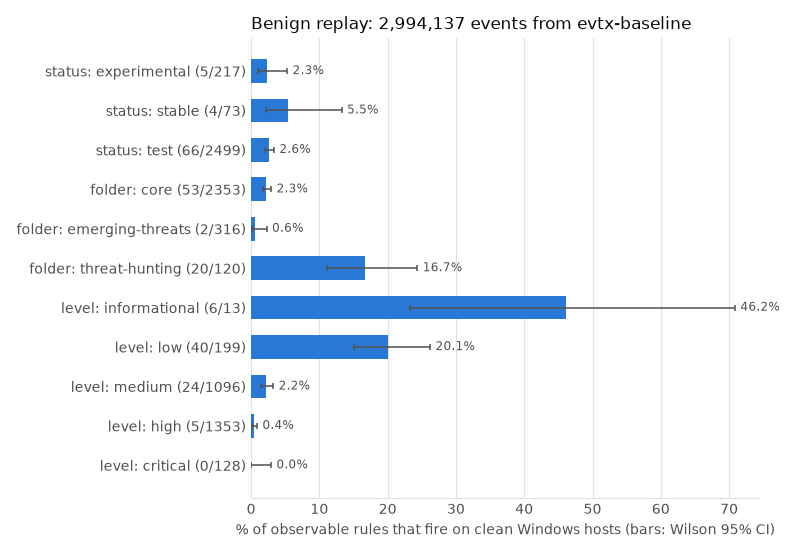
The corpus has 2,994,137 events from three hosts (Win10, Win11, Server 2022 AD), covering 2.55 host-days of install-day recordings. 75/2,789 observable rules fire, 2.7% [2.2, 3.4]. The budget lets a rule use 10% of a 200 alerts/day SOC, i.e. 20 alerts per host-day. When the per-host rate is projected to a fleet, the number of rules over budget grows:
| hosts | 1 | 3 | 10 | 100 |
|---|---|---|---|---|
| rules over budget (of 75 firing) | 12 | 26 | 41 | 75 |
The noisiest rules are install-driven (scheduled-task registry writes, AppX installs, AppCompat), so these per-day rates are likely higher than a steady-state host's (see Limitations). By level: 0/128 critical, 5/1,353 high (0.4% [0.2, 0.9]), 24/1,096 medium, 40/199 low and 6/13 informational rules fire. Against SigmaHQ's known-FPs.csv, 27 of the 29 medium+ rules that fire are listed (matched per rule id; the list was also used during development). Eight non-low rules fire in ANVIL without an entry: 2 medium (PowerShell-classic HostApplication parsing) and 6 informational. SigmaHQ's goodlog CI is green on the same images, and excusing per rule id is more lenient than its MatchString filters, so these 8 are a lower bound on rules where ANVIL fires and SigmaHQ's checker does not. They are listed in SUMMARY.
4. Emulated attacks and ATT&CK coverage
| corpus | captures | technique detected (exact or parent) | lenient (sibling sub-techniques credited) | any alert |
|---|---|---|---|---|
| OTRF Windows atomic | 98 | 62/98, 63.3% [53.4, 72.1] | 69/98, 70.4% [60.7, 78.5] | 95/98, 96.9% [91.4, 99.0] |
| Linux auditd (Splunk attack_data, OTRF) | 65 | 8/65, 12% [6, 22] | - | 19/65, 29% [20, 41] |
| Sysmon for Linux | 63 | 13/63, 21% [12, 32] | - | 38/63, 60% [48, 71] |
| AWS CloudTrail | 40 | 6/40, 15% [7, 29] | - | 32/40, 80% [65, 90] |
The CI runner also records its own telemetry (auditd and Sysmon for Linux; scripts/record_linux_live.sh). In a 3-second window of benign discovery-style commands, each labelled with the technique it resembles, 7/8 techniques are detected, 88% [53, 98] (T1033, T1082, T1007, T1087.001, T1057, T1016, T1083; T1027 missed: the SigmaHQ base64 rules look for decoding, piping into a shell or encoded shebangs, not for encoding a file), from 755 events and 17 alerts by 10 Linux rules. An 11-second benign developer workload on the same runner (venv, pip install, the unit tests, git; 15,480 events) fires 42 alerts from 6 Linux rules; it is far too short for a per-day rate and serves as a parser smoke test.
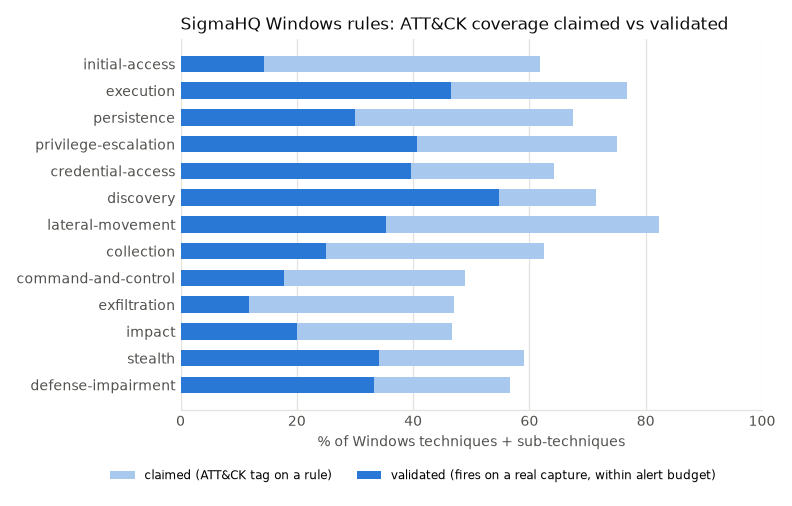
On ATT&CK Enterprise 19.2 for Windows, rule tags claim 299/474 techniques, 63.1% [58.6, 67.3]. Only 164/474, 34.6% [30.5, 39.0], are validated by a rule that fires on a real capture. On the APT29 evaluation captures, 111 and 117 rules fire, and they carry 69-70 distinct technique tags. That counts tags on fired rules, including rules triggered by background noise, not techniques covered.
SigmaHQ ships no correlation rules at the pinned commit 07ec293 (0 correlation: documents in any folder; also 0 on master 330d1cf, 2026-10-02). Its legacy aggregations live outside the rule folders: unsupported/ holds 87 rules, 45 with count() and 54 with any aggregation in the condition, plus one count() rule in deprecated/ (results/lint.json, aggregation_census). Correlation is therefore out of scope.
5. Real backend: OpenSearch vs ANVIL
In the CI backend job, pySigma's OpenSearch Lucene backend converts each Windows rule, using pySigma's own Sysmon and Windows log-source pipelines rather than ANVIL's router. The job then runs the queries with _search against an OpenSearch 2.19.1 container that holds the regression captures and an 1,800-event benign sample (results/backend_opensearch.json). The container runs without a restart policy, and the job fails on a restart or any java.lang.OutOfMemoryError in its log.
| comparison | compared | agree |
|---|---|---|
| regression captures: verdict | 458 | 450/458, 98.3% [96.6, 99.1] |
| benign sample: identical matching event set per rule | 2,836 | 2,835/2,836, 99.96% [99.80, 99.99] |
| benign sample, only rules that fire in either engine | 3 | 2/3 |
All 8 regression disagreements are captures that ANVIL and SigmaHQ's expected counts say should match, but OpenSearch returns nothing: 7 use |re (Lucene regexes must match the whole term, whereas Sigma regexes are unanchored searches, so the converted query is stricter than the rule) and 1 uses |cidr on a field indexed as keyword. In 1.1.0 there were 26: the 17 PowerShell script-block captures then counted as undiagnosed held ScriptBlockText values of 11,890-19,086 characters, which the old 10,922-character ignore_above mapping never indexed; values are now indexed up to Lucene's 32,766-byte term limit.
On benign data the two engines differ on one rule (OpenSearch 4 hits, ANVIL 0). The 99.96% is dominated by rules that fire in neither engine: only 3 rules fire at all, and 2 of them agree exactly (Cohen's kappa 0.80, bootstrap 95% CI [0.00, 1.00], i.e. undetermined with 3 firing rules). 19 rules raise HTTP 400 query errors, all recorded with their cause in results/backend_opensearch.json: 14 use regex syntax Lucene rejects (\b, \n, named groups, quote characters), 3 exceed Lucene's 10,000-state regex determinization limit, and 2 are very long OR lists (npm package names, driver hashes) that fail to parse. 4 rules cannot be converted. In 1.1.0 the job's first run died with java.lang.OutOfMemoryError at a 2 GB heap: Sigma keyword searches have no field and were expanded over every mapped field. They now query one catch-all field, and the run above has no restart and no heap error.
6. Drafter, SIEM conversion, FP prediction
| drafter on OTRF descriptions + transcripts | fires on its own emulation | fires and within budget | datasets with benign FPs | benign alerts |
|---|---|---|---|---|
| heuristic (68 datasets with a draft) | 32/68, 47% [36, 59] | 32 | 6 | 57 |
| naive keywords (baseline, 75 datasets with a draft) | 56/75, 75% [64, 83] | 35 | 33 | 126,768 |
| hand-written SigmaHQ, same 68 (any alert / technique) | 66 / 46 | - | - | - |
Paired over all 98 datasets (a dataset without a draft counts as a miss), the keyword baseline fires more often, 56 vs 32 (discordant 34 vs 10, exact McNemar p = 0.0004). After the budget gate the two cannot be told apart, 35 vs 32 of 98 (discordant 22 vs 19, p = 0.76), while the keyword drafts cost 126,768 benign alerts. On the 58 datasets where both drafted: 39 vs 22 (p = 1.5e-5) and 26 vs 22 within budget (p = 0.52). That trade-off is why the human review gate exists. The LLM backend is implemented but not benchmarked (see Limitations).
pySigma conversion of the 2,861 Windows rules succeeds for 2,857 (99.9% [99.6, 99.9]) on Splunk, 2,855 (99.8% [99.5, 99.9]) on Elastic, 2,842 (99.3% [99.0, 99.6]) on SQLite and 2,074 (72.5% [70.8, 74.1]) on Microsoft XDR KQL. For KQL, 632 rules have a log source with no XDR table and 119 use fields the pipeline cannot map.
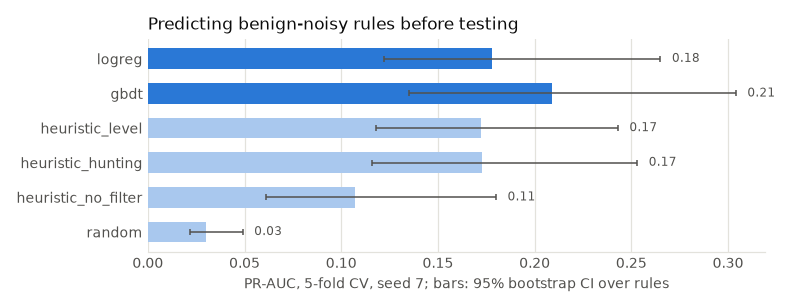
FP prediction from static rule features (75 noisy rules of 2,789), seed-7 cross-validation with bootstrap 95% CIs over rules: logistic regression ROC-AUC 0.831 [0.776, 0.881], PR-AUC 0.178 [0.122, 0.265]; GBDT ROC-AUC 0.824 [0.768, 0.871], PR-AUC 0.209 [0.135, 0.304]. A one-line level heuristic scores ROC-AUC 0.853 [0.808, 0.894] and PR-AUC 0.172 [0.118, 0.243]. (Means over 10 CV seeds: logreg 0.829 / 0.183, GBDT 0.830 / 0.231.) The paired bootstrap puts the PR-AUC difference against the heuristic at [-0.051, 0.083] for logreg and [-0.037, 0.120] for GBDT. With 75 positives, no scorer can be told apart from the heuristic. Treat the models as a review-order aid only.
Comparison with reference and published numbers
Each row states whether the comparison is like-for-like.
| reference | their result | ANVIL on the same input | like-for-like? |
|---|---|---|---|
SigmaHQ regression CI at 07ec293 (evtx-sigma-checker + SigmaHQ's json_matcher v0.0.2, run as json_checker), run 36187990502 |
all cases pass (green) | 463/463 | yes: same captures and expected counts |
| SigmaHQ goodlog CI on evtx-baseline win10, win11 and 2022 DC, non-low rules, run 36187990423 | 0 unexcused rules (green) | 8 non-low rules fire without a known-FPs.csv entry (2 medium, 6 informational) |
partly: same images and rules, but ANVIL excuses per rule id, which is more lenient than SigmaHQ's MatchString filters, so the 8 are a lower bound on rules where ANVIL fires and evtx-sigma-checker does not |
GAUNTLET v1.1.0 (sister project, tag cd41fa8), OTRF recordings detected at technique-family level |
sigma-all (SigmaHQ release package r2026-07-01, 2,519 rules): 67/98, 68.4% [58.6, 76.7]; sigma-full (adds low-level and threat-hunting rules, 2,805): 73/98, 74.5% [65.0, 82.1] | lenient column: 69/98, 70.4% [60.7, 78.5] (strict 62/98) | partly: the same 98 recordings and the same family-level match (ANVIL's lenient column), but different rule sets (release package r2026-07-01 vs repo commit 07ec293, 2,844 routable Windows rules, all levels). GAUNTLET v1.0.0 reported 67/96 (69.8%) before two AV-blocked recordings were added |
| Decay / breakage prediction for detection rules | no published benchmark found | Section 1 | n/a |
| LLM Sigma generation from CTI: AutoSigma (arXiv 2608.19011), CTI-REALM (arXiv 2603.13517) | rule validity and coverage on cloud blogs / agent tasks | drafts scored by execution on their own emulation | no: different corpora and metrics |
| AMIDES (Uetz et al., USENIX Security 2024, arXiv 2311.10197) | evasion of process-creation rules | - | no: it measures adversarial evasion, not benign volume or recall |
Full summary
Every table generated from results/*.json (results/SUMMARY.md)
Generated by python benchmarks/bench.py report from results/*.json. All result files come from bench run 37093721154 at commit 9906b42. Proportions are k/n, p% [95% Wilson CI].
SigmaHQ corpus lint
| rules | windows | compiled | unsupported | with regression test | test/stable w/o regression test | rules with lint errors |
|---|---|---|---|---|---|---|
| 3757 | 2861 | 3755 | 2 | 460 | 3029 | 0 |
| finding | count |
|---|---|
| W209 | 3029 |
| W205 | 2826 |
| W203 | 468 |
| W206 | 46 |
| W204 | 27 |
| W213 | 3 |
| W210 | 2 |
Aggregations and correlations at the pinned commit: unsupported/ holds 87 rules, 45 with count() and 54 with any aggregation in the condition; deprecated/ has 1 count() rule; the rule folders have none; 0 correlation: documents in total.
TP replay (recall) on SigmaHQ regression captures
TP-only check, and the development acceptance set: over-matching is detectable in only a few captures.
463 regression cases (499 real events); 0 samples unreadable.
| engine | detected | missed | could not evaluate | detection rate |
|---|---|---|---|---|
| ANVIL engine (1.x) | 463 | 0 | 0 | 463/463, 100.0% [99.2, 100.0] |
| ANVIL 0.1 (baseline) | 420 | 14 | 29 | 420/463, 90.7% [87.7, 93.0] |
| pySigma -> SQLite | 461 | 1 | 1 | 461/463, 99.6% [98.4, 99.9] |
ANVIL vs pySigma->SQLite: agree on 461 cases, disagree on 1.
- Local Network Connection Initiated By Script Interpreter: ANVIL 1, SQLite 0, expected 1
Benign sample (1800 events): ANVIL 1.x raised 15 alerts from 2 rules with 44,084 rule evaluations; the same 1.x engine with routing disabled raised 163 alerts from 16 rules with 5,119,200 evaluations; the 0.1 engine (no routing, older value semantics) raised 163 alerts from 16 rules with 5,149,800 evaluations.
Benign replay (false positives)
2,994,137 events, 2.55 host-days of clean Windows 10/11/Server 2022 AD telemetry (install-day recordings); 2789 of 2844 Windows rules have their log source present. Budget: 20 alerts per host-day per rule (10% of a 200/day SOC).
| observable rules firing | alerts | rules over budget (1 host) | events / CPU-second |
|---|---|---|---|
| 75/2789, 2.7% [2.2, 3.4] | 13249 | 12 | 3720 |
Rates are alerts per host-day. Rules over the 20/day budget when the per-host rate is projected to a fleet:
| hosts | rules over budget |
|---|---|
| 1 | 12 |
| 3 | 26 |
| 10 | 41 |
| 100 | 75 |
| 1000 | 75 |
| status | observable | fired | over budget |
|---|---|---|---|
| experimental | 217 | 5/217, 2.3% [1.0, 5.3] | 1 |
| stable | 73 | 4/73, 5.5% [2.2, 13.3] | 0 |
| test | 2499 | 66/2499, 2.6% [2.1, 3.3] | 11 |
| folder | observable | fired | over budget |
|---|---|---|---|
| core | 2353 | 53/2353, 2.3% [1.7, 2.9] | 5 |
| emerging-threats | 316 | 2/316, 0.6% [0.2, 2.3] | 1 |
| threat-hunting | 120 | 20/120, 16.7% [11.1, 24.3] | 6 |
| level | observable | fired | over budget |
|---|---|---|---|
| critical | 128 | 0/128, 0.0% [0.0, 2.9] | 0 |
| high | 1353 | 5/1353, 0.4% [0.2, 0.9] | 0 |
| informational | 13 | 6/13, 46.2% [23.2, 70.9] | 2 |
| low | 199 | 40/199, 20.1% [15.1, 26.2] | 9 |
| medium | 1096 | 24/1096, 2.2% [1.5, 3.2] | 1 |
Cross-check with SigmaHQ's known-FPs.csv (per rule id, MatchString filters not applied; the list was also used during development): 27/29, 93.1% [78.0, 98.1] of the medium+ rules ANVIL saw firing are on the list.
SigmaHQ's goodlog CI is green on the same images, so these 8 non-low rules that fire in ANVIL but are not excused by the list are rules where ANVIL fires and the reference checker does not (a lower bound: per-id excusing is more lenient than MatchString filtering):
- User Logoff Event (informational, 35 hits)
- Windows Update Error (informational, 3 hits)
- New PowerShell Instance Created (informational, 19 hits)
- Suspicious Non PowerShell WSMAN COM Provider (medium, 11 hits)
- Suspicious High IntegrityLevel Conhost Legacy Option (informational, 128 hits)
- New Application in AppCompat (informational, 141 hits)
- Windows Spooler Service Suspicious Binary Load (informational, 19 hits)
- Uncommon PowerShell Hosts (medium, 11 hits)
Reverse direction: 32 of 68 listed rules fire here (the list covers 7 images, ANVIL replays 3).
Top noisy rules:
| rule | level | status | folder | alerts | per day | gate |
|---|---|---|---|---|---|---|
| Scheduled Task Created - Registry | low | test | threat-hunting | 5513 | 2161.11 | fail |
| Shell Context Menu Command Tampering | low | test | threat-hunting | 4282 | 1678.56 | fail |
| EVTX Created In Uncommon Location | medium | test | core | 876 | 343.39 | fail |
| System Drawing DLL Load | low | test | threat-hunting | 608 | 238.34 | fail |
| Successful MSIX/AppX Package Installation | low | experimental | threat-hunting | 511 | 200.31 | fail |
| Potential Raspberry Robin Registry Set Internet Settings ZoneMap | low | test | emerging-threats | 200 | 78.4 | fail |
| New Application in AppCompat | informational | test | core | 141 | 55.27 | fail |
| Suspicious High IntegrityLevel Conhost Legacy Option | informational | test | core | 128 | 50.18 | fail |
| Modification of IE Registry Settings | low | test | core | 119 | 46.65 | fail |
| Scheduled Task Created - FileCreation | low | test | threat-hunting | 82 | 32.14 | fail |
| Potential Defense Evasion Via Raw Disk Access By Uncommon Tools | low | test | core | 72 | 28.22 | fail |
| Firewall Rule Modified In The Windows Firewall Exception List | low | test | threat-hunting | 62 | 24.3 | fail |
| BITS Client BitsProxy DLL Loaded By Uncommon Process | low | experimental | threat-hunting | 49 | 19.21 | pass |
| Potential Executable Run Itself As Sacrificial Process | low | experimental | threat-hunting | 43 | 16.86 | pass |
| Signed DLL Loaded With Missing PE Version Metadata | low | experimental | threat-hunting | 41 | 16.07 | pass |
Emulated attacks (OTRF Security-Datasets)
Technique detected = a rule tagged with the dataset technique or its parent fired (sibling sub-techniques do not count; they are credited only in the lenient column).
| datasets | events | any alert | technique claimed by a rule | technique detected | lenient (siblings credited) |
|---|---|---|---|---|---|
| 98 | 754,764 | 95/98, 97% [91, 99] | 90 | 62/98, 63% [53, 72] | 69/98, 70% [61, 79] |
| APT29 evaluation capture | events | rules fired | alerts | distinct technique tags on fired rules |
|---|---|---|---|---|
| syslog_auoms_auditd_log4shell_cve2021_44228_jndi_reference.zip | 50 | 0 | 0 | 0 |
| syslog_sysmon_log4shell_cve2021_44228_jndi_reference.zip | 93 | 4 | 5 | 4 |
| apt29_evals_day1_manual.zip | 196,081 | 111 | 3765 | 69 |
| apt29_evals_day2_manual.zip | 587,286 | 117 | 4723 | 70 |
ATT&CK coverage (Enterprise 19.2, Windows)
| view | techniques | tagged | validated | parent techniques validated |
|---|---|---|---|---|
| claimed | 474 | 299/474, 63.1% [58.6, 67.3] | 299/474, 63.1% [58.6, 67.3] | 137/176 |
| tp_validated | 474 | 299/474, 63.1% [58.6, 67.3] | 164/474, 34.6% [30.5, 39.0] | 89/176 |
| tp_validated_and_gated | 474 | 299/474, 63.1% [58.6, 67.3] | 164/474, 34.6% [30.5, 39.0] | 89/176 |
Decay monitor under telemetry changes
Field inventory: benign evtx-baseline only (no TP captures). False-alarm floor on unchanged telemetry: 183 rules (6.4%) are already broken/source-missing and are excluded; 3 of them are TP-validated.
- WMI Event Subscription (source-missing; missing -)
- Important Scheduled Task Deleted/Disabled (broken; missing TaskName)
- RedSun - TieringEngineService.exe Detected as EICAR Test File (broken; missing Path, ProcessName, SourceName, ThreatName)
Simulated changes (ground truth: the change applied to each TP-validated rule's regression captures; the same transform builds the post-change benign inventory):
| change | TP rules that stop firing | method | recall | precision | library flagged |
|---|---|---|---|---|---|
| ecs_rename | 430 | symbolic (ANVIL) | 426/430, 99.1% [97.6, 99.6] | 426/426, 100.0% [99.1, 100.0] | 2285 |
| ecs_rename | 430 | field presence, per source | 430/430, 100.0% [99.1, 100.0] | 430/435, 98.9% [97.3, 99.5] | 2365 |
| ecs_rename | 430 | field presence, global | 430/430, 100.0% [99.1, 100.0] | 430/435, 98.9% [97.3, 99.5] | 2396 |
| sysmon_to_4688 | 115 | symbolic (ANVIL) | 109/115, 94.8% [89.1, 97.6] | 109/109, 100.0% [96.6, 100.0] | 925 |
| sysmon_to_4688 | 115 | field presence, per source | 114/115, 99.1% [95.2, 99.8] | 114/272, 41.9% [36.2, 47.8] | 1593 |
| sysmon_to_4688 | 115 | field presence, global | 109/115, 94.8% [89.1, 97.6] | 109/266, 41.0% [35.2, 47.0] | 1547 |
| 4688_no_cmdline | 349 | symbolic (ANVIL) | 333/349, 95.4% [92.7, 97.2] | 333/333, 100.0% [98.9, 100.0] | 1865 |
| 4688_no_cmdline | 349 | field presence, per source | 347/349, 99.4% [97.9, 99.8] | 347/369, 94.0% [91.1, 96.0] | 2090 |
| 4688_no_cmdline | 349 | field presence, global | 342/349, 98.0% [95.9, 99.0] | 342/363, 94.2% [91.3, 96.2] | 2061 |
| 4688_no_cmdline_mixed | 349 | symbolic (ANVIL) | 109/349, 31.2% [26.6, 36.3] | 109/109, 100.0% [96.6, 100.0] | 925 |
| 4688_no_cmdline_mixed | 349 | field presence, per source | 252/349, 72.2% [67.3, 76.6] | 252/272, 92.6% [88.9, 95.2] | 1593 |
| 4688_no_cmdline_mixed | 349 | field presence, global | 247/349, 70.8% [65.8, 75.3] | 247/266, 92.9% [89.1, 95.4] | 1547 |
| no_commandline | 234 | symbolic (ANVIL) | 220/234, 94.0% [90.2, 96.4] | 220/220, 100.0% [98.3, 100.0] | 949 |
| no_commandline | 234 | field presence, per source | 233/234, 99.6% [97.6, 99.9] | 233/246, 94.7% [91.2, 96.9] | 1107 |
| no_commandline | 234 | field presence, global | 233/234, 99.6% [97.6, 99.9] | 233/246, 94.7% [91.2, 96.9] | 1118 |
| no_hashes | 0 | symbolic (ANVIL) | - | - | 6 |
| no_hashes | 0 | field presence, per source | - | 0/7, 0.0% [0.0, 35.4] | 47 |
| no_hashes | 0 | field presence, global | - | 0/7, 0.0% [0.0, 35.4] | 54 |
Exact McNemar tests, symbolic vs each presence check on the same rules (discordant counts symbolic-only / baseline-only):
| change | vs | false alarms on unbroken TP rules | flags on broken TP rules |
|---|---|---|---|
| ecs_rename | field presence, per source | 0 / 5 of 30, p = 0.062 | 0 / 4 of 430, p = 0.12 |
| ecs_rename | field presence, global | 0 / 5 of 30, p = 0.062 | 0 / 4 of 430, p = 0.12 |
| sysmon_to_4688 | field presence, per source | 0 / 158 of 345, p = 5.5e-48 | 0 / 5 of 115, p = 0.062 |
| sysmon_to_4688 | field presence, global | 0 / 157 of 345, p = 1.1e-47 | 5 / 5 of 115, p = 1.00 |
| 4688_no_cmdline | field presence, per source | 0 / 22 of 111, p = 4.8e-07 | 0 / 14 of 349, p = 1.2e-04 |
| 4688_no_cmdline | field presence, global | 0 / 21 of 111, p = 9.5e-07 | 5 / 14 of 349, p = 0.064 |
| 4688_no_cmdline_mixed | field presence, per source | 0 / 20 of 111, p = 1.9e-06 | 0 / 143 of 349, p = 1.8e-43 |
| 4688_no_cmdline_mixed | field presence, global | 0 / 19 of 111, p = 3.8e-06 | 5 / 143 of 349, p = 3.2e-36 |
| no_commandline | field presence, per source | 0 / 13 of 226, p = 2.4e-04 | 0 / 13 of 234, p = 2.4e-04 |
| no_commandline | field presence, global | 0 / 13 of 226, p = 2.4e-04 | 0 / 13 of 234, p = 2.4e-04 |
| no_hashes | field presence, per source | 0 / 7 of 460, p = 0.016 | 0 / 0 of 0, p = 1.00 |
| no_hashes | field presence, global | 0 / 7 of 460, p = 0.016 | 0 / 0 of 0, p = 1.00 |
Real Sysmon removal (no simulator): 88 OTRF captures that log both Sysmon EID 1 (1,434 events) and native Security 4688 (1,869). 286 Windows rules fire on them; 122 fire on none once the Sysmon channel is dropped. Predictions come from the benign inventory:
| inventory | method | recall | precision | false alarms |
|---|---|---|---|---|
| native 4688 | symbolic (ANVIL) | 114/122, 93.4% [87.6, 96.6] | 114/114, 100.0% [96.7, 100.0] | 0 |
| native 4688 | field presence, per source | 119/122, 97.5% [93.0, 99.2] | 119/182, 65.4% [58.2, 71.9] | 63 |
| native 4688 | field presence, global | 115/122, 94.3% [88.6, 97.2] | 115/177, 65.0% [57.7, 71.6] | 62 |
| simulated | symbolic (ANVIL) | 114/122, 93.4% [87.6, 96.6] | 114/114, 100.0% [96.7, 100.0] | 0 |
| simulated | field presence, per source | 119/122, 97.5% [93.0, 99.2] | 119/182, 65.4% [58.2, 71.9] | 63 |
| simulated | field presence, global | 115/122, 94.3% [88.6, 97.2] | 115/177, 65.0% [57.7, 71.6] | 62 |
Both inventories flag exactly the same rules: the benign hosts' native 4688 events carry the same per-source field set as the simulated conversion, so here the simulator and the real inventory agree; only the ground truth differs from the simulated rows above.
| inventory | symbolic vs | false alarms (symbolic-only / baseline-only) | flags on broken rules (symbolic-only / baseline-only) |
|---|---|---|---|
| native 4688 | field presence, per source | 0 / 63, p = 2.2e-19 | 0 / 5, p = 0.062 |
| native 4688 | field presence, global | 0 / 62, p = 4.3e-19 | 5 / 6, p = 1.00 |
| simulated | field presence, per source | 0 / 63, p = 2.2e-19 | 0 / 5, p = 0.062 |
| simulated | field presence, global | 0 / 62, p = 4.3e-19 | 5 / 6, p = 1.00 |
native 4688: missed e.g. WMI Event Subscription; Security Event Logging Disabled via MiniNt Registry Key - Process; ADS Zone.Identifier Deleted; UNC2452 Process Creation Patterns; false alarms e.g. -.
simulated: missed e.g. WMI Event Subscription; Security Event Logging Disabled via MiniNt Registry Key - Process; ADS Zone.Identifier Deleted; UNC2452 Process Creation Patterns; false alarms e.g. -.
SIEM conversion (pySigma)
| target | converted (of Windows rules) | seconds | errors |
|---|---|---|---|
| splunk | 2857/2861, 99.9% [99.6, 99.9] | 5.4 | SigmaFeatureNotSupportedByBackendError: 2; SigmaPlaceholderError: 2 |
| elastic | 2855/2861, 99.8% [99.5, 99.9] | 6.0 | SigmaFeatureNotSupportedByBackendError: 4; SigmaPlaceholderError: 2 |
| kusto | 2074/2861, 72.5% [70.8, 74.1] | 6.3 | SigmaTransformationError (log source has no table): 632; SigmaTransformationError (field cannot be mapped): 119; InvalidHashAlgorithmError: 28; : 5; NotImplementedError: 2; SigmaValueError: 1 |
| sqlite | 2842/2861, 99.3% [99.0, 99.6] | 6.4 | SigmaFeatureNotSupportedByBackendError: 17; SigmaPlaceholderError: 2 |
FP-prediction model
2789 observable rules, 75 noisy (rule fires at least once on the benign evtx-baseline corpus (observable rules only)). Point estimates from one CV run (seed 7); precision@k and recall use expected values under random tie-breaking.
| scorer | ROC-AUC | PR-AUC | precision at 75 | recall @ top 10% |
|---|---|---|---|---|
| logreg | 0.831 | 0.178 | 0.253 | 0.573 |
| gbdt | 0.824 | 0.209 | 0.28 | 0.533 |
| heuristic_level | 0.853 | 0.172 | 0.246 | 0.633 |
| heuristic_hunting | 0.852 | 0.173 | 0.242 | 0.641 |
| heuristic_no_filter | 0.524 | 0.107 | 0.202 | 0.394 |
| random | 0.5 | 0.03 | 0.053 | 0.12 |
Repeated 5-fold CV over 10 seeds (mean [interval over CV repetitions only, not over rules]):
| scorer | ROC-AUC | PR-AUC | precision at 75 |
|---|---|---|---|
| logreg | 0.829 [0.819, 0.838] | 0.183 [0.172, 0.194] | 0.259 [0.237, 0.280] |
| gbdt | 0.830 [0.820, 0.840] | 0.231 [0.218, 0.244] | 0.299 [0.279, 0.318] |
| heuristic_level | 0.853 [0.853, 0.853] | 0.172 [0.172, 0.172] | 0.246 [0.246, 0.246] |
| heuristic_hunting | 0.852 [0.852, 0.852] | 0.173 [0.173, 0.173] | 0.242 [0.242, 0.242] |
| heuristic_no_filter | 0.524 [0.524, 0.524] | 0.107 [0.107, 0.107] | 0.202 [0.202, 0.202] |
| random | 0.493 [0.469, 0.516] | 0.029 [0.027, 0.032] | 0.035 [0.022, 0.047] |
Bootstrap over rules (1000 resamples, seed-7 out-of-fold scores), paired against heuristic_level. The last column counts resamples with a PR-AUC difference <= 0 (a one-sided bootstrap tail; 1000/1000 means p > 0.999 for 'better than the reference').
| scorer | ROC-AUC 95% CI | PR-AUC 95% CI | dPR-AUC vs ref 95% CI | resamples with d <= 0 |
|---|---|---|---|---|
| logreg | [0.776, 0.881] | [0.122, 0.265] | [-0.051, 0.083] | 377/1000 |
| gbdt | [0.768, 0.871] | [0.135, 0.304] | [-0.037, 0.120] | 146/1000 |
| heuristic_level | [0.808, 0.894] | [0.118, 0.243] | - | - |
| heuristic_hunting | [0.807, 0.894] | [0.116, 0.253] | [-0.056, 0.059] | 501/1000 |
| heuristic_no_filter | [0.426, 0.625] | [0.061, 0.180] | [-0.102, -0.030] | 1000/1000 |
| random | [0.427, 0.565] | [0.022, 0.049] | [-0.210, -0.085] | 1000/1000 |
Drafter: CTI text -> rule -> tested
| backend | drafts | datasets with a draft (readable) | fires on its emulation | fires and within budget | datasets with benign FPs | benign alerts |
|---|---|---|---|---|---|---|
| heuristic | 90 | 68 | 32/68, 47.1% [35.7, 58.8] | 32 | 6 | 57 |
| keywords | 75 | 75 | 56/75, 74.7% [63.8, 83.1] | 35 | 33 | 126768 |
SigmaHQ on the same 68 datasets: any alert in 66, technique detected in 46.
Paired comparison on the same datasets (a dataset without a draft counts as a miss), exact McNemar:
| datasets | outcome | heuristic | keywords | discordant (heuristic-only / keywords-only) | p |
|---|---|---|---|---|---|
| all datasets | fires | 32/98, 33% [24, 42] | 56/98, 57% [47, 66] | 10 / 34 | 3.9e-04 |
| all datasets | fires within budget | 32/98, 33% [24, 42] | 35/98, 36% [27, 46] | 19 / 22 | 0.76 |
| datasets where both backends drafted | fires | 22/58, 38% [27, 51] | 39/58, 67% [54, 78] | 0 / 17 | 1.5e-05 |
| datasets where both backends drafted | fires within budget | 22/58, 38% [27, 51] | 26/58, 45% [33, 58] | 9 / 13 | 0.52 |
Linux and AWS CloudTrail (SigmaHQ linux + cloud/aws rules)
278 of 305 Linux/AWS rules routed; 168 labelled captures.
| source | captures | events | technique detected | any alert |
|---|---|---|---|---|
| auditd | 65 | 7,158 | 8/65, 12% [6, 22] | 19/65, 29% [20, 41] |
| cloudtrail | 40 | 27,793 | 6/40, 15% [7, 29] | 32/40, 80% [65, 90] |
| sysmon-linux | 63 | 551,655 | 13/63, 21% [12, 32] | 38/63, 60% [48, 71] |
| all | 168 | 27/168, 16% [11, 22] | 89/168, 53% [45, 60] |
Captures that parsed to 0 events: splunk:T1068/linux_dirtyfrag
Benign command emulation recorded on the CI runner (755 events: linux-auditd 697, linux-sysmon/operational 58): technique detected for 7/8, 88% [53, 98] emulated techniques (detected T1033, T1082, T1007, T1087.001, T1057, T1016, T1083; missed T1027); 10 Linux rules fired 17 alerts.
Benign Linux telemetry recorded on the CI runner (15,480 events: linux-auditd 12,662, linux-sysmon/operational 2,818; 0.003 h; venv + pip install (exit 0) + unit tests (exit 0) + git on the runner): 6 Linux rules fired 42 alerts. The window is too short to project a daily rate, so this is a smoke test of the Linux parsers and rules on benign activity, not an FP-rate estimate.
Real backend: OpenSearch 2.19.1 vs ANVIL
Rules converted by pySigma's OpenSearch Lucene backend with pySigma's own Sysmon + Windows log-source pipelines (independent of ANVIL's router), executed with _search in an OpenSearch container in CI.
| comparison | agree |
|---|---|
| regression captures: verdict | 450/458, 98.3% [96.6, 99.1] |
| regression captures: exact count | 450/458, 98.3% [96.6, 99.1] |
| benign sample: same matching events per rule | 2835/2836, 99.96% [99.80, 99.99] |
| benign sample: same events, rules that fire in either engine | 2/3, 67% [21, 94] |
Benign fire/no-fire table: {'both': 2, 'anvil_only': 0, 'opensearch_only': 1, 'neither': 2833}; Cohen's kappa 0.80 (bootstrap 95% CI [0.00, 1.00]). Disagreements by modifier: {'(plain)': 1}.
Query errors: regression 3, benign 19 ({'400 query_shard_exception': 21, '400 None': 1}); conversion errors {'SigmaFeatureNotSupportedByBackendError': 4}; values above Lucene's term limit (not indexed): {}.
| rule | set | HTTP | error type | reason |
|---|---|---|---|---|
| 63bf8794-9917-45bc-88dd-e1b5abc0ecfd | regression | 400 | query_shard_exception | failed to create query: Determinizing (copy-item|cpi) .{2,128} -destination .{1,32}\windows\(system32|syswow64) would require more than 10000 effort. |
| 589ac73f-8e12-409c-964e-31a2f5775ae2 | regression | 400 | query_shard_exception | failed to create query: Determinizing (?i).exe[\"\']?\s+[^\"]{0,64}werfaultsecure.exe[\"\']?\s+\d{2,10} would require more than 10000 effort. |
| bae7c70b-8569-44e9-accf-b30073da8a5d | regression | 400 | query_shard_exception | Failed to parse query [Channel:Microsoft-Windows-Sysmon\/Operational AND (EventID:1 AND ((Image:\node.exe AND (CommandLine:(install OR \ i\ *))) AND (Com |
| 7aaaf4b8-e47c-4295-92ee-6ed40a6f60c8 | benign | 400 | None | {"error":{"root_cause":[{"type":"query_shard_exception","reason":"Failed to parse query [Channel:Microsoft\-Windows\-Sysmon\/Operational AND (EventID:6 AND ( |
| 9ac8b09b-45de-4a07-9da1-0de8c09304a3 | benign | 400 | query_shard_exception | failed to create query: expected '"' at position 61 |
| 6bfb8fa7-b2e7-4f6c-8d9d-824e5d06ea9e | benign | 400 | query_shard_exception | failed to create query: expected '"' at position 86 |
| c72aca44-8d52-45ad-8f81-f96c4d3c755e | benign | 400 | query_shard_exception | failed to create query: expected '"' at position 60 |
| f3c89218-8c3d-4ba9-9974-f1d8e6a1b4a6 | benign | 400 | query_shard_exception | failed to create query: expected '"' at position 46 |
| 63bf8794-9917-45bc-88dd-e1b5abc0ecfd | benign | 400 | query_shard_exception | failed to create query: Determinizing (copy-item|cpi) .{2,128} -destination .{1,32}\windows\(system32|syswow64) would require more than 10000 effort. |
| 779c8c12-0eb1-11eb-adc1-0242ac120002 | benign | 400 | query_shard_exception | failed to create query: expected '"' at position 62 |
| 0adfbc14-0ed1-11eb-adc1-0242ac120002 | benign | 400 | query_shard_exception | failed to create query: expected '"' at position 86 |
| 86b896ba-ffa1-4fea-83e3-ee28a4c915c7 | benign | 400 | query_shard_exception | failed to create query: expected '"' at position 59 |
| e54f5149-6ba3-49cf-b153-070d24679126 | benign | 400 | query_shard_exception | failed to create query: expected '"' at position 46 |
| 27aec9c9-dbb0-4939-8422-1742242471d0 | benign | 400 | query_shard_exception | failed to create query: expected ')' at position 90 |
| 9c14c9fa-1a63-4a64-8e57-d19280559490 | benign | 400 | query_shard_exception | failed to create query: expected '"' at position 63 |
| 589ac73f-8e12-409c-964e-31a2f5775ae2 | benign | 400 | query_shard_exception | failed to create query: Determinizing (?i).exe[\"\']?\s+[^\"]{0,64}werfaultsecure.exe[\"\']?\s+\d{2,10} would require more than 10000 effort. |
| c83bf4b5-cdf0-437c-90fa-43d734f7c476 | benign | 400 | query_shard_exception | failed to create query: expected '>' at position 7 |
| dd8756e7-a3a0-4768-b47e-8f545d1a751c | benign | 400 | query_shard_exception | failed to create query: invalid character class \110 |
| cb5a2333-56cf-4562-8fcb-22ba1bca728d | benign | 400 | query_shard_exception | failed to create query: invalid character class \98 |
| 56d19cb4-6414-4769-9644-1ed35ffbb148 | benign | 400 | query_shard_exception | failed to create query: invalid character class \98 |
| bae7c70b-8569-44e9-accf-b30073da8a5d | benign | 400 | query_shard_exception | Failed to parse query [Channel:Microsoft-Windows-Sysmon\/Operational AND (EventID:1 AND ((Image:\node.exe AND (CommandLine:(install OR \ i\ *))) AND (Com |
| 064060aa-09fb-4636-817f-020a32aa7e9e | benign | 400 | query_shard_exception | failed to create query: Determinizing (get-item|gci|get-childitem).{1,64}-path.{1,64}\(currentcontrolset\services|currentversion\policies\explorer\run|curr |