Evaluation
All numbers come from python scripts/run_benchmarks.py, run by the bench GitHub Actions workflow
on the dataset snapshot in data/MANIFEST.json. Source of every number on this page: bench run
37092539472 on commit 2d7bacc (also printed at the top of the generated results
below). Commands and expected values: Reproduce. Protocol details:
ADR 0004.
Protocol in brief
- Leave-report-out. Before a case is attributed, every group edge whose citations are a subset of the case's own citations is removed (A1-LF, R, G). Plain A1 is kept only as a leaky upper bound.
- Per-report cases (R). One case per (group, cited report) with at least 3 techniques: 637 cases over 161 groups; 5-fold by report, and a temporal split: every citation dated 2022 or later is removed from the profiles (date from the citation's reference description "(YYYY, Month DD)", else from a year in its key) and the 219 cases from 2022+ reports are attributed. A sensitivity run also removes the 83 citations with no recoverable date.
- Commitment rule. Baselines commit only on a unique top score (ties abstain); DRAGNET commits at MEDIUM+, and its LOW verdicts are counted separately as "wrong actor named (any grade)".
- Uncertainty. Exact Clopper-Pearson intervals for proportions; bootstrap CIs for top-1 that resample the non-independent unit (threat groups for R, cases for the campaign sets, families for genetics, actors for G). Paired differences: sign-flip test, exact when at most 20 discordant units, otherwise Monte Carlo with B = 200,000 sign flips and p = (k+1)/(B+1) (never reported as 0); on R the test flips whole groups, matching the clustered CIs; Holm correction across methods.
- Genetics (E2/E3, B3). Time split at 2024-01-01; collision filters and the TLSH radius use pre-cutoff or validation data only; results per family and with WannaCry excluded.
- Published comparison (G). Guru, Moss & Kochenderfer (2025) adapted to ATT&CK human-curated per-report technique lists; an adaptation, not a reproduction (the paper picks the best of 10 weight matrices on validation; we report every split).
What the results say
- On leakage-controlled per-report cases DRAGNET beats every single-signal and TTP baseline on top-1: 5-fold 0.454 [0.401, 0.507] vs at most 0.310 (group-clustered Holm p = 5.0e-5, Monte Carlo with B = 200,000); temporal 0.137 [0.078, 0.214] vs at most 0.078 (Holm p <= 0.010).
- The gain comes from fusing techniques with software (+0.095 [0.064, 0.130] over software-only, p = 5.0e-6, B = 200,000) and from specificity weighting (+0.025 [0.003, 0.048], Holm p = 0.041).
- The ablation without the TTP-profile term scores higher on 5-fold top-1 (0.487 vs 0.454, not significant with group clustering: two-sided p = 0.088), and the temporal split does not decide it.
- On the 25 campaigns, with leakage removed, the edge over IOC correlation (+0.046 [-0.027, 0.147]) is not significant (exact p = 0.25).
- Tradecraft-only LOW verdicts are unreliable (A3 0/10; R-temporal LOW 18/40); MEDIUM verdicts are reliable (R 5-fold: 79/83, 0.95 [0.88, 0.99]).
- The false-flag rules matter only when a hard decoy anchor is planted (level 2: -0.23 [-0.37, -0.11]).
- Imphash and TLSH genetics are precise but rare anchors, mostly re-identify commodity families, and DRAGNET does not beat a plain lookup on them.
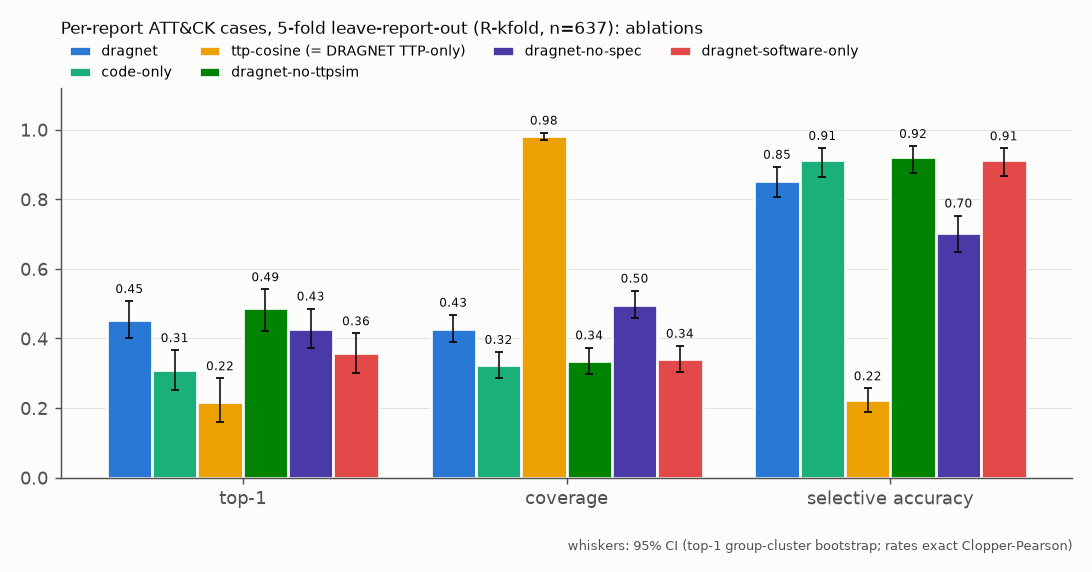
Figure 1. Per-report cases, 5-fold: top-1, coverage and selective accuracy of DRAGNET, its ablations and two baselines, with 95% CIs (top-1 group-cluster bootstrap, rates Clopper-Pearson).
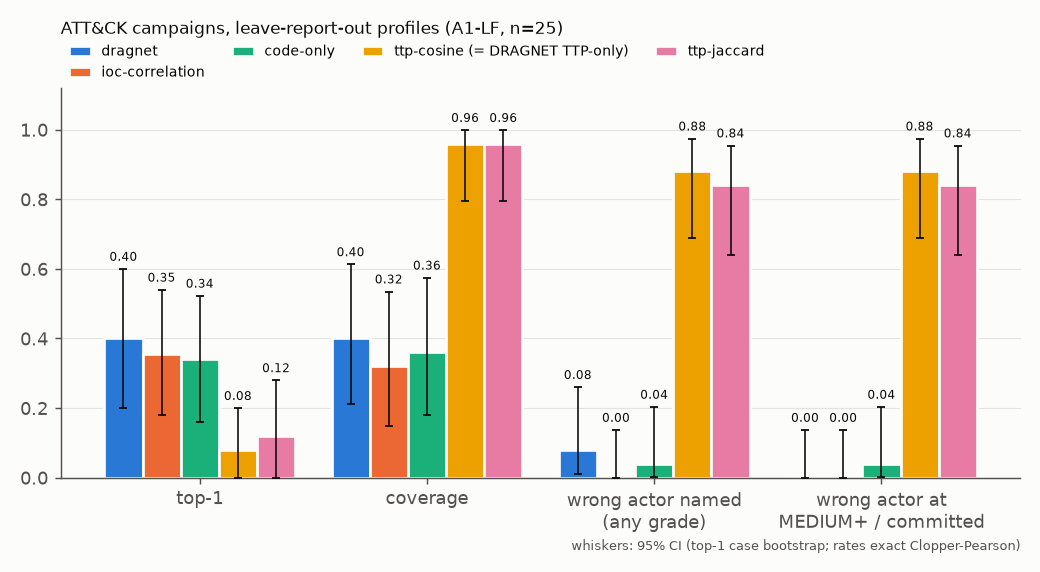
Figure 2. The 25 campaigns with leave-report-out profiles: top-1, coverage and wrong commitments per method, with 95% CIs.
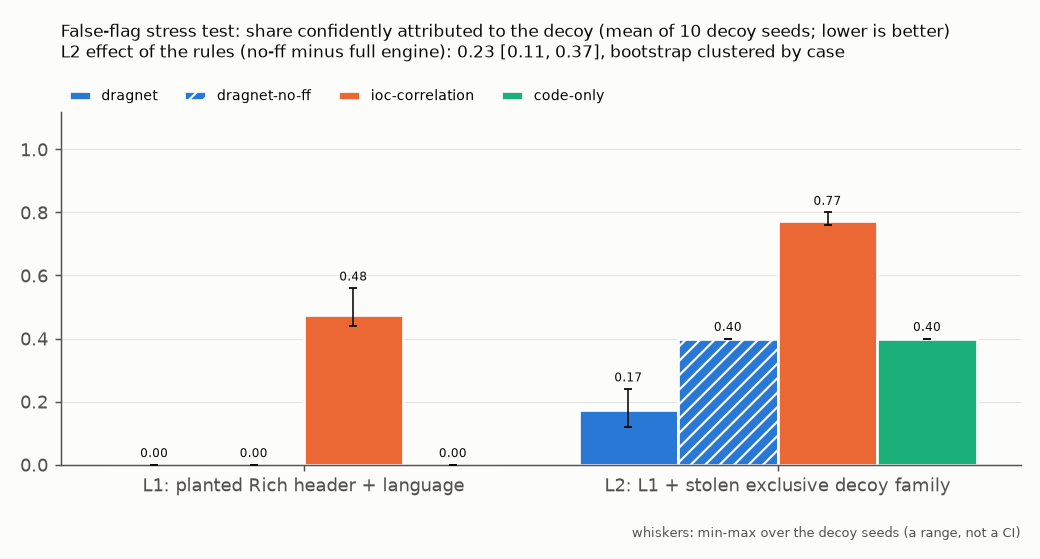
Figure 3. Confident decoy attributions at decoy levels 1 and 2, mean over 10 decoy seeds (whiskers: seed range), with the rules' level-2 effect and its case-clustered CI.
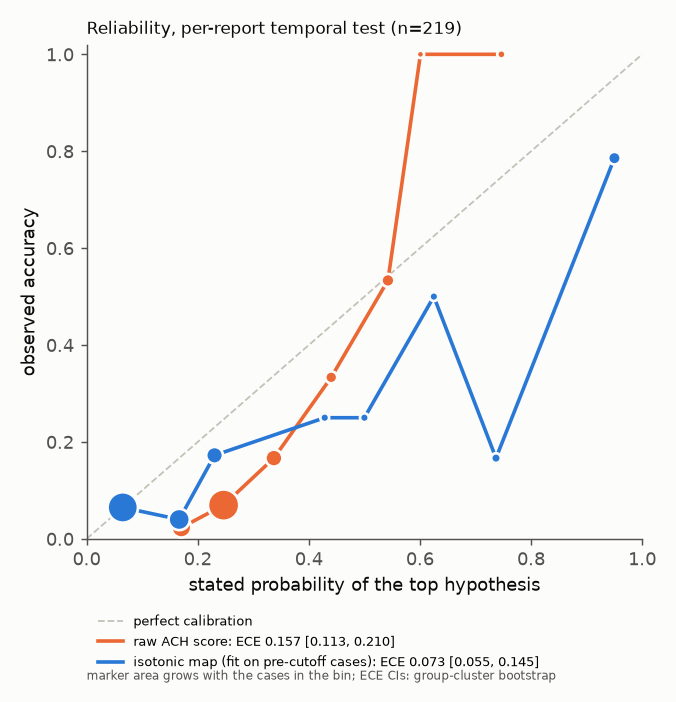
Figure 4. Reliability of DRAGNET's top-hypothesis score on the temporal test set, raw and after the isotonic map fitted on pre-2022 cases (ECE with group-cluster bootstrap CIs).
Full generated results
Generated by python scripts/run_benchmarks.py; do not edit by hand.
Source: bench run 37092539472 on commit 2d7bacc (2026-10-03, Python 3.12.14, PYTHONHASHSEED=0).
Knowledge graph: MITRE ATT&CK Enterprise v19.2 - 176 groups, 1600 distinct signal keys, 117 groups with a MISP sponsor-state mapping.
Conventions. A baseline commits to an actor only when that actor is its unique top score (a tie at the top is an abstention); 'wrong if ties broken at random' scores the alternative convention in expectation. DRAGNET commits at MEDIUM or HIGH; 'wrong actor named (any grade)' also counts its LOW verdicts. Ranking metrics score ties in expectation.
A1-LF - ATT&CK campaigns, leave-report-out profiles (headline protocol)
Before each campaign is attributed, every group 'uses' edge whose citations are a subset of the campaign's own citations is removed (mean 3.680 edges per case). This prevents profiles written from the campaign's own reports from answering the question.
| method | n | top-1 | coverage | selective acc. | wrong actor named (any grade) | wrong at MEDIUM+ / committed | wrong if ties broken at random |
|---|---|---|---|---|---|---|---|
| dragnet | 25 | 0.400 | 0.400 | 0.800 | 0.080 | 0.000 | 0.000 |
| ttp-jaccard | 25 | 0.120 | 0.960 | 0.125 | 0.840 | 0.840 | 0.840 |
| ttp-cosine | 25 | 0.080 | 0.960 | 0.083 | 0.880 | 0.880 | 0.880 |
| ttp-binary-bayes | 25 | 0.000 | 0.760 | 0.000 | 0.760 | 0.760 | 0.960 |
| ioc-correlation | 25 | 0.354 | 0.320 | 1.000 | 0.000 | 0.000 | 0.326 |
| code-only | 25 | 0.341 | 0.360 | 0.889 | 0.040 | 0.040 | 0.099 |
95% intervals (A1-LF): top-1 by case bootstrap; proportions exact Clopper-Pearson.
| method | top-1 | coverage | selective acc. | wrong (any grade) | wrong at MEDIUM+ / committed |
|---|---|---|---|---|---|
| dragnet | 0.400 [0.200, 0.600] | 0.400 [0.211, 0.613] | 0.800 [0.444, 0.975] | 0.080 [0.010, 0.260] | 0.000 [0.000, 0.137] |
| ttp-jaccard | 0.120 [0.000, 0.280] | 0.960 [0.796, 0.999] | 0.125 [0.027, 0.324] | 0.840 [0.639, 0.955] | 0.840 [0.639, 0.955] |
| ttp-cosine | 0.080 [0.000, 0.200] | 0.960 [0.796, 0.999] | 0.083 [0.010, 0.270] | 0.880 [0.688, 0.975] | 0.880 [0.688, 0.975] |
| ttp-binary-bayes | 0.000 [0.000, 0.000] | 0.760 [0.549, 0.906] | 0.000 [0.000, 0.176] | 0.760 [0.549, 0.906] | 0.760 [0.549, 0.906] |
| ioc-correlation | 0.354 [0.180, 0.540] | 0.320 [0.149, 0.535] | 1.000 [0.631, 1.000] | 0.000 [0.000, 0.137] | 0.000 [0.000, 0.137] |
| code-only | 0.341 [0.161, 0.523] | 0.360 [0.180, 0.575] | 0.889 [0.518, 0.997] | 0.040 [0.001, 0.204] | 0.040 [0.001, 0.204] |
Paired top-1 difference, DRAGNET minus method (A1-LF): case bootstrap 95% CI. Sign-flip test (one-sided, DRAGNET better): exact when at most 20 discordant units, otherwise Monte Carlo with B = 200,000 sign flips, p = (k+1)/(B+1); Holm-adjusted across methods.
| method | diff | 95% CI | discordant cases | p (one-sided) | p (Holm) | p (two-sided) |
|---|---|---|---|---|---|---|
| ttp-jaccard | 0.280 | [0.120, 0.480] | 7 | 0.008 (exact) | 0.047 | 0.016 |
| ttp-cosine | 0.320 | [0.160, 0.520] | 8 | 0.004 (exact) | 0.027 | 0.008 |
| ttp-binary-bayes | 0.400 | [0.200, 0.600] | 10 | 9.8e-04 (exact) | 0.008 | 0.002 |
| ioc-correlation | 0.046 | [-0.027, 0.147] | 4 | 0.250 (exact) | 1.000 | 0.500 |
| code-only | 0.059 | [-0.003, 0.159] | 3 | 0.250 (exact) | 1.000 | 0.500 |
| dragnet-no-spec | 0.040 | [0.000, 0.120] | 1 | 0.500 (exact) | 1.000 | 1.000 |
| dragnet-no-ttpsim | 0.040 | [0.000, 0.120] | 1 | 0.500 (exact) | 1.000 | 1.000 |
| dragnet-no-ff | 0.000 | [0.000, 0.000] | 0 | 1.000 (exact) | 1.000 | 1.000 |
DRAGNET verdicts by stated grade (A1-LF), exact 95% CI:
| grade | n named | correct | accuracy [95% CI] |
|---|---|---|---|
| HIGH | 0 | 0 | n/a [n/a, n/a] |
| MEDIUM | 3 | 3 | 1.000 [0.292, 1.000] |
| LOW | 7 | 5 | 0.714 [0.290, 0.963] |
Selective risk (error rate among the most confident cases) at fixed coverage, A1-LF; ties in confidence resolved in expectation. Lower is better.
| method | risk @20% | risk @40% | risk @60% | risk @100% | AURC |
|---|---|---|---|---|---|
| dragnet | 0.000 | 0.200 | 0.333 | 0.600 | 0.281 |
| ttp-jaccard | 1.000 | 0.900 | 0.933 | 0.880 | 0.925 |
| ttp-cosine | 0.800 | 0.800 | 0.867 | 0.920 | 0.793 |
| ttp-binary-bayes | 1.000 | 1.000 | 1.000 | 1.000 | 1.000 |
| ioc-correlation | 0.200 | 0.300 | 0.411 | 0.646 | 0.367 |
| code-only | 0.200 | 0.150 | 0.431 | 0.659 | 0.367 |
Ablations (A1-LF)
| method | n | top-1 | coverage | selective acc. | wrong actor named (any grade) | wrong at MEDIUM+ / committed | wrong if ties broken at random |
|---|---|---|---|---|---|---|---|
| dragnet | 25 | 0.400 | 0.400 | 0.800 | 0.080 | 0.000 | 0.000 |
| dragnet-no-spec | 25 | 0.360 | 0.440 | 0.818 | 0.080 | 0.000 | 0.000 |
| dragnet-no-ttpsim | 25 | 0.360 | 0.360 | 0.889 | 0.040 | 0.000 | 0.000 |
| dragnet-no-ff | 25 | 0.400 | 0.400 | 0.800 | 0.080 | 0.000 | 0.000 |
Ranking and calibration (A1-LF):
| method | in KG | top-3 | top-5 | MRR | Brier (top-1) | ECE | Brier (dist.) |
|---|---|---|---|---|---|---|---|
| dragnet | 25 | 0.400 | 0.400 | 0.424 | 0.116 | 0.168 | 0.981 |
| ttp-jaccard | 25 | 0.160 | 0.160 | 0.172 | 0.116 | 0.102 | 0.990 |
| ttp-cosine | 25 | 0.200 | 0.240 | 0.184 | 0.076 | 0.061 | 0.987 |
| ttp-binary-bayes | 25 | 0.000 | 0.000 | 0.018 | 0.001 | 0.030 | 0.999 |
| ioc-correlation | 25 | 0.402 | 0.404 | 0.378 | 0.154 | 0.205 | 0.853 |
| code-only | 25 | 0.364 | 0.367 | 0.355 | 0.115 | 0.149 | 0.791 |
A1 - ATT&CK campaigns vs v19.2 group profiles (retrospective, leaky upper bound)
In 18 of 25 campaigns the true group's profile already lists at least one of the campaign's own software; 14 of DRAGNET's 14 correct named verdicts are among them. Read A1 as an upper bound; A1-LF is the controlled version.
| method | n | top-1 | coverage | selective acc. | wrong actor named (any grade) | wrong at MEDIUM+ / committed | wrong if ties broken at random |
|---|---|---|---|---|---|---|---|
| dragnet | 25 | 0.680 | 0.600 | 0.933 | 0.040 | 0.000 | 0.000 |
| ttp-jaccard | 25 | 0.120 | 0.960 | 0.125 | 0.840 | 0.840 | 0.840 |
| ttp-cosine | 25 | 0.080 | 0.960 | 0.083 | 0.880 | 0.880 | 0.880 |
| ttp-binary-bayes | 25 | 0.000 | 0.760 | 0.000 | 0.760 | 0.760 | 0.960 |
| ioc-correlation | 25 | 0.560 | 0.520 | 1.000 | 0.000 | 0.000 | 0.280 |
| code-only | 25 | 0.540 | 0.560 | 0.929 | 0.040 | 0.040 | 0.060 |
95% intervals (A1): top-1 by case bootstrap; proportions exact Clopper-Pearson.
| method | top-1 | coverage | selective acc. | wrong (any grade) | wrong at MEDIUM+ / committed |
|---|---|---|---|---|---|
| dragnet | 0.680 [0.480, 0.840] | 0.600 [0.387, 0.789] | 0.933 [0.681, 0.998] | 0.040 [0.001, 0.204] | 0.000 [0.000, 0.137] |
| ttp-jaccard | 0.120 [0.000, 0.280] | 0.960 [0.796, 0.999] | 0.125 [0.027, 0.324] | 0.840 [0.639, 0.955] | 0.840 [0.639, 0.955] |
| ttp-cosine | 0.080 [0.000, 0.200] | 0.960 [0.796, 0.999] | 0.083 [0.010, 0.270] | 0.880 [0.688, 0.975] | 0.880 [0.688, 0.975] |
| ttp-binary-bayes | 0.000 [0.000, 0.000] | 0.760 [0.549, 0.906] | 0.000 [0.000, 0.176] | 0.760 [0.549, 0.906] | 0.760 [0.549, 0.906] |
| ioc-correlation | 0.560 [0.381, 0.733] | 0.520 [0.313, 0.722] | 1.000 [0.753, 1.000] | 0.000 [0.000, 0.137] | 0.000 [0.000, 0.137] |
| code-only | 0.540 [0.360, 0.720] | 0.560 [0.349, 0.756] | 0.929 [0.661, 0.998] | 0.040 [0.001, 0.204] | 0.040 [0.001, 0.204] |
Paired top-1 difference, DRAGNET minus method (A1): case bootstrap 95% CI. Sign-flip test (one-sided, DRAGNET better): exact when at most 20 discordant units, otherwise Monte Carlo with B = 200,000 sign flips, p = (k+1)/(B+1); Holm-adjusted across methods.
| method | diff | 95% CI | discordant cases | p (one-sided) | p (Holm) | p (two-sided) |
|---|---|---|---|---|---|---|
| ttp-jaccard | 0.560 | [0.360, 0.760] | 14 | 6.1e-05 (exact) | 3.7e-04 | 1.2e-04 |
| ttp-cosine | 0.600 | [0.400, 0.760] | 15 | 3.1e-05 (exact) | 2.1e-04 | 6.1e-05 |
| ttp-binary-bayes | 0.680 | [0.480, 0.840] | 17 | 7.6e-06 (exact) | 6.1e-05 | 1.5e-05 |
| ioc-correlation | 0.120 | [0.019, 0.248] | 6 | 0.062 (exact) | 0.312 | 0.125 |
| code-only | 0.140 | [0.020, 0.280] | 4 | 0.062 (exact) | 0.312 | 0.125 |
| dragnet-no-spec | 0.080 | [0.000, 0.200] | 2 | 0.250 (exact) | 0.750 | 0.500 |
| dragnet-no-ttpsim | 0.080 | [0.000, 0.200] | 2 | 0.250 (exact) | 0.750 | 0.500 |
| dragnet-no-ff | 0.000 | [0.000, 0.000] | 0 | 1.000 (exact) | 1.000 | 1.000 |
DRAGNET verdicts by stated grade (A1), exact 95% CI:
| grade | n named | correct | accuracy [95% CI] |
|---|---|---|---|
| HIGH | 0 | 0 | n/a [n/a, n/a] |
| MEDIUM | 5 | 5 | 1.000 [0.478, 1.000] |
| LOW | 10 | 9 | 0.900 [0.555, 0.997] |
Ablations (A1)
| method | n | top-1 | coverage | selective acc. | wrong actor named (any grade) | wrong at MEDIUM+ / committed | wrong if ties broken at random |
|---|---|---|---|---|---|---|---|
| dragnet | 25 | 0.680 | 0.600 | 0.933 | 0.040 | 0.000 | 0.000 |
| dragnet-no-spec | 25 | 0.600 | 0.600 | 0.933 | 0.040 | 0.000 | 0.000 |
| dragnet-no-ttpsim | 25 | 0.600 | 0.560 | 0.929 | 0.040 | 0.000 | 0.000 |
| dragnet-no-ff | 25 | 0.680 | 0.600 | 0.933 | 0.040 | 0.000 | 0.000 |
Ranking and calibration (A1):
| method | in KG | top-3 | top-5 | MRR | Brier (top-1) | ECE | Brier (dist.) |
|---|---|---|---|---|---|---|---|
| dragnet | 25 | 0.680 | 0.680 | 0.688 | 0.162 | 0.276 | 0.892 |
| ttp-jaccard | 25 | 0.160 | 0.160 | 0.169 | 0.116 | 0.102 | 0.990 |
| ttp-cosine | 25 | 0.160 | 0.200 | 0.166 | 0.076 | 0.061 | 0.987 |
| ttp-binary-bayes | 25 | 0.000 | 0.000 | 0.018 | 0.001 | 0.030 | 0.999 |
| ioc-correlation | 25 | 0.620 | 0.633 | 0.595 | 0.173 | 0.216 | 0.643 |
| code-only | 25 | 0.560 | 0.560 | 0.550 | 0.145 | 0.184 | 0.623 |
A2 - stale profiles: v19.2 campaigns vs ATT&CK v10.1 (2021-11-10) group profiles
ATT&CK v10.1 has no campaign objects, so this is not a temporal hold-out of campaigns: it measures attribution against older, thinner profiles in an open world (groups added after v10.1 are unknown to the graph). The 'later' rows restrict to the 12 campaigns whose recorded activity (first_seen) began after the v10.1 release.
| method | n | top-1 | coverage | selective acc. | wrong actor named (any grade) | wrong at MEDIUM+ / committed | wrong if ties broken at random | out-of-KG abstain |
|---|---|---|---|---|---|---|---|---|
| dragnet | 25 | 0.412 | 0.529 | 0.778 | 0.160 | 0.000 | 0.000 | 0.750 |
| ttp-jaccard | 25 | 0.235 | 0.941 | 0.250 | 0.800 | 0.800 | 0.800 | 0.000 |
| ttp-cosine | 25 | 0.235 | 0.941 | 0.250 | 0.800 | 0.800 | 0.800 | 0.000 |
| ttp-binary-bayes | 25 | 0.000 | 0.706 | 0.000 | 0.760 | 0.760 | 0.960 | 0.125 |
| ioc-correlation | 25 | 0.405 | 0.471 | 0.750 | 0.080 | 0.080 | 0.365 | 1.000 |
| code-only | 25 | 0.360 | 0.412 | 0.857 | 0.080 | 0.080 | 0.155 | 0.875 |
95% intervals (A2): top-1 by case bootstrap; proportions exact Clopper-Pearson.
| method | top-1 | coverage | selective acc. | wrong (any grade) | wrong at MEDIUM+ / committed |
|---|---|---|---|---|---|
| dragnet | 0.412 [0.176, 0.647] | 0.529 [0.278, 0.770] | 0.778 [0.400, 0.972] | 0.160 [0.045, 0.361] | 0.000 [0.000, 0.137] |
| ttp-jaccard | 0.235 [0.059, 0.471] | 0.941 [0.713, 0.999] | 0.250 [0.073, 0.524] | 0.800 [0.593, 0.932] | 0.800 [0.593, 0.932] |
| ttp-cosine | 0.235 [0.059, 0.471] | 0.941 [0.713, 0.999] | 0.250 [0.073, 0.524] | 0.800 [0.593, 0.932] | 0.800 [0.593, 0.932] |
| ttp-binary-bayes | 0.000 [0.000, 0.000] | 0.706 [0.440, 0.897] | 0.000 [0.000, 0.265] | 0.760 [0.549, 0.906] | 0.760 [0.549, 0.906] |
| ioc-correlation | 0.405 [0.188, 0.631] | 0.471 [0.230, 0.722] | 0.750 [0.349, 0.968] | 0.080 [0.010, 0.260] | 0.080 [0.010, 0.260] |
| code-only | 0.360 [0.129, 0.596] | 0.412 [0.184, 0.671] | 0.857 [0.421, 0.996] | 0.080 [0.010, 0.260] | 0.080 [0.010, 0.260] |
DRAGNET verdicts by stated grade (A2), exact 95% CI:
| grade | n named | correct | accuracy [95% CI] |
|---|---|---|---|
| HIGH | 0 | 0 | n/a [n/a, n/a] |
| MEDIUM | 4 | 4 | 1.000 [0.398, 1.000] |
| LOW | 7 | 3 | 0.429 [0.099, 0.816] |
A2-later (activity began after v10.1)
| method | n | top-1 | coverage | selective acc. | wrong actor named (any grade) | wrong at MEDIUM+ / committed | wrong if ties broken at random | out-of-KG abstain |
|---|---|---|---|---|---|---|---|---|
| dragnet | 12 | 0.143 | 0.143 | 1.000 | 0.000 | 0.000 | 0.000 | 1.000 |
| ttp-jaccard | 12 | 0.143 | 1.000 | 0.143 | 0.917 | 0.917 | 0.917 | 0.000 |
| ttp-cosine | 12 | 0.143 | 1.000 | 0.143 | 0.917 | 0.917 | 0.917 | 0.000 |
| ttp-binary-bayes | 12 | 0.000 | 0.714 | 0.000 | 0.750 | 0.750 | 1.000 | 0.200 |
| ioc-correlation | 12 | 0.214 | 0.286 | 0.500 | 0.083 | 0.083 | 0.292 | 1.000 |
| code-only | 12 | 0.152 | 0.286 | 0.500 | 0.083 | 0.083 | 0.161 | 1.000 |
95% intervals (A2-later): top-1 by case bootstrap; proportions exact Clopper-Pearson.
| method | top-1 | coverage | selective acc. | wrong (any grade) | wrong at MEDIUM+ / committed |
|---|---|---|---|---|---|
| dragnet | 0.143 [0.000, 0.429] | 0.143 [0.004, 0.579] | 1.000 [0.025, 1.000] | 0.000 [0.000, 0.265] | 0.000 [0.000, 0.265] |
| ttp-jaccard | 0.143 [0.000, 0.429] | 1.000 [0.590, 1.000] | 0.143 [0.004, 0.579] | 0.917 [0.615, 0.998] | 0.917 [0.615, 0.998] |
| ttp-cosine | 0.143 [0.000, 0.429] | 1.000 [0.590, 1.000] | 0.143 [0.004, 0.579] | 0.917 [0.615, 0.998] | 0.917 [0.615, 0.998] |
| ttp-binary-bayes | 0.000 [0.000, 0.000] | 0.714 [0.290, 0.963] | 0.000 [0.000, 0.522] | 0.750 [0.428, 0.945] | 0.750 [0.428, 0.945] |
| ioc-correlation | 0.214 [0.000, 0.500] | 0.286 [0.037, 0.710] | 0.500 [0.013, 0.987] | 0.083 [0.002, 0.385] | 0.083 [0.002, 0.385] |
| code-only | 0.152 [0.000, 0.438] | 0.286 [0.037, 0.710] | 0.500 [0.013, 0.987] | 0.083 [0.002, 0.385] | 0.083 [0.002, 0.385] |
A3 - novel malware family attributed from its documented techniques only
| method | n | top-1 | coverage | selective acc. | wrong actor named (any grade) | wrong at MEDIUM+ / committed | wrong if ties broken at random |
|---|---|---|---|---|---|---|---|
| dragnet | 411 | 0.063 | 0.024 | 0.000 | 0.024 | 0.000 | 0.000 |
| ttp-jaccard | 411 | 0.029 | 0.951 | 0.031 | 0.922 | 0.922 | 0.971 |
| ttp-cosine | 411 | 0.063 | 1.000 | 0.063 | 0.937 | 0.937 | 0.937 |
| ttp-binary-bayes | 411 | 0.000 | 0.842 | 0.000 | 0.842 | 0.842 | 1.000 |
95% intervals (A3, top-1 clustered by group): top-1 by cluster bootstrap; proportions exact Clopper-Pearson.
| method | top-1 | coverage | selective acc. | wrong (any grade) | wrong at MEDIUM+ / committed |
|---|---|---|---|---|---|
| dragnet | 0.063 [0.036, 0.095] | 0.024 [0.012, 0.044] | 0.000 [0.000, 0.308] | 0.024 [0.012, 0.044] | 0.000 [0.000, 0.009] |
| ttp-jaccard | 0.029 [0.011, 0.051] | 0.951 [0.926, 0.970] | 0.031 [0.016, 0.053] | 0.922 [0.892, 0.946] | 0.922 [0.892, 0.946] |
| ttp-cosine | 0.063 [0.036, 0.095] | 1.000 [0.991, 1.000] | 0.063 [0.042, 0.091] | 0.937 [0.909, 0.958] | 0.937 [0.909, 0.958] |
| ttp-binary-bayes | 0.000 [0.000, 0.000] | 0.842 [0.803, 0.876] | 0.000 [0.000, 0.011] | 0.842 [0.803, 0.876] | 0.842 [0.803, 0.876] |
DRAGNET verdicts by stated grade (A3), exact 95% CI:
| grade | n named | correct | accuracy [95% CI] |
|---|---|---|---|
| HIGH | 0 | 0 | n/a [n/a, n/a] |
| MEDIUM | 0 | 0 | n/a [n/a, n/a] |
| LOW | 10 | 0 | 0.000 [0.000, 0.308] |
R - per-report ATT&CK cases (group x cited report)
637 cases over 161 groups: the techniques and software one cited report documents for one group (at least 3 techniques). Labels are ATT&CK's own attribution. k-fold: 5 folds by report; each fold's reports are removed from the profiles before its cases are attributed. Temporal: every citation dated 2022 or later is removed from the profiles, and the 219 cases from reports dated 2022 or later are attributed. Top-1 CIs are clustered by group.
Citation dating: of 1947 citations on 'uses' edges, 1852 are dated from their reference description '(YYYY, Month DD)', 12 only from a year in the citation key, and 83 have no recoverable date ('n.d.'). 52 citations whose key has no year are dated 2022+ by their description and held out (an earlier version dated by key only and kept them in the profiles); 26 keys carry a year that differs from the description. Held out: 547 citations (630 when undated citations are also held out, the sensitivity rows below).
R-kfold (n=637)
| method | n | top-1 | coverage | selective acc. | wrong actor named (any grade) | wrong at MEDIUM+ / committed | wrong if ties broken at random |
|---|---|---|---|---|---|---|---|
| dragnet | 637 | 0.454 | 0.429 | 0.853 | 0.063 | 0.006 | 0.006 |
| ttp-jaccard | 637 | 0.126 | 0.936 | 0.133 | 0.812 | 0.812 | 0.874 |
| ttp-cosine | 637 | 0.218 | 0.983 | 0.222 | 0.765 | 0.765 | 0.782 |
| ttp-binary-bayes | 637 | 0.018 | 0.702 | 0.022 | 0.686 | 0.686 | 0.982 |
| ioc-correlation | 637 | 0.301 | 0.349 | 0.788 | 0.074 | 0.074 | 0.313 |
| code-only | 637 | 0.310 | 0.323 | 0.913 | 0.028 | 0.028 | 0.144 |
| dragnet-ttp-only | 637 | 0.218 | 0.096 | 0.525 | 0.046 | 0.000 | 0.000 |
| dragnet-software-only | 637 | 0.358 | 0.341 | 0.912 | 0.030 | 0.002 | 0.002 |
| dragnet-no-ttpsim | 637 | 0.487 | 0.336 | 0.921 | 0.027 | 0.002 | 0.002 |
| dragnet-no-spec | 637 | 0.429 | 0.498 | 0.703 | 0.148 | 0.003 | 0.003 |
| dragnet-no-ff | 637 | 0.454 | 0.435 | 0.848 | 0.066 | 0.006 | 0.006 |
95% intervals (R-kfold): top-1 by cluster bootstrap; proportions exact Clopper-Pearson.
| method | top-1 | coverage | selective acc. | wrong (any grade) | wrong at MEDIUM+ / committed |
|---|---|---|---|---|---|
| dragnet | 0.454 [0.401, 0.507] | 0.429 [0.390, 0.468] | 0.853 [0.806, 0.893] | 0.063 [0.045, 0.085] | 0.006 [0.002, 0.016] |
| ttp-jaccard | 0.126 [0.084, 0.180] | 0.936 [0.914, 0.953] | 0.133 [0.106, 0.162] | 0.812 [0.779, 0.841] | 0.812 [0.779, 0.841] |
| ttp-cosine | 0.218 [0.160, 0.285] | 0.983 [0.969, 0.991] | 0.222 [0.190, 0.257] | 0.765 [0.730, 0.797] | 0.765 [0.730, 0.797] |
| ttp-binary-bayes | 0.018 [0.008, 0.032] | 0.702 [0.665, 0.737] | 0.022 [0.011, 0.041] | 0.686 [0.648, 0.722] | 0.686 [0.648, 0.722] |
| ioc-correlation | 0.301 [0.245, 0.356] | 0.349 [0.311, 0.387] | 0.788 [0.729, 0.840] | 0.074 [0.055, 0.097] | 0.074 [0.055, 0.097] |
| code-only | 0.310 [0.251, 0.366] | 0.323 [0.287, 0.361] | 0.913 [0.865, 0.947] | 0.028 [0.017, 0.044] | 0.028 [0.017, 0.044] |
| dragnet-ttp-only | 0.218 [0.160, 0.285] | 0.096 [0.074, 0.121] | 0.525 [0.393, 0.654] | 0.046 [0.031, 0.065] | 0.000 [0.000, 0.006] |
| dragnet-software-only | 0.358 [0.302, 0.415] | 0.341 [0.304, 0.379] | 0.912 [0.867, 0.946] | 0.030 [0.018, 0.046] | 0.002 [0.000, 0.009] |
| dragnet-no-ttpsim | 0.487 [0.423, 0.541] | 0.336 [0.299, 0.374] | 0.921 [0.876, 0.953] | 0.027 [0.016, 0.042] | 0.002 [0.000, 0.009] |
| dragnet-no-spec | 0.429 [0.372, 0.486] | 0.498 [0.458, 0.537] | 0.703 [0.650, 0.753] | 0.148 [0.121, 0.178] | 0.003 [0.000, 0.011] |
| dragnet-no-ff | 0.454 [0.401, 0.507] | 0.435 [0.396, 0.474] | 0.848 [0.801, 0.888] | 0.066 [0.048, 0.088] | 0.006 [0.002, 0.016] |
Paired top-1 difference, DRAGNET minus method (R-kfold), clustered by threat group like the marginal CIs: group-cluster bootstrap 95% CI; the sign-flip test flips whole groups (per-group summed differences). Sign-flip test (one-sided, DRAGNET better): exact when at most 20 discordant units, otherwise Monte Carlo with B = 200,000 sign flips, p = (k+1)/(B+1); Holm-adjusted across methods. The last column is the case-level test (cases treated as independent), kept for reference.
| method | diff | 95% CI (group cluster) | discordant cases / groups | p (one-sided) | p (Holm) | p (two-sided) | case-level p (Holm) |
|---|---|---|---|---|---|---|---|
| ttp-jaccard | 0.327 | [0.282, 0.372] | 218 / 81 | 5.0e-06 (MC, B = 200,000) | 5.0e-05 | 5.0e-06 | 5.0e-06 (5.0e-05) |
| ttp-cosine | 0.235 | [0.186, 0.280] | 158 / 67 | 5.0e-06 (MC, B = 200,000) | 5.0e-05 | 5.0e-06 | 5.0e-06 (5.0e-05) |
| ttp-binary-bayes | 0.436 | [0.384, 0.489] | 284 / 91 | 5.0e-06 (MC, B = 200,000) | 5.0e-05 | 5.0e-06 | 5.0e-06 (5.0e-05) |
| ioc-correlation | 0.153 | [0.119, 0.192] | 152 / 73 | 5.0e-06 (MC, B = 200,000) | 5.0e-05 | 5.0e-06 | 5.0e-06 (5.0e-05) |
| code-only | 0.144 | [0.108, 0.184] | 130 / 66 | 5.0e-06 (MC, B = 200,000) | 5.0e-05 | 5.0e-06 | 5.0e-06 (5.0e-05) |
| dragnet-ttp-only | 0.235 | [0.186, 0.280] | 158 / 67 | 5.0e-06 (MC, B = 200,000) | 5.0e-05 | 5.0e-06 | 5.0e-06 (5.0e-05) |
| dragnet-software-only | 0.095 | [0.064, 0.130] | 108 / 57 | 5.0e-06 (MC, B = 200,000) | 5.0e-05 | 5.0e-06 | 5.0e-06 (5.0e-05) |
| dragnet-no-ttpsim | -0.034 | [-0.067, 0.004] | 98 / 45 | 0.956 (MC, B = 200,000) | 1.000 | 0.088 | 0.993 (1.000) |
| dragnet-no-spec | 0.025 | [0.003, 0.048] | 38 / 28 | 0.014 (MC, B = 200,000) | 0.041 | 0.028 | 0.007 (0.020) |
| dragnet-no-ff | 0.000 | [0.000, 0.000] | 0 / 0 | 1.000 (exact) | 1.000 | 1.000 | 1.000 (1.000) |
DRAGNET verdicts by stated grade (R-kfold), exact 95% CI:
| grade | n named | correct | accuracy [95% CI] |
|---|---|---|---|
| HIGH | 0 | 0 | n/a [n/a, n/a] |
| MEDIUM | 83 | 79 | 0.952 [0.881, 0.987] |
| LOW | 190 | 154 | 0.811 [0.747, 0.864] |
Selective risk (error rate among the most confident cases) at fixed coverage, R-kfold; ties in confidence resolved in expectation. Lower is better.
| method | risk @20% | risk @40% | risk @60% | risk @100% | AURC |
|---|---|---|---|---|---|
| dragnet | 0.031 | 0.129 | 0.343 | 0.546 | 0.247 |
| ttp-jaccard | 0.827 | 0.833 | 0.849 | 0.874 | 0.824 |
| ttp-cosine | 0.677 | 0.722 | 0.743 | 0.782 | 0.708 |
| ttp-binary-bayes | 0.953 | 0.971 | 0.974 | 0.982 | 0.950 |
| ioc-correlation | 0.109 | 0.370 | 0.499 | 0.699 | 0.402 |
| code-only | 0.048 | 0.238 | 0.483 | 0.690 | 0.353 |
| dragnet-ttp-only | 0.701 | 0.729 | 0.741 | 0.782 | 0.727 |
| dragnet-software-only | 0.046 | 0.158 | 0.403 | 0.642 | 0.295 |
| dragnet-no-ttpsim | 0.024 | 0.125 | 0.322 | 0.513 | 0.229 |
| dragnet-no-spec | 0.252 | 0.310 | 0.393 | 0.571 | 0.350 |
| dragnet-no-ff | 0.031 | 0.129 | 0.343 | 0.546 | 0.247 |
Selective-risk differences, DRAGNET minus method (R-kfold); group-cluster bootstrap 95% CIs (1,000 resamples). Negative = DRAGNET has the lower risk.
| method | risk @20% diff [95% CI] | AURC diff [95% CI] |
|---|---|---|
| ttp-jaccard | -0.795 [-0.898, -0.674] | -0.577 [-0.651, -0.497] |
| ttp-cosine | -0.646 [-0.790, -0.441] | -0.461 [-0.546, -0.368] |
| ttp-binary-bayes | -0.921 [-0.967, -0.861] | -0.703 [-0.766, -0.635] |
| ioc-correlation | -0.077 [-0.262, -0.007] | -0.154 [-0.208, -0.113] |
| code-only | -0.016 [-0.065, 0.024] | -0.106 [-0.150, -0.072] |
R-temporal (n=219)
| method | n | top-1 | coverage | selective acc. | wrong actor named (any grade) | wrong at MEDIUM+ / committed | wrong if ties broken at random |
|---|---|---|---|---|---|---|---|
| dragnet | 219 | 0.137 | 0.192 | 0.476 | 0.100 | 0.000 | 0.000 |
| ttp-jaccard | 219 | 0.050 | 0.932 | 0.049 | 0.886 | 0.886 | 0.950 |
| ttp-cosine | 219 | 0.078 | 1.000 | 0.078 | 0.922 | 0.922 | 0.922 |
| ttp-binary-bayes | 219 | 0.031 | 0.785 | 0.035 | 0.758 | 0.758 | 0.969 |
| ioc-correlation | 219 | 0.052 | 0.151 | 0.273 | 0.110 | 0.110 | 0.346 |
| code-only | 219 | 0.062 | 0.096 | 0.524 | 0.046 | 0.046 | 0.148 |
| dragnet-ttp-only | 219 | 0.078 | 0.055 | 0.417 | 0.032 | 0.000 | 0.000 |
| dragnet-software-only | 219 | 0.076 | 0.100 | 0.545 | 0.046 | 0.000 | 0.000 |
| dragnet-no-ttpsim | 219 | 0.126 | 0.100 | 0.591 | 0.041 | 0.000 | 0.000 |
| dragnet-no-spec | 219 | 0.123 | 0.274 | 0.317 | 0.187 | 0.005 | 0.005 |
| dragnet-no-ff | 219 | 0.137 | 0.192 | 0.476 | 0.100 | 0.000 | 0.000 |
95% intervals (R-temporal): top-1 by cluster bootstrap; proportions exact Clopper-Pearson.
| method | top-1 | coverage | selective acc. | wrong (any grade) | wrong at MEDIUM+ / committed |
|---|---|---|---|---|---|
| dragnet | 0.137 [0.078, 0.214] | 0.192 [0.142, 0.250] | 0.476 [0.320, 0.636] | 0.100 [0.064, 0.148] | 0.000 [0.000, 0.017] |
| ttp-jaccard | 0.050 [0.020, 0.091] | 0.932 [0.890, 0.961] | 0.049 [0.024, 0.088] | 0.886 [0.836, 0.925] | 0.886 [0.836, 0.925] |
| ttp-cosine | 0.078 [0.034, 0.139] | 1.000 [0.983, 1.000] | 0.078 [0.046, 0.121] | 0.922 [0.879, 0.954] | 0.922 [0.879, 0.954] |
| ttp-binary-bayes | 0.031 [0.000, 0.075] | 0.785 [0.725, 0.838] | 0.035 [0.013, 0.074] | 0.758 [0.696, 0.813] | 0.758 [0.696, 0.813] |
| ioc-correlation | 0.052 [0.024, 0.090] | 0.151 [0.106, 0.205] | 0.273 [0.133, 0.455] | 0.110 [0.071, 0.159] | 0.110 [0.071, 0.159] |
| code-only | 0.062 [0.027, 0.107] | 0.096 [0.060, 0.143] | 0.524 [0.298, 0.743] | 0.046 [0.022, 0.082] | 0.046 [0.022, 0.082] |
| dragnet-ttp-only | 0.078 [0.034, 0.139] | 0.055 [0.029, 0.094] | 0.417 [0.152, 0.723] | 0.032 [0.013, 0.065] | 0.000 [0.000, 0.017] |
| dragnet-software-only | 0.076 [0.038, 0.125] | 0.100 [0.064, 0.148] | 0.545 [0.322, 0.756] | 0.046 [0.022, 0.082] | 0.000 [0.000, 0.017] |
| dragnet-no-ttpsim | 0.126 [0.069, 0.194] | 0.100 [0.064, 0.148] | 0.591 [0.364, 0.793] | 0.041 [0.019, 0.077] | 0.000 [0.000, 0.017] |
| dragnet-no-spec | 0.123 [0.070, 0.193] | 0.274 [0.216, 0.338] | 0.317 [0.203, 0.450] | 0.187 [0.138, 0.245] | 0.005 [0.000, 0.025] |
| dragnet-no-ff | 0.137 [0.078, 0.214] | 0.192 [0.142, 0.250] | 0.476 [0.320, 0.636] | 0.100 [0.064, 0.148] | 0.000 [0.000, 0.017] |
Paired top-1 difference, DRAGNET minus method (R-temporal), clustered by threat group like the marginal CIs: group-cluster bootstrap 95% CI; the sign-flip test flips whole groups (per-group summed differences). Sign-flip test (one-sided, DRAGNET better): exact when at most 20 discordant units, otherwise Monte Carlo with B = 200,000 sign flips, p = (k+1)/(B+1); Holm-adjusted across methods. The last column is the case-level test (cases treated as independent), kept for reference.
| method | diff | 95% CI (group cluster) | discordant cases / groups | p (one-sided) | p (Holm) | p (two-sided) | case-level p (Holm) |
|---|---|---|---|---|---|---|---|
| ttp-jaccard | 0.087 | [0.045, 0.137] | 21 / 16 | 4.6e-05 (exact) | 4.6e-04 | 9.2e-05 | 5.0e-06 (5.0e-05) |
| ttp-cosine | 0.059 | [0.021, 0.108] | 13 / 9 | 0.002 (exact) | 0.010 | 0.004 | 1.2e-04 (6.1e-04) |
| ttp-binary-bayes | 0.106 | [0.051, 0.169] | 27 / 18 | 5.3e-05 (exact) | 4.8e-04 | 1.1e-04 | 5.0e-06 (5.0e-05) |
| ioc-correlation | 0.085 | [0.041, 0.144] | 26 / 16 | 6.1e-05 (exact) | 4.9e-04 | 1.2e-04 | 5.0e-06 (5.0e-05) |
| code-only | 0.075 | [0.029, 0.136] | 26 / 16 | 7.3e-04 (exact) | 0.004 | 0.001 | 3.0e-05 (2.1e-04) |
| dragnet-ttp-only | 0.059 | [0.021, 0.108] | 13 / 9 | 0.002 (exact) | 0.010 | 0.004 | 1.2e-04 (6.1e-04) |
| dragnet-software-only | 0.061 | [0.025, 0.110] | 20 / 13 | 4.9e-04 (exact) | 0.003 | 9.8e-04 | 3.1e-05 (2.1e-04) |
| dragnet-no-ttpsim | 0.011 | [-0.027, 0.055] | 17 / 10 | 0.309 (exact) | 0.750 | 0.617 | 0.262 (0.562) |
| dragnet-no-spec | 0.014 | [-0.009, 0.040] | 5 / 4 | 0.250 (exact) | 0.750 | 0.500 | 0.188 (0.562) |
| dragnet-no-ff | 0.000 | [0.000, 0.000] | 0 / 0 | 1.000 (exact) | 1.000 | 1.000 | 1.000 (1.000) |
DRAGNET verdicts by stated grade (R-temporal), exact 95% CI:
| grade | n named | correct | accuracy [95% CI] |
|---|---|---|---|
| HIGH | 0 | 0 | n/a [n/a, n/a] |
| MEDIUM | 2 | 2 | 1.000 [0.158, 1.000] |
| LOW | 40 | 18 | 0.450 [0.293, 0.615] |
Selective risk (error rate among the most confident cases) at fixed coverage, R-temporal; ties in confidence resolved in expectation. Lower is better.
| method | risk @20% | risk @40% | risk @60% | risk @100% | AURC |
|---|---|---|---|---|---|
| dragnet | 0.523 | 0.739 | 0.802 | 0.863 | 0.692 |
| ttp-jaccard | 0.898 | 0.903 | 0.924 | 0.950 | 0.896 |
| ttp-cosine | 0.795 | 0.864 | 0.893 | 0.922 | 0.862 |
| ttp-binary-bayes | 0.909 | 0.932 | 0.952 | 0.969 | 0.931 |
| ioc-correlation | 0.798 | 0.871 | 0.914 | 0.948 | 0.858 |
| code-only | 0.693 | 0.846 | 0.897 | 0.938 | 0.814 |
| dragnet-ttp-only | 0.818 | 0.886 | 0.916 | 0.922 | 0.840 |
| dragnet-software-only | 0.648 | 0.810 | 0.872 | 0.924 | 0.771 |
| dragnet-no-ttpsim | 0.614 | 0.795 | 0.840 | 0.874 | 0.725 |
| dragnet-no-spec | 0.727 | 0.761 | 0.832 | 0.877 | 0.768 |
| dragnet-no-ff | 0.523 | 0.739 | 0.802 | 0.863 | 0.692 |
Selective-risk differences, DRAGNET minus method (R-temporal); group-cluster bootstrap 95% CIs (1,000 resamples). Negative = DRAGNET has the lower risk.
| method | risk @20% diff [95% CI] | AURC diff [95% CI] |
|---|---|---|
| ttp-jaccard | -0.375 [-0.543, -0.127] | -0.203 [-0.314, -0.100] |
| ttp-cosine | -0.273 [-0.457, -0.024] | -0.169 [-0.286, -0.052] |
| ttp-binary-bayes | -0.386 [-0.559, -0.154] | -0.239 [-0.357, -0.130] |
| ioc-correlation | -0.275 [-0.414, -0.086] | -0.166 [-0.249, -0.082] |
| code-only | -0.171 [-0.320, 0.026] | -0.122 [-0.213, -0.041] |
R-temporal sensitivity: undated citations also held out (n=219)
| method | n | top-1 | coverage | selective acc. | wrong actor named (any grade) | wrong at MEDIUM+ / committed | wrong if ties broken at random |
|---|---|---|---|---|---|---|---|
| dragnet | 219 | 0.078 | 0.178 | 0.308 | 0.123 | 0.005 | 0.005 |
| ttp-jaccard | 219 | 0.021 | 0.927 | 0.020 | 0.909 | 0.909 | 0.979 |
| ttp-cosine | 219 | 0.032 | 1.000 | 0.032 | 0.968 | 0.968 | 0.968 |
| ttp-binary-bayes | 219 | 0.011 | 0.744 | 0.012 | 0.735 | 0.735 | 0.989 |
| ioc-correlation | 219 | 0.041 | 0.146 | 0.219 | 0.114 | 0.114 | 0.352 |
| code-only | 219 | 0.044 | 0.096 | 0.381 | 0.059 | 0.059 | 0.157 |
| dragnet-ttp-only | 219 | 0.032 | 0.064 | 0.071 | 0.059 | 0.000 | 0.000 |
| dragnet-software-only | 219 | 0.054 | 0.096 | 0.381 | 0.059 | 0.000 | 0.000 |
| dragnet-no-ttpsim | 219 | 0.098 | 0.091 | 0.450 | 0.050 | 0.000 | 0.000 |
| dragnet-no-spec | 219 | 0.078 | 0.269 | 0.220 | 0.210 | 0.005 | 0.005 |
| dragnet-no-ff | 219 | 0.078 | 0.178 | 0.308 | 0.123 | 0.005 | 0.005 |
95% intervals (R-temporal, undated held out): top-1 by cluster bootstrap; proportions exact Clopper-Pearson.
| method | top-1 | coverage | selective acc. | wrong (any grade) | wrong at MEDIUM+ / committed |
|---|---|---|---|---|---|
| dragnet | 0.078 [0.035, 0.130] | 0.178 [0.130, 0.235] | 0.308 [0.170, 0.476] | 0.123 [0.083, 0.174] | 0.005 [0.000, 0.025] |
| ttp-jaccard | 0.021 [0.004, 0.045] | 0.927 [0.884, 0.958] | 0.020 [0.005, 0.050] | 0.909 [0.862, 0.943] | 0.909 [0.862, 0.943] |
| ttp-cosine | 0.032 [0.010, 0.063] | 1.000 [0.983, 1.000] | 0.032 [0.013, 0.065] | 0.968 [0.935, 0.987] | 0.968 [0.935, 0.987] |
| ttp-binary-bayes | 0.011 [0.000, 0.039] | 0.744 [0.681, 0.801] | 0.012 [0.001, 0.044] | 0.735 [0.671, 0.792] | 0.735 [0.671, 0.792] |
| ioc-correlation | 0.041 [0.013, 0.078] | 0.146 [0.102, 0.200] | 0.219 [0.093, 0.400] | 0.114 [0.075, 0.164] | 0.114 [0.075, 0.164] |
| code-only | 0.044 [0.012, 0.084] | 0.096 [0.060, 0.143] | 0.381 [0.181, 0.616] | 0.059 [0.032, 0.099] | 0.059 [0.032, 0.099] |
| dragnet-ttp-only | 0.032 [0.010, 0.063] | 0.064 [0.035, 0.105] | 0.071 [0.002, 0.339] | 0.059 [0.032, 0.099] | 0.000 [0.000, 0.017] |
| dragnet-software-only | 0.054 [0.020, 0.096] | 0.096 [0.060, 0.143] | 0.381 [0.181, 0.616] | 0.059 [0.032, 0.099] | 0.000 [0.000, 0.017] |
| dragnet-no-ttpsim | 0.098 [0.050, 0.155] | 0.091 [0.057, 0.138] | 0.450 [0.231, 0.685] | 0.050 [0.025, 0.088] | 0.000 [0.000, 0.017] |
| dragnet-no-spec | 0.078 [0.035, 0.134] | 0.269 [0.212, 0.333] | 0.220 [0.123, 0.347] | 0.210 [0.158, 0.270] | 0.005 [0.000, 0.025] |
| dragnet-no-ff | 0.078 [0.035, 0.130] | 0.178 [0.130, 0.235] | 0.308 [0.170, 0.476] | 0.123 [0.083, 0.174] | 0.005 [0.000, 0.025] |
Paired top-1 difference, DRAGNET minus method (R-temporal, undated held out), clustered by threat group like the marginal CIs: group-cluster bootstrap 95% CI; the sign-flip test flips whole groups (per-group summed differences). Sign-flip test (one-sided, DRAGNET better): exact when at most 20 discordant units, otherwise Monte Carlo with B = 200,000 sign flips, p = (k+1)/(B+1); Holm-adjusted across methods. The last column is the case-level test (cases treated as independent), kept for reference.
| method | diff | 95% CI (group cluster) | discordant cases / groups | p (one-sided) | p (Holm) | p (two-sided) | case-level p (Holm) |
|---|---|---|---|---|---|---|---|
| ttp-jaccard | 0.057 | [0.022, 0.101] | 13 / 9 | 0.002 (exact) | 0.020 | 0.004 | 1.2e-04 (0.001) |
| ttp-cosine | 0.046 | [0.006, 0.094] | 12 / 8 | 0.027 (exact) | 0.137 | 0.055 | 0.003 (0.019) |
| ttp-binary-bayes | 0.066 | [0.011, 0.124] | 20 / 12 | 0.010 (exact) | 0.067 | 0.019 | 3.6e-04 (0.003) |
| ioc-correlation | 0.037 | [0.011, 0.071] | 15 / 10 | 0.004 (exact) | 0.035 | 0.008 | 9.8e-04 (0.008) |
| code-only | 0.034 | [0.011, 0.066] | 14 / 10 | 0.004 (exact) | 0.035 | 0.008 | 0.002 (0.014) |
| dragnet-ttp-only | 0.046 | [0.006, 0.094] | 12 / 8 | 0.027 (exact) | 0.137 | 0.055 | 0.003 (0.019) |
| dragnet-software-only | 0.024 | [0.005, 0.053] | 12 / 8 | 0.016 (exact) | 0.094 | 0.031 | 0.008 (0.031) |
| dragnet-no-ttpsim | -0.020 | [-0.055, 0.016] | 17 / 10 | 0.883 (exact) | 1.000 | 0.264 | 0.933 (1.000) |
| dragnet-no-spec | 0.000 | [-0.015, 0.011] | 2 / 2 | 0.750 (exact) | 1.000 | 1.000 | 0.750 (1.000) |
| dragnet-no-ff | 0.000 | [0.000, 0.000] | 0 / 0 | 1.000 (exact) | 1.000 | 1.000 | 1.000 (1.000) |
DRAGNET verdicts by stated grade (R-temporal, undated held out), exact 95% CI:
| grade | n named | correct | accuracy [95% CI] |
|---|---|---|---|
| HIGH | 0 | 0 | n/a [n/a, n/a] |
| MEDIUM | 1 | 0 | 0.000 [0.000, 0.975] |
| LOW | 38 | 12 | 0.316 [0.175, 0.487] |
Calibration of the top-hypothesis probability
Isotonic map fitted on 406 k-fold cases dated before 2022, evaluated on the 219 temporal test cases (CIs: group-cluster bootstrap, 1,000 resamples).
| forecast | ECE [95% CI] | Brier [95% CI] |
|---|---|---|
| DRAGNET raw ACH score | 0.157 [0.113, 0.210] | 0.113 [0.095, 0.143] |
| DRAGNET isotonic | 0.073 [0.055, 0.145] | 0.100 [0.070, 0.145] |
| ttp-jaccard (normalised share, raw) | 0.015 [0.004, 0.056] | - |
| ttp-cosine (normalised share, raw) | 0.040 [0.007, 0.102] | - |
| ttp-binary-bayes (normalised share, raw) | 0.028 [0.012, 0.058] | - |
| ioc-correlation (normalised share, raw) | 0.047 [0.027, 0.085] | - |
| code-only (normalised share, raw) | 0.046 [0.021, 0.085] | - |
G - comparison with Guru, Moss & Kochenderfer (2025)
Guru et al. (arXiv:2505.11547) attribute threat reports to 29 actors by scoring P(technique | actor), estimated from technique counts in training reports, against the techniques extracted from a test report (machine extraction with text-embedding-3-large over 727 reports); the metric is the mean rank of the true actor among the 29 (random = 15). Paper protocol: 70/20/10 split per actor; 10 weight matrices are trained, the best is selected on the validation split and its test mean rank is reported; the paper does not define its +/-. Their report corpus and extracted technique counts are not public in reusable form, so the paper's numbers cannot be reproduced exactly. Our adaptation keeps their scorer, actor set and 70/20/10 split per actor, but evaluates every one of 10 random splits on its test part (the 20% validation part is unused) and uses ATT&CK's human-curated per-report technique lists (261 reports). Human technique lists are cleaner than machine extraction, so the adaptation is an optimistic upper bound for their pipeline. DRAGNET and the other methods use graphs from which every validation/test report has been removed.
| setting | mean rank of true actor (of 29) | 95% CI (pooled, actor cluster) | top-1 |
|---|---|---|---|
| paper: random | 15.0 | - | - |
| paper: uniform prior | 10.68 +/- 0.53 | - | - |
| paper: expert prior | 7.75 +/- 0.09 | - | - |
| paper: HyDE + expert prior (best) | 7.55 +/- 0.21 | - | - |
| paper artefact: released single test run | 12.67 | - | - |
| ours: their scorer, uniform prior (ATT&CK technique lists) | 8.718 +/- 0.549 | [6.354, 11.770] | 0.200 |
| ours: their scorer, prior = training-report share (expert-prior proxy) | 9.709 +/- 0.454 | [6.998, 13.155] | 0.173 |
| ours: ttp-binary-bayes (simplified) | 9.842 +/- 0.782 | [7.758, 12.202] | 0.112 |
| ours: ttp-jaccard | 8.891 +/- 0.888 | [6.923, 11.182] | 0.161 |
| ours: DRAGNET, techniques only (= ttp-cosine ranking) | 7.547 +/- 0.664 | [5.525, 10.091] | 0.279 |
| ours: DRAGNET, software only | 8.988 +/- 0.537 | [7.178, 10.641] | 0.376 |
| ours: DRAGNET (techniques + software) | 5.382 +/- 0.791 | [3.630, 7.565] | 0.533 |
Ours: mean +/- SD over the 10 random splits. The 95% CI pools the 330 (split, test report) rows and resamples whole actors, so it reflects actor-level variation; the splits reuse the same reports and are not independent samples.
Paired rank difference, method minus DRAGNET (positive = DRAGNET ranks the true actor higher), pooled rows, actor-cluster bootstrap CI; sign-flip over per-actor summed differences. Sign-flip test (one-sided, DRAGNET better): exact when at most 20 discordant units, otherwise Monte Carlo with B = 200,000 sign flips, p = (k+1)/(B+1); Holm-adjusted across methods.
| method | rank diff | 95% CI | splits where DRAGNET is lower | p (one-sided) | p (Holm) |
|---|---|---|---|---|---|
| guru-uniform | 3.336 | [1.839, 5.490] | 10/10 | 1.5e-05 (MC, B = 200,000) | 7.5e-05 |
| guru-report-prior | 4.327 | [1.907, 7.325] | 10/10 | 4.0e-04 (MC, B = 200,000) | 0.001 |
| ttp-binary-bayes | 4.461 | [2.013, 6.776] | 10/10 | 5.9e-04 (MC, B = 200,000) | 0.001 |
| ttp-jaccard | 3.509 | [1.548, 5.543] | 10/10 | 5.2e-04 (MC, B = 200,000) | 0.001 |
| dragnet-ttp-only | 2.165 | [0.982, 4.067] | 10/10 | 5.0e-06 (MC, B = 200,000) | 3.0e-05 |
| dragnet-software-only | 3.606 | [2.080, 4.879] | 10/10 | 7.0e-05 (MC, B = 200,000) | 2.8e-04 |
B - larger case sets
B1 - every attributed ATT&CK campaign across releases and domains
Attributed campaigns per release: v12.1: 1, v13.1: 6, v14.1: 8, v15.1: 12, v16.1: 16, v17.1: 22, v18.1: 24, v19.2 (enterprise+ics+mobile): 26. The union over releases 12.1-19.2 and the Enterprise, ICS and Mobile domains has 26 attributed campaigns, 26 with evidence; new relative to A1: C0031. Campaigns are rarely removed from ATT&CK, so the union barely enlarges the set; the per-report cases (section R) are the real enlargement.
Leave-report-out, Enterprise+ICS+Mobile v19.2 graph:
| method | n | top-1 | coverage | selective acc. | wrong actor named (any grade) | wrong at MEDIUM+ / committed | wrong if ties broken at random |
|---|---|---|---|---|---|---|---|
| dragnet | 26 | 0.423 | 0.462 | 0.750 | 0.115 | 0.000 | 0.000 |
| ioc-correlation | 26 | 0.378 | 0.346 | 1.000 | 0.000 | 0.000 | 0.276 |
| code-only | 26 | 0.367 | 0.385 | 0.900 | 0.038 | 0.038 | 0.095 |
| ttp-jaccard | 26 | 0.115 | 0.962 | 0.120 | 0.846 | 0.846 | 0.846 |
95% intervals (B1): top-1 by case bootstrap; proportions exact Clopper-Pearson.
| method | top-1 | coverage | selective acc. | wrong (any grade) | wrong at MEDIUM+ / committed |
|---|---|---|---|---|---|
| dragnet | 0.423 [0.231, 0.615] | 0.462 [0.266, 0.666] | 0.750 [0.428, 0.945] | 0.115 [0.024, 0.302] | 0.000 [0.000, 0.132] |
| ioc-correlation | 0.378 [0.205, 0.558] | 0.346 [0.172, 0.557] | 1.000 [0.664, 1.000] | 0.000 [0.000, 0.132] | 0.000 [0.000, 0.132] |
| code-only | 0.367 [0.194, 0.558] | 0.385 [0.202, 0.594] | 0.900 [0.555, 0.997] | 0.038 [0.001, 0.196] | 0.038 [0.001, 0.196] |
| ttp-jaccard | 0.115 [0.000, 0.269] | 0.962 [0.804, 0.999] | 0.120 [0.025, 0.312] | 0.846 [0.651, 0.956] | 0.846 [0.651, 0.956] |
Paired top-1 difference, DRAGNET minus method (B1): case bootstrap 95% CI. Sign-flip test (one-sided, DRAGNET better): exact when at most 20 discordant units, otherwise Monte Carlo with B = 200,000 sign flips, p = (k+1)/(B+1); Holm-adjusted across methods.
| method | diff | 95% CI | discordant cases | p (one-sided) | p (Holm) | p (two-sided) |
|---|---|---|---|---|---|---|
| ioc-correlation | 0.045 | [-0.026, 0.147] | 3 | 0.250 (exact) | 0.500 | 0.500 |
| code-only | 0.056 | [-0.003, 0.154] | 3 | 0.250 (exact) | 0.500 | 0.500 |
| ttp-jaccard | 0.308 | [0.154, 0.500] | 8 | 0.004 (exact) | 0.012 | 0.008 |
B2 - rolling origin: each campaign vs the newest release published before it was added
Release used: v12.1: 5, v13.1: 2, v14.1: 5, v15.1: 4, v16.1: 6, v17.1: 2, v18.1: 1.
| method | n | top-1 | coverage | selective acc. | wrong actor named (any grade) | wrong at MEDIUM+ / committed | wrong if ties broken at random | out-of-KG abstain |
|---|---|---|---|---|---|---|---|---|
| dragnet | 25 | 0.474 | 0.421 | 0.875 | 0.120 | 0.000 | 0.000 | 0.667 |
| ioc-correlation | 25 | 0.349 | 0.368 | 0.857 | 0.040 | 0.040 | 0.375 | 1.000 |
| code-only | 25 | 0.321 | 0.368 | 0.857 | 0.080 | 0.080 | 0.156 | 0.833 |
95% intervals (B2): top-1 by case bootstrap; proportions exact Clopper-Pearson.
| method | top-1 | coverage | selective acc. | wrong (any grade) | wrong at MEDIUM+ / committed |
|---|---|---|---|---|---|
| dragnet | 0.474 [0.263, 0.684] | 0.421 [0.203, 0.665] | 0.875 [0.473, 0.997] | 0.120 [0.025, 0.312] | 0.000 [0.000, 0.137] |
| ioc-correlation | 0.349 [0.162, 0.558] | 0.368 [0.163, 0.616] | 0.857 [0.421, 0.996] | 0.040 [0.001, 0.204] | 0.040 [0.001, 0.204] |
| code-only | 0.321 [0.114, 0.531] | 0.368 [0.163, 0.616] | 0.857 [0.421, 0.996] | 0.080 [0.010, 0.260] | 0.080 [0.010, 0.260] |
Paired top-1 difference, DRAGNET minus method (B2): case bootstrap 95% CI. Sign-flip test (one-sided, DRAGNET better): exact when at most 20 discordant units, otherwise Monte Carlo with B = 200,000 sign flips, p = (k+1)/(B+1); Holm-adjusted across methods.
| method | diff | 95% CI | discordant cases | p (one-sided) | p (Holm) | p (two-sided) |
|---|---|---|---|---|---|---|
| ioc-correlation | 0.125 | [-0.018, 0.297] | 4 | 0.125 (exact) | 0.250 | 0.250 |
| code-only | 0.153 | [0.000, 0.353] | 4 | 0.125 (exact) | 0.250 | 0.250 |
B3 - Malpedia-labelled abuse.ch cases
One case per Malpedia family with a single attributed actor and post-2024-01-01 abuse.ch metadata: up to 20 ThreatFox IOCs and 10 MalwareBazaar samples (imphash, TLSH), sampled with 5 seeds (means shown). Graph: ATT&CK v14.1 + pre-cutoff abuse.ch; labels come from Malpedia, a source the graph does not use. Label agreement Malpedia vs ATT&CK on families both attribute: 203/217.
artifacts only (129 cases, 80 with the actor in the graph):
| method | top-1 | coverage | selective acc. | wrong (any grade) | wrong at MEDIUM+ / committed | out-of-KG abstain |
|---|---|---|---|---|---|---|
| dragnet | 0.040 | 0.062 | 0.397 | 0.023 | 0.006 | 1.000 |
| ioc-correlation | 0.040 | 0.035 | 0.700 | 0.006 | 0.006 | 1.000 |
| code-only | 0.040 | 0.035 | 0.700 | 0.006 | 0.006 | 1.000 |
| dragnet-infra-only | 0.000 | 0.000 | n/a | 0.000 | 0.000 | 1.000 |
| dragnet-genetics-only | 0.040 | 0.062 | 0.397 | 0.023 | 0.006 | 1.000 |
95% CIs for the seed-0 sample of this variant (artifacts only): top-1 by case bootstrap, proportions exact Clopper-Pearson (the table above shows the 5-seed means).
| method | top-1 | coverage | selective acc. | wrong (any grade) |
|---|---|---|---|---|
| dragnet | [0.006, 0.085] | [0.021, 0.140] | [0.053, 0.853] | [0.005, 0.066] |
| ioc-correlation | [0.006, 0.085] | [0.008, 0.106] | [0.094, 0.992] | [0.000, 0.042] |
| code-only | [0.006, 0.085] | [0.008, 0.106] | [0.094, 0.992] | [0.000, 0.042] |
| dragnet-infra-only | [0.000, 0.000] | [0.000, 0.045] | [n/a, n/a] | [0.000, 0.028] |
| dragnet-genetics-only | [0.006, 0.085] | [0.021, 0.140] | [0.053, 0.853] | [0.005, 0.066] |
artifacts + family name (129 cases, 80 with the actor in the graph):
| method | top-1 | coverage | selective acc. | wrong (any grade) | wrong at MEDIUM+ / committed | out-of-KG abstain |
|---|---|---|---|---|---|---|
| dragnet | 0.272 | 0.278 | 0.856 | 0.025 | 0.006 | 1.000 |
| ioc-correlation | 0.272 | 0.250 | 0.950 | 0.008 | 0.008 | 1.000 |
| code-only | 0.272 | 0.250 | 0.950 | 0.008 | 0.008 | 1.000 |
| dragnet-infra-only | 0.000 | 0.000 | n/a | 0.000 | 0.000 | 1.000 |
| dragnet-genetics-only | 0.040 | 0.062 | 0.397 | 0.023 | 0.006 | 1.000 |
95% CIs for the seed-0 sample of this variant (artifacts + family name): top-1 by case bootstrap, proportions exact Clopper-Pearson (the table above shows the 5-seed means).
| method | top-1 | coverage | selective acc. | wrong (any grade) |
|---|---|---|---|---|
| dragnet | [0.178, 0.362] | [0.181, 0.386] | [0.651, 0.971] | [0.005, 0.066] |
| ioc-correlation | [0.178, 0.362] | [0.160, 0.359] | [0.751, 0.999] | [0.000, 0.042] |
| code-only | [0.178, 0.362] | [0.160, 0.359] | [0.751, 0.999] | [0.000, 0.042] |
| dragnet-infra-only | [0.000, 0.000] | [0.000, 0.045] | [n/a, n/a] | [0.000, 0.028] |
| dragnet-genetics-only | [0.006, 0.085] | [0.021, 0.140] | [0.053, 0.853] | [0.005, 0.066] |
C - curated real cases (demonstrations, not validation)
Rules R2 and R4 were designed from the Olympic Destroyer and Turla/OilRig patterns, and several cases depend on hand-written graph additions (e.g. WannaCry's code-reuse token), so these are demonstrations that the rules behave as designed, not independent evidence.
time-of-incident
| case | truth | DRAGNET verdict | truth rank | false-flag indicators | as designed | ioc-correlation | ttp-jaccard |
|---|---|---|---|---|---|---|---|
| bangladesh_bank_2016 | APT38, Lazarus Group | Lazarus Group (MEDIUM) | 1 | 0 | yes | Lazarus Group | Group5 |
| commodity_tooling_generic | (none) | - (INSUFFICIENT) | - | 0 | yes | tie among 26 (abstain) | Threat Group-1314 |
| notpetya_2017 | Sandworm Team | Sandworm Team (MEDIUM) | 1 | 0 | yes | Sandworm Team | Blue Mockingbird |
| olympic_destroyer_2018 | Sandworm Team | - (INSUFFICIENT) | 12 | 3 | yes | menuPass | Play |
| sony_pictures_2014 | Lazarus Group | Lazarus Group (MEDIUM) | 1 | 0 | yes | Lazarus Group | Orangeworm |
| turla_oilrig_2019 | Turla | OilRig (LOW) | 2 | 1 | yes | OilRig | Tropic Trooper |
| wannacry_2017 | Lazarus Group | Lazarus Group (MEDIUM) | 1 | 0 | yes | Lazarus Group | Lotus Blossom |
Behaved as designed: 7/7
retrospective
| case | truth | DRAGNET verdict | truth rank | false-flag indicators | as designed | ioc-correlation | ttp-jaccard |
|---|---|---|---|---|---|---|---|
| bangladesh_bank_2016 | APT38, Lazarus Group | Lazarus Group (MEDIUM) | 1 | 0 | yes | Lazarus Group | Group5 |
| commodity_tooling_generic | (none) | - (INSUFFICIENT) | - | 0 | yes | tie among 26 (abstain) | Threat Group-1314 |
| notpetya_2017 | Sandworm Team | Sandworm Team (MEDIUM) | 1 | 0 | yes | Sandworm Team | Blue Mockingbird |
| olympic_destroyer_2018 | Sandworm Team | - (INSUFFICIENT) | 3 | 4 | yes | tie among 2 (abstain) | Play |
| sony_pictures_2014 | Lazarus Group | Lazarus Group (MEDIUM) | 1 | 0 | yes | Lazarus Group | Orangeworm |
| turla_oilrig_2019 | Turla | OilRig (LOW) | 2 | 1 | yes | OilRig | Tropic Trooper |
| wannacry_2017 | Lazarus Group | Lazarus Group (MEDIUM) | 1 | 0 | yes | Lazarus Group | Lotus Blossom |
Behaved as designed: 7/7
D - false-flag stress test (planted decoy artifacts on A1 cases)
Decoys are drawn only from other sponsor states (the condition rules R3/R4 check), and the planted Rich header matches exactly one actor's simulated reference sample, so rule R1 fires by construction at level 1. Level 2 (a stolen exclusive decoy family) is the informative test.
False-flag indicators on clean A1 cases (false-alarm rate): 0.160 (4/25, exact 95% CI [0.045, 0.361])
level1 (seed 7)
| method | n | decoy ranked #1 | confidently attributed to decoy | truth ranked #1 | flagged | withheld (<=LOW) |
|---|---|---|---|---|---|---|
| dragnet | 25 | 0.440 | 0.000 | 0.520 | 1.000 | 1.000 |
| ttp-jaccard | 25 | 0.000 | 0.000 | 0.120 | 0.000 | 0.000 |
| ttp-cosine | 25 | 0.000 | 0.000 | 0.080 | 0.000 | 0.000 |
| ttp-binary-bayes | 25 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 |
| ioc-correlation | 25 | 0.541 | 0.440 | 0.267 | 0.000 | 0.000 |
| code-only | 25 | 0.000 | 0.000 | 0.540 | 0.000 | 0.000 |
| dragnet-no-ff | 25 | 0.440 | 0.000 | 0.520 | 0.000 | 0.800 |
DRAGNET confidently attributed to decoy, exact 95% CI: [0.000, 0.137].
Over 10 decoy seeds (same cases, different decoys): mean and range (min-max, not a CI):
- dragnet: mean 0.000, range 0.000-0.000
- ttp-jaccard: mean 0.000, range 0.000-0.000
- ttp-cosine: mean 0.000, range 0.000-0.000
- ttp-binary-bayes: mean 0.008, range 0.000-0.040
- ioc-correlation: mean 0.476, range 0.440-0.560
- code-only: mean 0.000, range 0.000-0.000
- dragnet-no-ff: mean 0.000, range 0.000-0.000
Effect of the false-flag rules (no-ff minus full engine, confident decoy rate, all case x seed cells): 0.000, 95% CI [0.000, 0.000] (bootstrap clustered by case).
level2 (seed 7)
| method | n | decoy ranked #1 | confidently attributed to decoy | truth ranked #1 | flagged | withheld (<=LOW) |
|---|---|---|---|---|---|---|
| dragnet | 25 | 0.760 | 0.240 | 0.240 | 0.760 | 0.760 |
| ttp-jaccard | 25 | 0.000 | 0.000 | 0.120 | 0.000 | 0.000 |
| ttp-cosine | 25 | 0.000 | 0.000 | 0.080 | 0.000 | 0.000 |
| ttp-binary-bayes | 25 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 |
| ioc-correlation | 25 | 0.780 | 0.760 | 0.180 | 0.000 | 0.000 |
| code-only | 25 | 0.520 | 0.400 | 0.440 | 0.000 | 0.000 |
| dragnet-no-ff | 25 | 0.760 | 0.400 | 0.240 | 0.000 | 0.600 |
DRAGNET confidently attributed to decoy, exact 95% CI: [0.094, 0.451].
Over 10 decoy seeds (same cases, different decoys): mean and range (min-max, not a CI):
- dragnet: mean 0.172, range 0.120-0.240
- ttp-jaccard: mean 0.000, range 0.000-0.000
- ttp-cosine: mean 0.000, range 0.000-0.000
- ttp-binary-bayes: mean 0.008, range 0.000-0.040
- ioc-correlation: mean 0.772, range 0.760-0.800
- code-only: mean 0.400, range 0.400-0.400
- dragnet-no-ff: mean 0.400, range 0.400-0.400
Effect of the false-flag rules (no-ff minus full engine, confident decoy rate, all case x seed cells): 0.228, 95% CI [0.108, 0.368] (bootstrap clustered by case).
E1 - ThreatFox export structure and IOC re-sighting
The export has 109234 rows and 108378 distinct IOC values; 0.992 of values occur in exactly one row, because ThreatFox records an IOC once (re-sightings do not create rows). The export therefore cannot measure IOC longevity, and no longevity conclusion is drawn.
Actor-specific-family IOCs: 2810 (types: {'url': 187, 'ip:port': 516, 'domain': 223, 'sha256_hash': 703, 'md5_hash': 841, 'sha1_hash': 340}); network IOCs (IP, domain): 739, spanning ['2020-12-15', '2026-10-02']. Split at the median network-IOC date (2026-06-30), 5 of 370 later network IOCs had an earlier row. Families are mostly commodity: WannaCryptor 462, Akira 406, Agent Tesla 304, Havoc 291, AgendaCrypt 194, CrossRAT 171.
E2 - MalwareBazaar imphash genetics (train < cutoff, test >= cutoff)
494204 labelled samples with imphash; 205246 in actor-specific ATT&CK families (train 191843, test 13403). The test samples share only 1139 distinct imphashes and are dominated by a few families (AgentTesla 8434, Amadey 1923, WannaCry 739, Loki 567, PureCrypter 324), so per-sample accuracy mostly measures re-identification of a few commodity families. CIs resample whole families.
| variant | method | coverage | selective acc. [family-cluster 95% CI] | macro acc. over families | families covered | imphashes covered |
|---|---|---|---|---|---|---|
| collision-filtered | DRAGNET (any grade) | 0.078 | 0.918 [0.455, 0.999] | 0.919 | 25 | 84 |
| collision-filtered | DRAGNET MEDIUM+ | 0.064 | 0.998 [0.943, 1.000] | 0.882 | 17 | 63 |
| collision-filtered | imphash lookup | 0.064 | 0.998 [0.943, 1.000] | 0.882 | 17 | 63 |
| collision-filtered | DRAGNET, WannaCry excluded | 0.024 | 0.726 [0.308, 0.995] | 0.915 | 24 | 78 |
| collision-filtered | DRAGNET MEDIUM+, WannaCry excluded | 0.010 | 0.984 [0.889, 1.000] | 0.875 | 16 | 57 |
| unfiltered | DRAGNET (any grade) | 0.114 | 0.866 [0.590, 0.989] | 0.790 | 29 | 111 |
| unfiltered | DRAGNET MEDIUM+ | 0.092 | 0.912 [0.458, 0.999] | 0.862 | 21 | 78 |
| unfiltered | imphash lookup | 0.092 | 0.912 [0.458, 0.999] | 0.862 | 21 | 78 |
| unfiltered | DRAGNET, WannaCry excluded | 0.063 | 0.741 [0.448, 0.954] | 0.782 | 28 | 105 |
| unfiltered | DRAGNET MEDIUM+, WannaCry excluded | 0.040 | 0.783 [0.309, 0.998] | 0.855 | 20 | 72 |
Share of collision-filtered MEDIUM+ verdicts that are WannaCry: 0.853.
E3 - MalwareBazaar TLSH genetics (train < cutoff, test >= cutoff)
Pre-cutoff TLSH digests of actor-specific families become fuzzy graph signals (collision filter: a digest whose radius-tau neighbourhood in a 100000-digest pre-cutoff sample spans more than 2 families is dropped). tau was chosen on a validation window ['2023-07-01', '2024-01-01'] (n=3000) by maximising correct minus twice wrong verdicts: chosen tau = 100 (tau 30: cov 0.005, acc 1.000, tau 50: cov 0.010, acc 0.806, tau 70: cov 0.014, acc 0.854, tau 100: cov 0.022, acc 0.851). Graph digests: 14376; test samples: 30643. Searches are exact (numpy); the stdlib banded index recovers 0.963 of the 1704 true neighbour pairs (within the chosen radius tau = 100) of 300 test queries. The shipped runtime default TLSH_TAU = 50 is more conservative than the evaluated tau = 100; at distance < 100 Oliver, Cheng & Chen (CTC 2013, Table II) report about a 6.43% file-pair false-positive rate.
| method | coverage | selective acc. [family-cluster 95% CI] | macro acc. over families | families covered | clusters |
|---|---|---|---|---|---|
| DRAGNET (any grade) | 0.039 | 0.844 [0.461, 0.957] | 0.592 | 37 | 37 |
| DRAGNET MEDIUM+ | 0.000 | n/a [n/a, n/a] | n/a | 0 | 0 |
| TLSH nearest-neighbour lookup | 0.052 | 0.807 [0.464, 0.934] | 0.605 | 30 | 30 |
| DRAGNET, WannaCry excluded | 0.017 | 0.648 [0.405, 0.809] | 0.581 | 36 | 36 |
False alarms on 3000 post-cutoff samples of families with no actor mapping: an actor was named for 0.008 of them, at MEDIUM+ for 0.000.
F - accuracy vs public reporting depth (APTnotes, A1 cases)
An association, not a cause: APTnotes is dense for 2010-2018 and nearly empty afterwards, so '0 reports' partly means 'recently named actor'. Shown with ATT&CK-only aliases and with MISP aliases merged (which lets e.g. AppleJeus inherit Lazarus reports).
ATT&CK aliases only (Fisher exact p, 0 vs >0 reports: 0.007)
| truth actor reporting | n | DRAGNET top-1 |
|---|---|---|
| 0 reports | 11 | 0.364 |
| 1-5 reports | 9 | 0.889 |
| >5 reports | 5 | 1.000 |
ATT&CK + MISP aliases (Fisher exact p, 0 vs >0 reports: 0.028)
| truth actor reporting | n | DRAGNET top-1 |
|---|---|---|
| 0 reports | 10 | 0.400 |
| 1-5 reports | 2 | 1.000 |
| >5 reports | 13 | 0.846 |
K - APTMalware hashes in MalwareBazaar metadata (Kida & Olukoya 2023)
APTMalware (overview.csv, 4449 rows) lists 3719 distinct SHA-256s; 12 of them occur among the 1147952 rows of the MalwareBazaar metadata export used here (by group: APT 1 2, APT 10 3, APT 28 2, Energetic Bear 1, Equation Group 2, Gorgon Group 2). The fuzzy-hash study of Kida & Olukoya (IEEE Access 11:1148-1165, 2023, doi:10.1109/ACCESS.2022.3233403) needs the binaries, so its results cannot be matched from metadata. The export changes daily, so this count drifts.
Runtime of the last run: 1044.3 s (A1,A1LF,A2,A3,R,G,B,C,D,E1,E2,E3,F,K)