Evaluation¶
Every number on this page comes from a script in scripts/ run on pinned,
checksummed public data. The result files in
results/ are
included here verbatim.
Provenance. Each table names the GitHub Actions run and the commit that
produced it. All current files come from bench run
37093689060
of the manual bench workflow. That workflow regenerates every file and lists
any value that differs from the committed one. Reproduce gives
the commands and runtimes.
Intervals. All are 95%:
- group-cluster bootstrap where incidents share a group, with paired differences computed on the same resamples;
- a Wilson interval with the number of groups as the sample size when a rate is exactly 0 or 1 and the bootstrap interval is degenerate (marked †);
- Wilson intervals for the small APTnotes and campaign sets;
- a leave-one-group-out jackknife for clustering scores;
- a document bootstrap for extraction.
A "± SD over folds" describes how much the folds vary, not confidence.
Summary¶
Research question. Does automated ACH with mandatory disconfirming-evidence weighting give better-calibrated, less overconfident attribution than naive TTP-similarity matching, especially under false flags?
Mostly no. ACH's remaining advantage is an inspectable matrix with span-anchored evidence. That is a design property and is not measured here.
- Calibration. Under one setting-agnostic calibration map, ACH's pooled Brier score is 0.214 [0.202–0.226] and the marker-trusting matcher's is 0.160 [0.141–0.178]. The paired difference is +0.031 to +0.080, for an equal mix of closed, open and planted-marker incidents. ACH is better in the closed world (paired −0.178 to −0.075) and worse in the open and planted-marker settings.
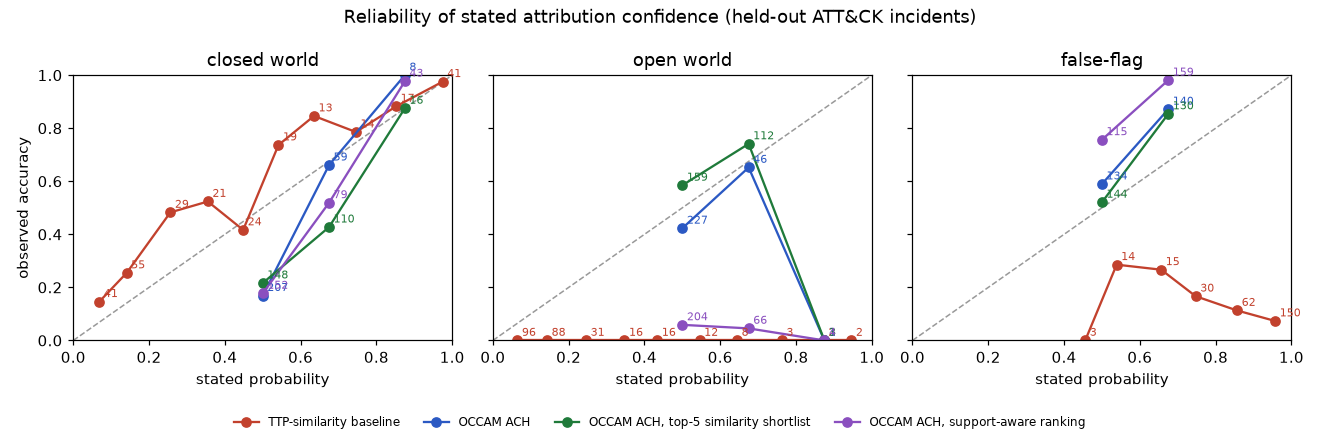
- Overconfidence is a property of the raw outputs. Under planted markers, ACH's capped grades are never wrong at stated p ≥ 0.8 (0/274), while the matcher's softmax is wrong at that level 194/274 times. After one recalibration, neither method makes such errors: 1/822 for ACH, 0/822 for the matcher.
- Planted markers. Resistance does not depend on ACH's false-flag machinery. ACH is still framed only 2.6% of the time without its false-flag hypotheses, spoofable discount and caps. It comes from hard evidence contradicting the framed group, which both ranking rules honour. Any baseline that ignores spoofable rows is never framed, and a consistency gate is correct more often.
- Mimicry. ACH is framed less often than IDF coverage (27.0% vs 32.1%; paired −8.6 to −1.8 points) but is correct less often (17.9% vs 28.8%; paired −16.0 to −6.6 points).
- Abstention. A cosine-threshold baseline matched to ACH's closed-world accuracy declines 93.4% of the time on untracked actors, against ACH's 46.0%. Matched to ACH's decline rate, it is right 47.4% of the time in the closed world, against 29.9%.
- Costs. ACH loses closed-world accuracy, and it calls genuine marker overlap a frame-up 18.6% of the time.
1. False flags: baselines, controls and ablations¶
Methodology: the 274 leave-one-report-out incidents of section 2, in five settings:
- closed;
- open;
- false_flag: 3 spoofable markers frame a random other group;
- authentic: the same markers point at the true group, a control for false alarms;
- mimicry: the framed group's 3 rarest techniques or software are added as hard evidence.
Baselines include:
- the shipped marker-trusting similarity (marker boost 0.15) and a sweep of the boost;
- similarity that ignores spoofable rows;
- IDF coverage;
- an abstaining similarity at three cross-fitted operating points (best closed + open accuracy, ACH's decline rate, ACH's closed-world accuracy);
- a consistency gate.
Thresholds are cross-fitted over a 2-fold group split. Each ACH mechanism is removed one at a time. Calibration uses one map fitted on closed, open and false-flag incidents together, cross-fitted by group.
274 held-out incidents from 103 groups, 3 markers per incident. Brackets: group-cluster bootstrap 95% CI (1000 resamples); † = the rate is exactly 0 or 1, so the bootstrap interval is degenerate and a Wilson interval with the number of groups as the sample size is shown. Cross-fitted parameters (per group fold): tau = {0: 0.38, 1: 0.36}, k = {0: 15, 1: 10}; tau matched to ACH's open-world decline = {0: 0.25, 1: 0.255}, to ACH's closed-world accuracy = {0: 0.35, 1: 0.37}.
Source: GitHub Actions run 37093689060, commit 09cde53, 2026-10-03T03:35:51+00:00.
Planted markers (false_flag) vs authentic markers (control) vs TTP mimicry¶
| Method | False flag: correct | False flag: names framed | Authentic: names true | Authentic: calls it a frame | Mimicry: correct | Mimicry: names framed |
|---|---|---|---|---|---|---|
| TTP-similarity, marker boost 0.15 (shipped baseline) | 0.113 [0.06-0.17] | 0.880 [0.82-0.93] | 1.000 [0.96-1.00]† | 0.000 [0.00-0.04]† | 0.212 [0.16-0.27] | 0.763 [0.71-0.82] |
| TTP-similarity, marker boost 0.05 | 0.496 [0.42-0.57] | 0.124 [0.09-0.17] | 0.854 [0.80-0.90] | 0.000 [0.00-0.04]† | 0.212 [0.16-0.27] | 0.763 [0.71-0.82] |
| TTP-similarity, marker boost 0.3 | 0.000 [0.00-0.04]† | 1.000 [0.96-1.00]† | 1.000 [0.96-1.00]† | 0.000 [0.00-0.04]† | 0.212 [0.16-0.27] | 0.763 [0.71-0.82] |
| TTP-similarity, ignores spoofable rows | 0.533 [0.45-0.61] | 0.000 [0.00-0.04]† | 0.533 [0.45-0.61] | 0.000 [0.00-0.04]† | 0.212 [0.16-0.27] | 0.763 [0.71-0.82] |
| IDF coverage, ignores spoofable rows | 0.420 [0.35-0.49] | 0.000 [0.00-0.04]† | 0.420 [0.35-0.49] | 0.000 [0.00-0.04]† | 0.288 [0.22-0.36] | 0.321 [0.25-0.39] |
| Similarity + decline if cosine < tau (tau cross-fitted) | 0.266 [0.20-0.34] | 0.000 [0.00-0.04]† | 0.266 [0.20-0.34] | 0.000 [0.00-0.04]† | 0.109 [0.07-0.15] | 0.445 [0.38-0.50] |
| Similarity + decline, tau matched to ACH's open-world decline rate | 0.474 [0.40-0.55] | 0.000 [0.00-0.04]† | 0.474 [0.40-0.55] | 0.000 [0.00-0.04]† | 0.201 [0.14-0.25] | 0.715 [0.66-0.77] |
| Similarity + decline, tau matched to ACH's closed-world accuracy | 0.299 [0.23-0.37] | 0.000 [0.00-0.04]† | 0.299 [0.23-0.37] | 0.000 [0.00-0.04]† | 0.128 [0.08-0.17] | 0.460 [0.40-0.52] |
| Similarity + consistency gate (k cross-fitted) | 0.920 [0.88-0.95] | 0.080 [0.05-0.12] | 0.770 [0.71-0.83] | 0.230 [0.17-0.29] | 0.212 [0.16-0.27] | 0.763 [0.71-0.82] |
| OCCAM ACH (full) | 0.734 [0.67-0.80] | 0.011 [0.00-0.03] | 0.358 [0.29-0.43] | 0.186 [0.14-0.24] | 0.179 [0.12-0.24] | 0.270 [0.21-0.33] |
Closed and open world (abstention) and setting-agnostic calibration¶
| Method | Closed: correct | Closed: declines | Open: correct decline | Brier, pooled map | Brier, ACH minus method (paired) | Overconfident errors, pooled map |
|---|---|---|---|---|---|---|
| TTP-similarity, marker boost 0.15 (shipped baseline) | 0.533 [0.45-0.61] | 0.000 [0.00-0.04]† | 0.000 [0.00-0.04]† | 0.160 [0.14-0.18] | [+0.031, +0.080] | 0/822 [0.000-0.036] |
| TTP-similarity, marker boost 0.05 | 0.533 [0.45-0.61] | 0.000 [0.00-0.04]† | 0.000 [0.00-0.04]† | 0.144 [0.12-0.16] | [+0.048, +0.095] | 7/822 [0.000-0.020] |
| TTP-similarity, marker boost 0.3 | 0.533 [0.45-0.61] | 0.000 [0.00-0.04]† | 0.000 [0.00-0.04]† | 0.124 [0.11-0.14] | [+0.068, +0.111] | 0/822 [0.000-0.036] |
| TTP-similarity, ignores spoofable rows | 0.533 [0.45-0.61] | 0.000 [0.00-0.04]† | 0.000 [0.00-0.04]† | 0.151 [0.13-0.17] | [+0.039, +0.087] | 7/822 [0.000-0.020] |
| IDF coverage, ignores spoofable rows | 0.420 [0.35-0.49] | 0.000 [0.00-0.04]† | 0.000 [0.00-0.04]† | 0.167 [0.14-0.19] | [+0.021, +0.074] | 0/822 [0.000-0.036] |
| Similarity + decline if cosine < tau (tau cross-fitted) | 0.266 [0.20-0.34] | 0.690 [0.62-0.76] | 0.945 [0.92-0.97] | 0.214 [0.20-0.23] | [-0.016, +0.017] | 10/822 [0.001-0.026] |
| Similarity + decline, tau matched to ACH's open-world decline rate | 0.474 [0.40-0.55] | 0.230 [0.18-0.28] | 0.478 [0.42-0.54] | 0.208 [0.19-0.22] | [-0.014, +0.027] | 10/822 [0.001-0.026] |
| Similarity + decline, tau matched to ACH's closed-world accuracy | 0.299 [0.23-0.37] | 0.639 [0.56-0.71] | 0.934 [0.91-0.96] | 0.214 [0.20-0.23] | [-0.016, +0.017] | 10/822 [0.001-0.026] |
| Similarity + consistency gate (k cross-fitted) | 0.533 [0.45-0.61] | 0.000 [0.00-0.04]† | 0.000 [0.00-0.04]† | 0.204 [0.19-0.22] | [-0.005, +0.027] | 15/822 [0.007-0.031] |
| OCCAM ACH (full) | 0.299 [0.23-0.37] | 0.365 [0.30-0.43] | 0.460 [0.39-0.53] | 0.214 [0.20-0.23] | 1/822 [0.000-0.004] |
Brier score under the pooled map, per setting: ACH minus method (paired 95% CI)¶
| Method | Closed | Open | False flag | All three pooled |
|---|---|---|---|---|
| OCCAM ACH (full), value | 0.189 | 0.249 | 0.205 | 0.214 |
| TTP-similarity, marker boost 0.15 (shipped baseline) (0.315 / 0.032 / 0.131 / 0.160) | [-0.178, -0.075] | [+0.197, +0.238] | [+0.045, +0.104] | [+0.031, +0.080] |
| TTP-similarity, marker boost 0.05 (0.190 / 0.070 / 0.171 / 0.144) | [-0.040, +0.034] | [+0.156, +0.203] | [-0.004, +0.074] | [+0.048, +0.095] |
| TTP-similarity, marker boost 0.3 (0.315 / 0.042 / 0.016 / 0.124) | [-0.180, -0.072] | [+0.186, +0.229] | [+0.169, +0.211] | [+0.068, +0.111] |
| TTP-similarity, ignores spoofable rows (0.189 / 0.076 / 0.189 / 0.151) | [-0.037, +0.035] | [+0.150, +0.198] | [-0.024, +0.056] | [+0.039, +0.087] |
| IDF coverage, ignores spoofable rows (0.206 / 0.088 / 0.206 / 0.167) | [-0.054, +0.016] | [+0.139, +0.184] | [-0.039, +0.040] | [+0.021, +0.074] |
| Similarity + decline if cosine < tau (tau cross-fitted) (0.165 / 0.313 / 0.165 / 0.214) | [+0.000, +0.046] | [-0.088, -0.040] | [+0.011, +0.071] | [-0.016, +0.017] |
| Similarity + decline, tau matched to ACH's open-world decline rate (0.181 / 0.262 / 0.181 / 0.208) | [-0.020, +0.034] | [-0.040, +0.015] | [-0.005, +0.057] | [-0.014, +0.027] |
| Similarity + decline, tau matched to ACH's closed-world accuracy (0.170 / 0.302 / 0.170 / 0.214) | [-0.005, +0.040] | [-0.077, -0.030] | [+0.006, +0.067] | [-0.016, +0.017] |
| Similarity + consistency gate (k cross-fitted) (0.176 / 0.156 / 0.280 / 0.204) | [-0.011, +0.037] | [+0.070, +0.116] | [-0.112, -0.041] | [-0.005, +0.027] |
Ablations of ACH (each row removes one mechanism)¶
| Variant | Closed correct | Open correct | False flag correct | names framed | names true | Authentic: names true | Authentic: calls frame | Mimicry: correct | Mimicry: names framed | Brier, pooled map | Brier, variant minus full ACH (paired) | Overconfident errors, pooled map |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| OCCAM ACH (full) | 0.299 | 0.460 | 0.734 | 0.011 | 0.022 | 0.358 | 0.186 | 0.179 | 0.270 | 0.214 | 1/822 | |
| ACH without false-flag hypotheses | 0.299 | 0.460 | 0.201 | 0.011 | 0.201 | 0.369 | 0.000 | 0.179 | 0.270 | 0.207 | [-0.023, +0.011] | 1/822 |
| ACH without unknown-actor hypothesis | 0.372 | 0.000 | 0.945 | 0.033 | 0.026 | 0.518 | 0.372 | 0.212 | 0.307 | 0.181 | [-0.048, -0.020] | 27/822 |
| ACH without spoofable x0.5 discount | 0.299 | 0.460 | 0.726 | 0.011 | 0.004 | 0.372 | 0.193 | 0.179 | 0.270 | 0.231 | [+0.010, +0.023] | 1/822 |
| ACH without confidence caps | 0.299 | 0.460 | 0.734 | 0.011 | 0.022 | 0.358 | 0.186 | 0.179 | 0.270 | 0.207 | [-0.010, -0.005] | 2/822 |
| ACH without diagnosticity weighting | 0.237 | 0.723 | 0.631 | 0.004 | 0.022 | 0.263 | 0.117 | 0.168 | 0.182 | 0.234 | [+0.010, +0.029] | 0/822 |
| ACH without FF hypotheses, discount and caps | 0.299 | 0.460 | 0.131 | 0.026 | 0.131 | 0.401 | 0.000 | 0.179 | 0.270 | 0.207 | [-0.026, +0.011] | 0/822 |
| ACH, support-aware ranking | 0.401 | 0.055 | 0.887 | 0.015 | 0.131 | 0.507 | 0.255 | 0.245 | 0.354 | 0.203 | [-0.028, +0.005] | 5/822 |
| ACH, top-5 similarity shortlist | 0.339 | 0.642 | 0.679 | 0.011 | 0.018 | 0.350 | 0.153 | 0.230 | 0.292 | 0.234 | [+0.010, +0.030] | 4/822 |
Paired difference ACH minus method, 95% cluster-bootstrap interval¶
| Method | Closed: correct | Open: correct decline | False flag: correct | False flag: names framed | Authentic: names true | Authentic: calls it a frame | Mimicry: correct | Mimicry: names framed |
|---|---|---|---|---|---|---|---|---|
| TTP-similarity, marker boost 0.15 (shipped baseline) | [-0.317, -0.152] | [+0.393, +0.531] | [+0.534, +0.700] | [-0.921, -0.811] | [-0.712, -0.574] | [+0.138, +0.244] | [-0.101, +0.035] | [-0.560, -0.422] |
| TTP-similarity, marker boost 0.05 | [-0.317, -0.152] | [+0.393, +0.531] | [+0.147, +0.327] | [-0.160, -0.073] | [-0.573, -0.428] | [+0.138, +0.244] | [-0.101, +0.035] | [-0.560, -0.422] |
| TTP-similarity, marker boost 0.3 | [-0.317, -0.152] | [+0.393, +0.531] | [+0.669, +0.796] | [-1.000, -0.974] | [-0.712, -0.574] | [+0.138, +0.244] | [-0.101, +0.035] | [-0.560, -0.422] |
| TTP-similarity, ignores spoofable rows | [-0.317, -0.152] | [+0.393, +0.531] | [+0.111, +0.289] | [+0.000, +0.026] | [-0.260, -0.098] | [+0.138, +0.244] | [-0.101, +0.035] | [-0.560, -0.422] |
| IDF coverage, ignores spoofable rows | [-0.161, -0.082] | [+0.393, +0.531] | [+0.241, +0.396] | [+0.000, +0.026] | [-0.109, -0.011] | [+0.138, +0.244] | [-0.160, -0.066] | [-0.086, -0.018] |
| Similarity + decline if cosine < tau (tau cross-fitted) | [-0.053, +0.119] | [-0.560, -0.410] | [+0.371, +0.556] | [+0.000, +0.026] | [+0.004, +0.178] | [+0.138, +0.244] | [+0.008, +0.131] | [-0.252, -0.102] |
| Similarity + decline, tau matched to ACH's open-world decline rate | [-0.254, -0.100] | [-0.114, +0.073] | [+0.174, +0.352] | [+0.000, +0.026] | [-0.193, -0.044] | [+0.138, +0.244] | [-0.088, +0.046] | [-0.518, -0.372] |
| Similarity + decline, tau matched to ACH's closed-world accuracy | [-0.083, +0.080] | [-0.548, -0.396] | [+0.337, +0.525] | [+0.000, +0.026] | [-0.026, +0.140] | [+0.138, +0.244] | [-0.014, +0.116] | [-0.264, -0.120] |
| Similarity + consistency gate (k cross-fitted) | [-0.317, -0.152] | [+0.393, +0.531] | [-0.256, -0.122] | [-0.107, -0.037] | [-0.485, -0.342] | [-0.118, +0.025] | [-0.101, +0.035] | [-0.560, -0.422] |
Number of planted / mimicked items¶
| n | Method | False flag: names framed | Authentic: names true | Authentic: calls frame | Mimicry: names framed |
|---|---|---|---|---|---|
| 1 | TTP-similarity, marker boost 0.15 (shipped baseline) | 0.124 | 0.854 | 0.000 | 0.208 |
| 1 | TTP-similarity, ignores spoofable rows | 0.000 | 0.533 | 0.000 | 0.208 |
| 1 | IDF coverage, ignores spoofable rows | 0.000 | 0.420 | 0.000 | 0.036 |
| 1 | OCCAM ACH (full) | 0.007 | 0.321 | 0.153 | 0.066 |
| 1 | ACH without false-flag hypotheses | 0.007 | 0.336 | 0.000 | 0.066 |
| 1 | Similarity + consistency gate (k cross-fitted) | 0.080 | 0.770 | 0.230 | 0.208 |
| 6 | TTP-similarity, marker boost 0.15 (shipped baseline) | 1.000 | 1.000 | 0.000 | 0.909 |
| 6 | TTP-similarity, ignores spoofable rows | 0.000 | 0.533 | 0.000 | 0.909 |
| 6 | IDF coverage, ignores spoofable rows | 0.000 | 0.420 | 0.000 | 0.613 |
| 6 | OCCAM ACH (full) | 0.011 | 0.372 | 0.193 | 0.442 |
| 6 | ACH without false-flag hypotheses | 0.026 | 0.401 | 0.000 | 0.442 |
| 6 | Similarity + consistency gate (k cross-fitted) | 0.080 | 0.770 | 0.230 | 0.909 |
Correct: closed/authentic = names the true group; open = declines; false_flag/mimicry = names the true group or concludes the framed group was framed. Calls it a frame under authentic markers is a false alarm. Mimicry items are ordinary technique/software rows, so the gate cannot see them (it equals plain similarity there). Pooled map: one probability map (histogram binning; the learned grade map for ACH variants) fitted on closed + open + false_flag together and cross-fitted by group, i.e. without knowing which setting an incident comes from; Brier and overconfident errors (wrong with calibrated probability >= 0.8) are over all three settings (822 answers). Per setting it gives similarity 0.315 / 0.032 / 0.131 and ACH 0.189 / 0.249 / 0.205 (closed / open / false_flag), the same map as the pooled table in results/attribution.md. The pooled number depends on the equal 1:1:1 mix of settings. Raw (uncalibrated) overconfident errors under planted markers: similarity 194/274, ACH 0/274. Brier rewards a matcher that is always framed but states low probabilities: marker boost 0.3 is framed 1.000 of the time under planted markers, yet has the lowest pooled Brier (0.124; false flag 0.016), so Brier alone does not measure resistance to framing.
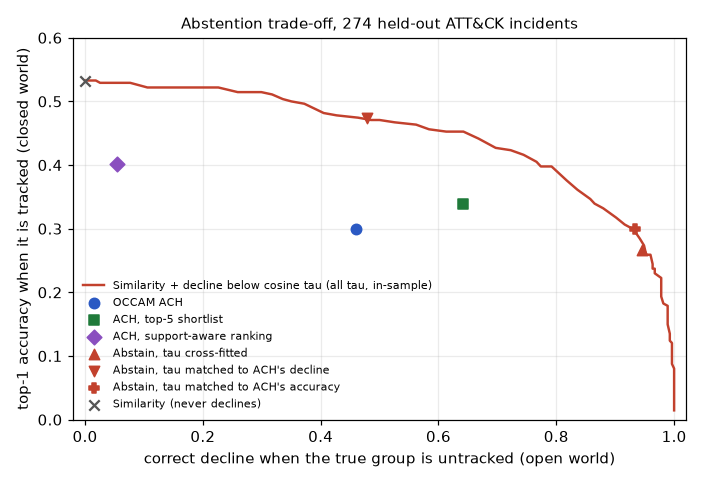
ACH's operating point lies inside the frontier of the cosine-threshold baseline (red curve). The curve is in-sample. The marked baseline points are cross-fitted.
2. Sensitivity to the hand-set cell-rule thresholds¶
Methodology: the same incidents, markers and framing seed. Plain ACH is rerun with the "common technique" cut-off at 20%, 30% or 40% of groups and the "rare" cut-off at 2, 3 or 5 groups. A cross-fitted row picks the thresholds on one group fold and applies them to the other.
274 held-out incidents from 103 groups, 3 markers. cX-rY: a technique used by at least X of all groups is non-diagnostic, one used by at most Y groups is rare (CC on a match). Shipped: c0.3-r3 (hand-set). Cross-fitted: each group fold uses the configuration with the best mean accuracy over the five settings on the other fold (chosen: {0: 'c0.2-r5', 1: 'c0.2-r3'}).
Source: GitHub Actions run 37093689060, commit 09cde53, 2026-10-03T03:35:51+00:00.
| Thresholds | Closed correct | Open correct decline | False flag correct | False flag names framed | Authentic: calls it a frame | Mimicry correct | Mimicry names framed |
|---|---|---|---|---|---|---|---|
| c0.2-r2 | 0.310 | 0.591 | 0.701 | 0.007 | 0.212 | 0.168 | 0.354 |
| c0.2-r3 | 0.332 | 0.489 | 0.752 | 0.007 | 0.245 | 0.186 | 0.350 |
| c0.2-r5 | 0.354 | 0.391 | 0.803 | 0.011 | 0.274 | 0.201 | 0.361 |
| c0.3-r2 | 0.285 | 0.577 | 0.668 | 0.007 | 0.157 | 0.164 | 0.274 |
| c0.3-r3 (shipped) | 0.299 | 0.460 | 0.734 | 0.011 | 0.186 | 0.179 | 0.270 |
| c0.3-r5 | 0.325 | 0.369 | 0.766 | 0.011 | 0.230 | 0.201 | 0.292 |
| c0.4-r2 | 0.270 | 0.588 | 0.642 | 0.007 | 0.150 | 0.172 | 0.248 |
| c0.4-r3 | 0.285 | 0.482 | 0.708 | 0.007 | 0.172 | 0.186 | 0.248 |
| c0.4-r5 | 0.310 | 0.380 | 0.759 | 0.007 | 0.215 | 0.212 | 0.263 |
| cross-fitted choice | 0.339 | 0.420 | 0.774 | 0.011 | 0.259 | 0.190 | 0.358 |
Paired difference, configuration minus shipped (95% cluster-bootstrap interval):
| Thresholds | Closed correct | Open correct decline | False flag correct | False flag names framed | Authentic: calls it a frame | Mimicry correct | Mimicry names framed |
|---|---|---|---|---|---|---|---|
| c0.2-r2 | [-0.019, +0.040] | [+0.084, +0.183] | [-0.073, +0.007] | [-0.018, +0.007] | [-0.004, +0.057] | [-0.043, +0.019] | [+0.050, +0.120] |
| c0.2-r3 | [+0.011, +0.058] | [-0.004, +0.065] | [-0.007, +0.042] | [-0.018, +0.007] | [+0.030, +0.088] | [-0.022, +0.037] | [+0.046, +0.116] |
| c0.2-r5 | [+0.026, +0.085] | [-0.117, -0.022] | [+0.033, +0.111] | [-0.011, +0.011] | [+0.055, +0.122] | [-0.007, +0.055] | [+0.055, +0.130] |
| c0.3-r2 | [-0.036, +0.000] | [+0.077, +0.159] | [-0.098, -0.036] | [-0.011, +0.000] | [-0.051, -0.011] | [-0.030, -0.004] | [-0.007, +0.018] |
| c0.3-r5 | [+0.004, +0.052] | [-0.133, -0.056] | [+0.007, +0.067] | [+0.000, +0.000] | [+0.022, +0.068] | [+0.004, +0.041] | [+0.004, +0.043] |
| c0.4-r2 | [-0.054, -0.007] | [+0.084, +0.175] | [-0.130, -0.053] | [-0.011, +0.000] | [-0.059, -0.015] | [-0.026, +0.008] | [-0.043, -0.004] |
| c0.4-r3 | [-0.029, -0.004] | [+0.007, +0.044] | [-0.048, -0.007] | [-0.011, +0.000] | [-0.030, -0.004] | [+0.000, +0.019] | [-0.040, -0.007] |
| c0.4-r5 | [-0.015, +0.040] | [-0.124, -0.041] | [+0.000, +0.059] | [-0.011, +0.000] | [+0.004, +0.055] | [+0.011, +0.059] | [-0.030, +0.015] |
| cross-fitted choice | [+0.015, +0.069] | [-0.091, +0.007] | [+0.015, +0.068] | [-0.011, +0.011] | [+0.042, +0.108] | [-0.018, +0.041] | [+0.053, +0.124] |
3. Attribution on held-out ATT&CK group usage¶
Methodology (ADR 0004): every (group, cited report) pair with at least 4 techniques/software becomes an incident (at most 3 per group); items supported only by that report are removed from the group's profile first. closed: the true group is a candidate; open: it is removed and the right answer is to decline; false_flag: 3 spoofable markers frame a random other group.
274 leave-one-report-out incidents from 103 groups; 176 candidate group profiles; 3 planted markers in the false-flag setting. 95% CIs: group-cluster bootstrap; † = the rate is exactly 0 or 1, so the bootstrap interval is degenerate and a Wilson interval with the number of groups as the sample size is shown.
Source: GitHub Actions run 37093689060, commit 09cde53, 2026-10-03T03:35:50+00:00.
| Setting | Method | Correct [95% CI] | Names true group | Framed | Brier [95% CI] | ECE | Overconfident errors [95% CI] | Brier (recal.) | ECE (recal.) |
|---|---|---|---|---|---|---|---|---|---|
| closed | TTP-similarity baseline | 0.533 [0.45-0.61] | 0.533 | 0.000 | 0.179 [0.15-0.21] | 0.102 | 0.011 [0.00-0.03] | 0.180 | 0.068 |
| closed | OCCAM ACH | 0.299 [0.23-0.37] | 0.299 | 0.000 | 0.238 [0.22-0.25] | 0.257 | 0.000 [0.00-0.04]† | 0.156 | 0.007 |
| closed | OCCAM ACH, top-5 similarity shortlist | 0.339 [0.27-0.41] | 0.339 | 0.000 | 0.264 [0.24-0.28] | 0.253 | 0.007 [0.00-0.02] | 0.201 | 0.075 |
| closed | OCCAM ACH, support-aware ranking | 0.401 [0.32-0.47] | 0.401 | 0.000 | 0.223 [0.20-0.24] | 0.240 | 0.004 [0.00-0.01] | 0.161 | 0.071 |
| open | TTP-similarity baseline | 0.000 [0.00-0.04]† | 0.000 | 0.000 | 0.077 [0.06-0.09] | 0.206 | 0.015 [0.00-0.03] | 0.000 | 0.000 |
| open | OCCAM ACH | 0.460 [0.39-0.53] | 0.000 | 0.000 | 0.248 [0.24-0.26] | 0.071 | 0.004 [0.00-0.01] | 0.245 | 0.064 |
| open | OCCAM ACH, top-5 similarity shortlist | 0.642 [0.58-0.70] | 0.000 | 0.000 | 0.234 [0.22-0.25] | 0.086 | 0.011 [0.00-0.02] | 0.222 | 0.036 |
| open | OCCAM ACH, support-aware ranking | 0.055 [0.03-0.09] | 0.000 | 0.000 | 0.303 [0.29-0.32] | 0.493 | 0.015 [0.00-0.03] | 0.052 | 0.001 |
| false_flag | TTP-similarity baseline | 0.113 [0.06-0.17] | 0.113 | 0.880 | 0.700 [0.65-0.75] | 0.755 | 0.708 [0.64-0.78] | 0.100 | 0.054 |
| false_flag | OCCAM ACH | 0.734 [0.67-0.80] | 0.022 | 0.011 | 0.199 [0.19-0.21] | 0.144 | 0.000 [0.00-0.04]† | 0.176 | 0.023 |
| false_flag | OCCAM ACH, top-5 similarity shortlist | 0.679 [0.61-0.75] | 0.018 | 0.011 | 0.206 [0.19-0.22] | 0.096 | 0.000 [0.00-0.04]† | 0.192 | 0.032 |
| false_flag | OCCAM ACH, support-aware ranking | 0.887 [0.85-0.92] | 0.131 | 0.015 | 0.170 [0.16-0.18] | 0.285 | 0.000 [0.00-0.04]† | 0.094 | 0.054 |
Correct: closed = names the true group; open = declines to name (true group absent); false_flag = names the true group or concludes the framed group was framed. Overconfident errors: wrong with stated probability >= 0.8. recal.: histogram binning cross-fitted over a 2-fold group split.
Setting-agnostic calibration (the realistic number)¶
One map fitted on closed + open + false_flag together, cross-fitted by group. The per-setting maps further below know which setting an incident comes from and are an oracle upper bound. Canonical pooled-calibration table; results/falseflag.md quotes the same map as one number over all three settings. A single map cannot help the similarity baseline: it never declines, so all its open-world answers are wrong and the map pulls every probability down. The closed-world Brier therefore rises from 0.179 (raw) to 0.315, while the open-world Brier falls to 0.032. Overconfident errors: wrong with calibrated probability >= 0.8.
| Setting | Method | Brier (pooled map) | ECE (pooled map) | Overconfident errors (pooled map) [95% CI] |
|---|---|---|---|---|
| closed | TTP-similarity baseline | 0.315 | 0.321 | 0/274 [0.000-0.036]† |
| closed | OCCAM ACH | 0.189 | 0.174 | 0/274 [0.000-0.036]† |
| closed | OCCAM ACH, top-5 similarity shortlist | 0.253 | 0.217 | 2/274 [0.000-0.018] |
| closed | OCCAM ACH, support-aware ranking | 0.171 | 0.108 | 1/274 [0.000-0.011] |
| open | TTP-similarity baseline | 0.032 | 0.139 | 0/274 [0.000-0.036]† |
| open | OCCAM ACH | 0.249 | 0.067 | 1/274 [0.000-0.011] |
| open | OCCAM ACH, top-5 similarity shortlist | 0.240 | 0.110 | 2/274 [0.000-0.018] |
| open | OCCAM ACH, support-aware ranking | 0.186 | 0.316 | 4/274 [0.004-0.029] |
| false_flag | TTP-similarity baseline | 0.131 | 0.178 | 0/274 [0.000-0.036]† |
| false_flag | OCCAM ACH | 0.205 | 0.158 | 0/274 [0.000-0.036]† |
| false_flag | OCCAM ACH, top-5 similarity shortlist | 0.209 | 0.123 | 0/274 [0.000-0.036]† |
| false_flag | OCCAM ACH, support-aware ranking | 0.252 | 0.394 | 0/274 [0.000-0.036]† |
Learned grade -> probability map, fitted per setting (oracle upper bound)¶
Stated probability per ACH grade, learned (Beta-smoothed, monotone) instead of fixed ICD-203 midpoints. Brier with the learned map is cross-fitted over a 2-fold group split.
| Setting | Method | Brier (ICD-203 midpoints) | Brier (learned grades) | ECE (learned grades) |
|---|---|---|---|---|
| closed | OCCAM ACH | 0.238 | 0.156 | 0.012 |
| closed | OCCAM ACH, top-5 similarity shortlist | 0.264 | 0.201 | 0.073 |
| closed | OCCAM ACH, support-aware ranking | 0.223 | 0.161 | 0.072 |
| open | OCCAM ACH | 0.248 | 0.245 | 0.064 |
| open | OCCAM ACH, top-5 similarity shortlist | 0.234 | 0.227 | 0.038 |
| open | OCCAM ACH, support-aware ranking | 0.303 | 0.053 | 0.017 |
| false_flag | OCCAM ACH | 0.199 | 0.177 | 0.033 |
| false_flag | OCCAM ACH, top-5 similarity shortlist | 0.206 | 0.192 | 0.040 |
| false_flag | OCCAM ACH, support-aware ranking | 0.170 | 0.094 | 0.066 |
Shipped map (fit on all settings of plain ACH, results/grade_calibration.json): low = 0.370 (n=568), moderate = 0.777 (n=245), high = 0.818 (n=9)
False-flag setting across framing seeds [7, 11, 13, 17, 19]¶
| Method | Correct, mean ± sample SD | Names framed group, mean ± sample SD | Brier, mean ± sample SD |
|---|---|---|---|
| TTP-similarity baseline | 0.119 ± 0.009 | 0.875 ± 0.009 | 0.699 ± 0.006 |
| OCCAM ACH | 0.718 ± 0.017 | 0.008 ± 0.006 | 0.196 ± 0.004 |
| OCCAM ACH, top-5 similarity shortlist | 0.680 ± 0.014 | 0.008 ± 0.006 | 0.203 ± 0.003 |
| OCCAM ACH, support-aware ranking | 0.894 ± 0.009 | 0.020 ± 0.008 | 0.169 ± 0.003 |
4. Extended protocols: all reports, campaigns, unattributed, temporal¶
Methodology:
loro-alldrops the per-group cap, giving 575 incidents.campaignsholds out ATT&CK campaign objects with all their references.unattributedasks for a decline on campaigns ATT&CK does not attribute.unattributed-cleandrops those whose description names a tracked group.temporal-Xbuilds profiles from an older ATT&CK release and attributes activity added to ATT&CK after it, with renamed technique ids mapped back to the old release.
Source: GitHub Actions run 37093689060, commit 09cde53, 2026-10-03T03:35:44+00:00.
| Protocol | Incidents | Groups | Candidate profiles |
|---|---|---|---|
loro-all: Leave-one-report-out, every (group, report) pair, no per-group cap |
575 (0 campaigns) | 103 | 176 |
campaigns: ATT&CK campaigns attributed to a group, held out with all their references |
21 (21 campaigns) | 15 | 176 |
unattributed: ATT&CK campaigns with no attributed group (correct = decline) |
31 (31 campaigns) | 0 | 176 |
unattributed-clean: As unattributed, minus campaigns whose ATT&CK description names a tracked group |
21 (21 campaigns) | 0 | 176 |
temporal-12.1: Profiles from ATT&CK v12.1 (released Nov 2022); incidents added to ATT&CK after it (in v19.2) |
89 (15 campaigns) | 26 | 133 |
temporal-15.1: Profiles from ATT&CK v15.1 (released May 2024); incidents added to ATT&CK after it (in v19.2) |
69 (9 campaigns) | 22 | 148 |
unattributed: 10 campaigns name a tracked group in their own description (excluded in unattributed-clean).
temporal-12.1 id mapping: 1506 items, 1327 known to the old release, 17 mapped via revoked-by, 54 to the parent technique, 108 dropped (7.2%); 81 of 96 incidents had an unknown id; 89 kept (>= 4 items).
temporal-15.1 id mapping: 1133 items, 1009 known to the old release, 23 mapped via revoked-by, 22 to the parent technique, 79 dropped (7.0%); 61 of 77 incidents had an unknown id; 69 kept (>= 4 items).
| Protocol | Setting | Method | Correct [95% CI] | Names true group | Framed | Brier | Overconfident errors |
|---|---|---|---|---|---|---|---|
| loro-all | closed | TTP-similarity baseline | 0.478 [0.40-0.56] | 0.478 | 0.000 | 0.205 | 0.019 |
| loro-all | closed | OCCAM ACH | 0.390 [0.31-0.45] | 0.390 | 0.000 | 0.228 | 0.000 |
| loro-all | closed | OCCAM ACH, top-5 similarity shortlist | 0.402 [0.33-0.47] | 0.402 | 0.000 | 0.250 | 0.005 |
| loro-all | closed | OCCAM ACH, support-aware ranking | 0.503 [0.42-0.56] | 0.503 | 0.000 | 0.204 | 0.003 |
| loro-all | open | TTP-similarity baseline | 0.000 [0.00-0.04]† | 0.000 | 0.000 | 0.089 | 0.024 |
| loro-all | open | OCCAM ACH | 0.473 [0.42-0.53] | 0.000 | 0.000 | 0.247 | 0.002 |
| loro-all | open | OCCAM ACH, top-5 similarity shortlist | 0.642 [0.59-0.69] | 0.000 | 0.000 | 0.233 | 0.014 |
| loro-all | open | OCCAM ACH, support-aware ranking | 0.064 [0.04-0.09] | 0.000 | 0.000 | 0.314 | 0.028 |
| loro-all | false_flag | TTP-similarity baseline | 0.073 [0.04-0.11] | 0.073 | 0.918 | 0.736 | 0.736 |
| loro-all | false_flag | OCCAM ACH | 0.739 [0.69-0.79] | 0.023 | 0.009 | 0.195 | 0.000 |
| loro-all | false_flag | OCCAM ACH, top-5 similarity shortlist | 0.697 [0.64-0.75] | 0.021 | 0.009 | 0.203 | 0.000 |
| loro-all | false_flag | OCCAM ACH, support-aware ranking | 0.894 [0.86-0.92] | 0.160 | 0.028 | 0.176 | 0.000 |
| campaigns | closed | TTP-similarity baseline | 0.286 [0.14-0.50] | 0.286 | 0.000 | 0.155 | 0.000 |
| campaigns | closed | OCCAM ACH | 0.238 [0.11-0.45] | 0.238 | 0.000 | 0.253 | 0.000 |
| campaigns | closed | OCCAM ACH, top-5 similarity shortlist | 0.238 [0.11-0.45] | 0.238 | 0.000 | 0.269 | 0.000 |
| campaigns | closed | OCCAM ACH, support-aware ranking | 0.429 [0.24-0.63] | 0.429 | 0.000 | 0.217 | 0.000 |
| campaigns | open | TTP-similarity baseline | 0.000 [0.00-0.15] | 0.000 | 0.000 | 0.027 | 0.000 |
| campaigns | open | OCCAM ACH | 0.619 [0.41-0.79] | 0.000 | 0.000 | 0.243 | 0.000 |
| campaigns | open | OCCAM ACH, top-5 similarity shortlist | 0.857 [0.65-0.95] | 0.000 | 0.000 | 0.181 | 0.000 |
| campaigns | open | OCCAM ACH, support-aware ranking | 0.048 [0.01-0.23] | 0.000 | 0.000 | 0.253 | 0.000 |
| campaigns | false_flag | TTP-similarity baseline | 0.000 [0.00-0.15] | 0.000 | 1.000 | 0.873 | 1.000 |
| campaigns | false_flag | OCCAM ACH | 0.667 [0.45-0.83] | 0.000 | 0.000 | 0.205 | 0.000 |
| campaigns | false_flag | OCCAM ACH, top-5 similarity shortlist | 0.571 [0.37-0.76] | 0.000 | 0.000 | 0.205 | 0.000 |
| campaigns | false_flag | OCCAM ACH, support-aware ranking | 1.000 [0.85-1.00] | 0.143 | 0.000 | 0.147 | 0.000 |
| unattributed | open | TTP-similarity baseline | 0.000 [0.00-0.11] | 0.000 | 0.000 | 0.096 | 0.065 |
| unattributed | open | OCCAM ACH | 0.484 [0.32-0.65] | 0.000 | 0.000 | 0.259 | 0.000 |
| unattributed | open | OCCAM ACH, top-5 similarity shortlist | 0.742 [0.57-0.86] | 0.000 | 0.000 | 0.228 | 0.000 |
| unattributed | open | OCCAM ACH, support-aware ranking | 0.000 [0.00-0.11] | 0.000 | 0.000 | 0.306 | 0.032 |
| unattributed-clean | open | TTP-similarity baseline | 0.000 [0.00-0.15] | 0.000 | 0.000 | 0.070 | 0.048 |
| unattributed-clean | open | OCCAM ACH | 0.571 [0.37-0.76] | 0.000 | 0.000 | 0.260 | 0.000 |
| unattributed-clean | open | OCCAM ACH, top-5 similarity shortlist | 0.762 [0.55-0.89] | 0.000 | 0.000 | 0.215 | 0.000 |
| unattributed-clean | open | OCCAM ACH, support-aware ranking | 0.000 [0.00-0.15] | 0.000 | 0.000 | 0.299 | 0.000 |
| temporal-12.1 | closed | TTP-similarity baseline | 0.202 [0.10-0.35] | 0.202 | 0.000 | 0.162 | 0.034 |
| temporal-12.1 | closed | OCCAM ACH | 0.213 [0.11-0.36] | 0.213 | 0.000 | 0.262 | 0.000 |
| temporal-12.1 | closed | OCCAM ACH, top-5 similarity shortlist | 0.213 [0.10-0.37] | 0.213 | 0.000 | 0.312 | 0.000 |
| temporal-12.1 | closed | OCCAM ACH, support-aware ranking | 0.270 [0.16-0.43] | 0.270 | 0.000 | 0.269 | 0.022 |
| temporal-12.1 | open | TTP-similarity baseline | 0.000 [0.00-0.13]† | 0.000 | 0.000 | 0.099 | 0.034 |
| temporal-12.1 | open | OCCAM ACH | 0.506 [0.43-0.58] | 0.000 | 0.000 | 0.262 | 0.000 |
| temporal-12.1 | open | OCCAM ACH, top-5 similarity shortlist | 0.764 [0.68-0.84] | 0.000 | 0.000 | 0.205 | 0.000 |
| temporal-12.1 | open | OCCAM ACH, support-aware ranking | 0.011 [0.00-0.04] | 0.000 | 0.000 | 0.338 | 0.045 |
| temporal-12.1 | false_flag | TTP-similarity baseline | 0.034 [0.00-0.08] | 0.034 | 0.966 | 0.835 | 0.910 |
| temporal-12.1 | false_flag | OCCAM ACH | 0.708 [0.62-0.83] | 0.011 | 0.000 | 0.190 | 0.000 |
| temporal-12.1 | false_flag | OCCAM ACH, top-5 similarity shortlist | 0.629 [0.53-0.75] | 0.011 | 0.000 | 0.211 | 0.000 |
| temporal-12.1 | false_flag | OCCAM ACH, support-aware ranking | 0.899 [0.84-0.95] | 0.056 | 0.045 | 0.161 | 0.000 |
| temporal-15.1 | closed | TTP-similarity baseline | 0.116 [0.03-0.25] | 0.116 | 0.000 | 0.123 | 0.014 |
| temporal-15.1 | closed | OCCAM ACH | 0.130 [0.06-0.23] | 0.130 | 0.000 | 0.274 | 0.000 |
| temporal-15.1 | closed | OCCAM ACH, top-5 similarity shortlist | 0.116 [0.04-0.22] | 0.116 | 0.000 | 0.326 | 0.000 |
| temporal-15.1 | closed | OCCAM ACH, support-aware ranking | 0.159 [0.06-0.29] | 0.159 | 0.000 | 0.282 | 0.014 |
| temporal-15.1 | open | TTP-similarity baseline | 0.000 [0.00-0.15]† | 0.000 | 0.000 | 0.087 | 0.014 |
| temporal-15.1 | open | OCCAM ACH | 0.493 [0.31-0.60] | 0.000 | 0.000 | 0.237 | 0.000 |
| temporal-15.1 | open | OCCAM ACH, top-5 similarity shortlist | 0.725 [0.60-0.82] | 0.000 | 0.000 | 0.197 | 0.000 |
| temporal-15.1 | open | OCCAM ACH, support-aware ranking | 0.014 [0.00-0.05] | 0.000 | 0.000 | 0.299 | 0.014 |
| temporal-15.1 | false_flag | TTP-similarity baseline | 0.014 [0.00-0.05] | 0.014 | 0.986 | 0.832 | 0.870 |
| temporal-15.1 | false_flag | OCCAM ACH | 0.681 [0.57-0.86] | 0.000 | 0.000 | 0.199 | 0.000 |
| temporal-15.1 | false_flag | OCCAM ACH, top-5 similarity shortlist | 0.609 [0.49-0.79] | 0.000 | 0.000 | 0.213 | 0.000 |
| temporal-15.1 | false_flag | OCCAM ACH, support-aware ranking | 0.928 [0.88-0.98] | 0.014 | 0.000 | 0.147 | 0.000 |
False-flag setting over framing seeds (mean ± sample SD):
| Protocol | Method | Correct | Names framed group | Names true group |
|---|---|---|---|---|
| loro-all | TTP-similarity baseline | 0.077 ± 0.003 | 0.914 ± 0.004 | 0.077 ± 0.003 |
| loro-all | OCCAM ACH | 0.736 ± 0.015 | 0.011 ± 0.004 | 0.019 ± 0.005 |
| loro-all | OCCAM ACH, top-5 similarity shortlist | 0.699 ± 0.015 | 0.010 ± 0.004 | 0.016 ± 0.005 |
| loro-all | OCCAM ACH, support-aware ranking | 0.894 ± 0.001 | 0.024 ± 0.007 | 0.145 ± 0.015 |
| campaigns | TTP-similarity baseline | 0.000 ± 0.000 | 1.000 ± 0.000 | 0.000 ± 0.000 |
| campaigns | OCCAM ACH | 0.733 ± 0.054 | 0.010 ± 0.021 | 0.000 ± 0.000 |
| campaigns | OCCAM ACH, top-5 similarity shortlist | 0.667 ± 0.075 | 0.000 ± 0.000 | 0.000 ± 0.000 |
| campaigns | OCCAM ACH, support-aware ranking | 0.943 ± 0.062 | 0.019 ± 0.026 | 0.057 ± 0.062 |
| temporal-12.1 | TTP-similarity baseline | 0.025 ± 0.005 | 0.973 ± 0.006 | 0.025 ± 0.005 |
| temporal-12.1 | OCCAM ACH | 0.730 ± 0.018 | 0.007 ± 0.010 | 0.018 ± 0.006 |
| temporal-12.1 | OCCAM ACH, top-5 similarity shortlist | 0.645 ± 0.022 | 0.004 ± 0.010 | 0.018 ± 0.006 |
| temporal-12.1 | OCCAM ACH, support-aware ranking | 0.926 ± 0.023 | 0.016 ± 0.019 | 0.061 ± 0.013 |
| temporal-15.1 | TTP-similarity baseline | 0.003 ± 0.006 | 0.997 ± 0.006 | 0.003 ± 0.006 |
| temporal-15.1 | OCCAM ACH | 0.713 ± 0.024 | 0.000 ± 0.000 | 0.003 ± 0.006 |
| temporal-15.1 | OCCAM ACH, top-5 similarity shortlist | 0.617 ± 0.022 | 0.000 ± 0.000 | 0.003 ± 0.006 |
| temporal-15.1 | OCCAM ACH, support-aware ranking | 0.933 ± 0.039 | 0.012 ± 0.016 | 0.014 ± 0.010 |
Correct: closed = names the true group; open = declines to name; false_flag = names the true group or concludes the framed group was framed. Temporal protocols use the old release's profiles and KB and hold nothing out. Intervals: group-cluster bootstrap (n >= 50), else Wilson score interval. † = a rate of exactly 0 or 1 (e.g. the similarity baseline never declines), whose bootstrap interval is degenerate: a Wilson interval with the number of groups as the sample size is shown instead.
5. Reproduction of published TTP extraction results (rcATT)¶
Methodology: rcATT's own data (1,490 reports), its label filter, the released code's 5-fold split and its metrics (Legoy et al., 2020, arXiv:2004.14322v1; paper numbers from Table 4, "Inde." rows). Four rcATT pipelines form a 2 x 2 ablation of the two settings in which the released code differs from the paper text: tokenisation, and balanced class weights. OCCAM's classifier family runs on the same folds.
1490 reports, 5-fold CV (KFold, shuffle, seed 42, as in the released code), binary relevance; mean ± SD over folds (dispersion of the 5 folds, not a confidence interval), percent.
Source: GitHub Actions run 37093689060, commit 09cde53, 2026-10-03T03:35:46+00:00.
Tactics (12 labels)¶
| Source | Micro P | Micro R | Micro F0.5 | Macro P | Macro R | Macro F0.5 |
|---|---|---|---|---|---|---|
| rcATT paper (Legoy et al. 2020, arXiv:2004.14322v1, Table 4 'Inde.' rows; same means in Tables 2-3, TF-IDF BR Linear SVC) | 65.64 ± 3.76 | 64.69 ± 3.00 | 65.38 ± 2.87 | 60.26 ± 3.20 | 58.50 ± 3.68 | 59.47 ± 2.29 |
| Reproduction, released rcATT pipeline (stemmed/lemmatised tokens, balanced class weights) | 64.97 ± 3.88 | 64.31 ± 2.32 | 64.82 ± 3.44 | 61.52 ± 4.93 | 58.00 ± 2.86 | 60.32 ± 4.23 |
| Released pipeline without class weighting | 71.37 ± 4.41 | 52.28 ± 2.10 | 66.50 ± 3.58 | 68.66 ± 6.72 | 42.29 ± 2.10 | 57.45 ± 4.48 |
| Pipeline as the paper text describes it (default tokens, no class weighting) | 71.81 ± 3.77 | 52.00 ± 2.14 | 66.71 ± 3.17 | 69.25 ± 6.11 | 41.82 ± 2.05 | 57.46 ± 3.98 |
| Paper-text pipeline with balanced class weights | 65.20 ± 4.24 | 63.93 ± 1.91 | 64.93 ± 3.71 | 61.47 ± 5.11 | 57.38 ± 2.52 | 60.14 ± 4.36 |
| OCCAM TF-IDF + LR, same folds | 61.07 ± 3.51 | 65.41 ± 3.14 | 61.88 ± 3.29 | 57.65 ± 5.15 | 59.50 ± 4.55 | 57.39 ± 5.03 |
| Effect on micro F0.5 (same 5 folds) | Fold-paired difference, mean ± SD |
|---|---|
| class weighting, released tokens | -1.67 ± 0.87 |
| class weighting, paper-text tokens | -1.79 ± 0.92 |
| rcATT tokenisation, balanced weights | -0.10 ± 0.46 |
| rcATT tokenisation, no weighting | -0.22 ± 0.78 |
| both (released minus paper text) | -1.89 ± 0.60 |
Techniques (197 labels)¶
| Source | Micro P | Micro R | Micro F0.5 | Macro P | Macro R | Macro F0.5 |
|---|---|---|---|---|---|---|
| rcATT paper (Legoy et al. 2020, arXiv:2004.14322v1, Table 4 'Inde.' rows; same means in Tables 2-3, TF-IDF BR Linear SVC) | 37.18 ± 6.75 | 29.79 ± 5.91 | 35.02 ± 5.32 | 28.84 ± 6.90 | 22.67 ± 5.94 | 25.06 ± 6.09 |
| Reproduction, released rcATT pipeline (stemmed/lemmatised tokens, balanced class weights) | 39.32 ± 2.02 | 27.95 ± 1.54 | 36.33 ± 1.39 | 33.99 ± 2.15 | 22.97 ± 1.48 | 28.86 ± 1.62 |
| Released pipeline without class weighting | 59.69 ± 2.38 | 10.33 ± 0.90 | 30.44 ± 1.48 | 22.27 ± 0.95 | 8.21 ± 0.96 | 14.66 ± 1.07 |
| Pipeline as the paper text describes it (default tokens, no class weighting) | 59.40 ± 3.09 | 9.70 ± 0.98 | 29.28 ± 2.05 | 20.91 ± 1.30 | 7.62 ± 1.00 | 13.64 ± 1.27 |
| Paper-text pipeline with balanced class weights | 39.86 ± 2.52 | 26.14 ± 1.22 | 36.06 ± 1.93 | 33.38 ± 1.58 | 21.40 ± 1.30 | 27.84 ± 1.34 |
| OCCAM TF-IDF + LR, same folds | 37.76 ± 2.12 | 24.81 ± 1.98 | 34.18 ± 2.10 | 15.93 ± 2.84 | 10.33 ± 1.13 | 12.94 ± 2.10 |
| Effect on micro F0.5 (same 5 folds) | Fold-paired difference, mean ± SD |
|---|---|
| class weighting, released tokens | +5.88 ± 2.51 |
| class weighting, paper-text tokens | +6.78 ± 3.17 |
| rcATT tokenisation, balanced weights | +0.27 ± 0.62 |
| rcATT tokenisation, no weighting | +1.16 ± 1.03 |
| both (released minus paper text) | +7.05 ± 2.86 |
6. TTP extraction on TRAM2¶
Methodology: 151 CTI reports, 5-fold cross-validation grouped by document; classifier thresholds tuned on an inner 20% document split.
Protocol: 5-fold CV grouped by document, seed 13; thresholds tuned on inner 20% doc split. ATT&CK v19.2.
Source: GitHub Actions run 37093689060, commit 09cde53, 2026-10-03T03:35:44+00:00.
| Method | Sent. P | Sent. R | Sent. micro-F1 | Sent. macro-F1 | Doc P | Doc R | Doc micro-F1 | Doc macro-F1 |
|---|---|---|---|---|---|---|---|---|
| Keyword baseline (ATT&CK technique names) | 0.395 | 0.071 | 0.121 | 0.134 | 0.686 | 0.270 | 0.387 | 0.355 |
| TF-IDF+LR trained on ATT&CK procedures only | 0.376 | 0.387 | 0.381 | 0.353 | 0.552 | 0.703 | 0.618 | 0.579 |
| TF-IDF+LR trained on ATT&CK + TRAM train folds | 0.471 | 0.518 | 0.493 | 0.446 | 0.647 | 0.787 | 0.710 | 0.663 |
| Method | Doc micro-F1, fold mean ± SD (dispersion) | Doc micro-F1, document bootstrap 95% CI |
|---|---|---|
| Keyword baseline (ATT&CK technique names) | 0.388 ± 0.044 | 0.329-0.434 |
| TF-IDF+LR trained on ATT&CK procedures only | 0.618 ± 0.030 | 0.587-0.648 |
| TF-IDF+LR trained on ATT&CK + TRAM train folds | 0.710 ± 0.023 | 0.680-0.738 |
2 TRAM labels (T1562.001, T1574.002) are revoked in ATT&CK v19.2, so the keyword and ATT&CK-only models cannot predict them (3.3% of sentence-level gold labels).
Best / worst techniques (sentence F1, ATT&CK+TRAM model):
| Technique | Support | F1 |
|---|---|---|
| T1140 Deobfuscate/Decode Files or Information | 466 | 0.712 |
| T1021.001 Remote Desktop Protocol | 99 | 0.688 |
| T1056.001 Keylogging | 62 | 0.673 |
| T1053.005 Scheduled Task | 118 | 0.664 |
| T1003.001 LSASS Memory | 112 | 0.662 |
| T1557.001 Name Resolution Poisoning and SMB Relay | 7 | 0.222 |
| T1074.001 Local Data Staging | 26 | 0.211 |
| T1005 Data from Local System | 61 | 0.196 |
| T1552.001 Credentials In Files | 22 | 0.182 |
| T1569.002 Service Execution | 22 | 0.176 |
7. Campaign clustering¶
Methodology: per-report slices of ATT&CK group activity plus attributed campaigns. Hyper-parameters are chosen on dev groups (even ATT&CK numbers) and reported on disjoint test groups. The test is capability-only, because ATT&CK records no infrastructure.
Hyper-parameters chosen on 239 dev events from 26 disjoint groups (dev ARI: kNN 0.369, dense 0.373). Brackets: 95% leave-one-group-out jackknife interval with each clustering held fixed (sampling variation of the test set only; estimate +- 1.96 SE).
Source: GitHub Actions run 37093689060, commit 09cde53, 2026-10-03T03:35:51+00:00.
| Method | Purity [95% CI] | NMI [95% CI] | ARI [95% CI] | #clusters |
|---|---|---|---|---|
| Louvain, IDF-weighted Jaccard kNN graph (k=10, res=5.0; dev-tuned) | 0.511 [0.44-0.58] | 0.642 [0.60-0.69] | 0.249 [0.17-0.32] | 37 |
| Louvain, dense graph (no kNN, res=5.0; dev-tuned) | 0.659 [0.57-0.75] | 0.705 [0.66-0.75] | 0.203 [0.14-0.26] | 84 |
| Louvain, dense graph (no kNN, default res=1.0) | 0.178 [0.09-0.26] | 0.255 [0.18-0.33] | 0.047 [-0.00-0.10] | 4 |
| Single-linkage Jaccard (t=0.3; dev-tuned = default) | 0.800 [0.71-0.89] | 0.694 [0.64-0.75] | 0.107 [-0.03-0.25] | 181 |
| Trivial: one cluster per event | 1.000 [1.00-1.00] | 0.753 [0.72-0.79] | 0.000 [0.00-0.00] | 270 |
ARI, kNN minus dense graph (paired jackknife, 95%): [-0.019, +0.110]. Louvain depends on input order: the selected kNN configuration on 10 random permutations of the test events gives ARI 0.248 ± 0.013 (sample SD; range 0.228-0.267).
8. End-to-end on APTnotes reports¶
Methodology:
- Reports. Public APT report PDFs whose file name or title names exactly one ATT&CK group.
- Pipeline. Text is extracted, the span-anchored extractor finds techniques and software, and the report is attributed against all 176 group profiles.
- Leak control. The leak-controlled rows first hold out ATT&CK citations of the true group that appear to be the same report.
Source: GitHub Actions run 37093689060, commit 09cde53, 2026-10-03T03:35:45+00:00.
Mean per report: 3.5 techniques, 2.5 software, 102.4 IOCs (all span-anchored). Evidence used: all. 3 reports with nothing extracted are scored as declines. 23 of 75 reports matched an ATT&CK citation of their own group (held out in the leak-controlled rows). 33 groups among the reports with extracted items (clustered below). Skipped: 1 (2014/h12756-wp-shell-crew.pdf: excluded: its converted text quotes webshell code and is quarantined by Windows Defender on the author's machine; skipped everywhere so local and CI runs match).
| Attributor | Profiles | Top-1 [Wilson 95%] | Top-5 | Names someone | Brier | Wrong at p>=0.8 [Wilson 95%] |
|---|---|---|---|---|---|---|
| TTP-similarity baseline | as-is (upper bound) | 0.320 [0.23-0.43] | 0.533 | 0.960 | 0.332 | 9/75 [0.06-0.21] |
| OCCAM ACH | as-is (upper bound) | 0.360 [0.26-0.47] | 0.493 | 0.840 | 0.216 | 0/75 [0.00-0.05] |
| OCCAM ACH, top-5 shortlist | as-is (upper bound) | 0.347 [0.25-0.46] | 0.533 | 0.640 | 0.225 | 0/75 [0.00-0.05] |
| TTP-similarity baseline | leak-controlled | 0.280 [0.19-0.39] | 0.493 | 0.960 | 0.333 | 9/75 [0.06-0.21] |
| OCCAM ACH | leak-controlled | 0.320 [0.23-0.43] | 0.467 | 0.827 | 0.229 | 0/75 [0.00-0.05] |
| OCCAM ACH, top-5 shortlist | leak-controlled | 0.293 [0.20-0.40] | 0.493 | 0.587 | 0.242 | 0/75 [0.00-0.05] |
| Exact McNemar test (same reports) | Correct only first | Correct only second | Both | p (two-sided) |
|---|---|---|---|---|
| ACH vs similarity, as-is | 12 | 9 | 15 | 0.664 |
| ACH vs similarity, leak-controlled | 12 | 9 | 12 | 0.664 |
| Clustering of the reports | Purity | NMI | ARI | #clusters |
|---|---|---|---|---|
| louvain (k=10, res=5.0) | 0.972 | 0.890 | 0.242 | 59 |
| single-linkage (t=0.3) | 0.986 | 0.874 | 0.068 | 68 |
Ablation: which kind of extracted evidence carries the signal?
Source: GitHub Actions run 37093689060, commit 09cde53, 2026-10-03T03:37:13+00:00.
Mean per report: 3.5 techniques, 2.5 software, 102.4 IOCs (all span-anchored). Evidence used: software. 15 reports with nothing extracted are scored as declines. 23 of 75 reports matched an ATT&CK citation of their own group (held out in the leak-controlled rows). 28 groups among the reports with extracted items (clustered below). Skipped: 1 (2014/h12756-wp-shell-crew.pdf: excluded: its converted text quotes webshell code and is quarantined by Windows Defender on the author's machine; skipped everywhere so local and CI runs match).
| Attributor | Profiles | Top-1 [Wilson 95%] | Top-5 | Names someone | Brier | Wrong at p>=0.8 [Wilson 95%] |
|---|---|---|---|---|---|---|
| TTP-similarity baseline | as-is (upper bound) | 0.520 [0.41-0.63] | 0.573 | 0.800 | 0.316 | 1/75 [0.00-0.07] |
| OCCAM ACH | as-is (upper bound) | 0.493 [0.38-0.60] | 0.560 | 0.773 | 0.201 | 0/75 [0.00-0.05] |
| OCCAM ACH, top-5 shortlist | as-is (upper bound) | 0.520 [0.41-0.63] | 0.573 | 0.773 | 0.198 | 0/75 [0.00-0.05] |
| TTP-similarity baseline | leak-controlled | 0.480 [0.37-0.59] | 0.547 | 0.800 | 0.325 | 1/75 [0.00-0.07] |
| OCCAM ACH | leak-controlled | 0.453 [0.35-0.57] | 0.533 | 0.760 | 0.214 | 0/75 [0.00-0.05] |
| OCCAM ACH, top-5 shortlist | leak-controlled | 0.480 [0.37-0.59] | 0.547 | 0.760 | 0.211 | 0/75 [0.00-0.05] |
| Exact McNemar test (same reports) | Correct only first | Correct only second | Both | p (two-sided) |
|---|---|---|---|---|
| ACH vs similarity, as-is | 1 | 3 | 36 | 0.625 |
| ACH vs similarity, leak-controlled | 1 | 3 | 33 | 0.625 |
| Clustering of the reports | Purity | NMI | ARI | #clusters |
|---|---|---|---|---|
| louvain (k=10, res=5.0) | 0.983 | 0.887 | 0.220 | 50 |
| single-linkage (t=0.3) | 1.000 | 0.873 | 0.080 | 57 |
Source: GitHub Actions run 37093689060, commit 09cde53, 2026-10-03T03:38:43+00:00.
Mean per report: 3.5 techniques, 2.5 software, 102.4 IOCs (all span-anchored). Evidence used: techniques. 6 reports with nothing extracted are scored as declines. 23 of 75 reports matched an ATT&CK citation of their own group (held out in the leak-controlled rows). 32 groups among the reports with extracted items (clustered below). Skipped: 1 (2014/h12756-wp-shell-crew.pdf: excluded: its converted text quotes webshell code and is quarantined by Windows Defender on the author's machine; skipped everywhere so local and CI runs match).
| Attributor | Profiles | Top-1 [Wilson 95%] | Top-5 | Names someone | Brier | Wrong at p>=0.8 [Wilson 95%] |
|---|---|---|---|---|---|---|
| TTP-similarity baseline | as-is (upper bound) | 0.000 [0.00-0.05] | 0.027 | 0.920 | 0.408 | 23/75 [0.21-0.42] |
| OCCAM ACH | as-is (upper bound) | 0.013 [0.00-0.07] | 0.093 | 0.560 | 0.288 | 0/75 [0.00-0.05] |
| OCCAM ACH, top-5 shortlist | as-is (upper bound) | 0.000 [0.00-0.05] | 0.027 | 0.387 | 0.305 | 0/75 [0.00-0.05] |
| TTP-similarity baseline | leak-controlled | 0.000 [0.00-0.05] | 0.013 | 0.920 | 0.408 | 23/75 [0.21-0.42] |
| OCCAM ACH | leak-controlled | 0.013 [0.00-0.07] | 0.093 | 0.560 | 0.288 | 0/75 [0.00-0.05] |
| OCCAM ACH, top-5 shortlist | leak-controlled | 0.000 [0.00-0.05] | 0.013 | 0.387 | 0.305 | 0/75 [0.00-0.05] |
| Exact McNemar test (same reports) | Correct only first | Correct only second | Both | p (two-sided) |
|---|---|---|---|---|
| ACH vs similarity, as-is | 1 | 0 | 0 | 1.000 |
| ACH vs similarity, leak-controlled | 1 | 0 | 0 | 1.000 |
| Clustering of the reports | Purity | NMI | ARI | #clusters |
|---|---|---|---|---|
| louvain (k=10, res=5.0) | 0.971 | 0.894 | 0.261 | 57 |
| single-linkage (t=0.3) | 0.986 | 0.877 | 0.053 | 66 |
With the sentence classifier added (top 10 techniques per report), including a paired test against the keyword-only run:
Source: GitHub Actions run 37093689060, commit 09cde53, 2026-10-03T03:42:20+00:00.
Mean per report: 12.5 techniques, 2.5 software, 102.4 IOCs (all span-anchored). Evidence used: all. 0 reports with nothing extracted are scored as declines. 23 of 75 reports matched an ATT&CK citation of their own group (held out in the leak-controlled rows). 33 groups among the reports with extracted items (clustered below). Skipped: 1 (2014/h12756-wp-shell-crew.pdf: excluded: its converted text quotes webshell code and is quarantined by Windows Defender on the author's machine; skipped everywhere so local and CI runs match).
| Attributor | Profiles | Top-1 [Wilson 95%] | Top-5 | Names someone | Brier | Wrong at p>=0.8 [Wilson 95%] |
|---|---|---|---|---|---|---|
| TTP-similarity baseline | as-is (upper bound) | 0.333 [0.24-0.45] | 0.507 | 1.000 | 0.194 | 0/75 [0.00-0.05] |
| OCCAM ACH | as-is (upper bound) | 0.187 [0.11-0.29] | 0.387 | 0.573 | 0.248 | 0/75 [0.00-0.05] |
| OCCAM ACH, top-5 shortlist | as-is (upper bound) | 0.187 [0.11-0.29] | 0.507 | 0.280 | 0.315 | 0/75 [0.00-0.05] |
| TTP-similarity baseline | leak-controlled | 0.293 [0.20-0.40] | 0.467 | 1.000 | 0.211 | 0/75 [0.00-0.05] |
| OCCAM ACH | leak-controlled | 0.160 [0.09-0.26] | 0.347 | 0.547 | 0.255 | 0/75 [0.00-0.05] |
| OCCAM ACH, top-5 shortlist | leak-controlled | 0.120 [0.06-0.21] | 0.467 | 0.213 | 0.327 | 0/75 [0.00-0.05] |
| Exact McNemar test (same reports) | Correct only first | Correct only second | Both | p (two-sided) |
|---|---|---|---|---|
| ACH vs similarity, as-is | 6 | 17 | 8 | 0.035 |
| ACH vs similarity, leak-controlled | 7 | 17 | 5 | 0.064 |
| ach (this run) vs aptnotes, leak-controlled | 0 | 12 | 12 | 4.9e-04 |
| similarity (this run) vs aptnotes, leak-controlled | 5 | 4 | 17 | 1.000 |
| Clustering of the reports | Purity | NMI | ARI | #clusters |
|---|---|---|---|---|
| louvain (k=10, res=5.0) | 0.920 | 0.866 | 0.217 | 58 |
| single-linkage (t=0.3) | 1.000 | 0.869 | 0.041 | 73 |