Evaluation¶
Every number on this page is generated by python benchmarks/make_figures.py from the
committed results/*.json, which the bench-extended, atlas-repro and CI (live-auditd)
GitHub Actions workflows produce from public data; each section names the run it comes from.
How to rerun everything is on Reproduce; the design rationale is
ADR 0006.
Methodology in brief¶
| Benchmark | Question | Ground truth | Unit / statistics |
|---|---|---|---|
| B1 causal edges | Which process start caused each effect, with GUIDs hidden? | Sysmon ProcessGuid lineage (objective; GUIDs hidden as a proxy for GUID-less sources) |
effect; CIs resample captures (10,000 reps, seed 7); macro F1 beside micro; paired capture-level sign and Wilcoxon tests for every comparison |
| Calibration | Do edge confidences mean what they say, and do they rank edges? | same GUID truth | ECE (10 bins), Brier, AUROC, selective prediction; fit on one corpus, test on another; capture bootstrap |
| B2 story ranking | Does reading stories reach the labelled technique sooner than a flat list? | ATT&CK labels in OTRF metadata | capture; equal event budget for every method; Wilson CIs, exact McNemar |
| B3 anti-forensics | Are log/timestamp tampering files flagged? | file-name labels (10 positives) | file; Wilson CIs, exact McNemar |
| B3b anti-forensics | Are the OTRF captures the dataset authors labelled T1562.002 flagged? | OTRF ATT&CK metadata (17 captures, 6 entries) | capture and entry; Wilson CIs, exact McNemar |
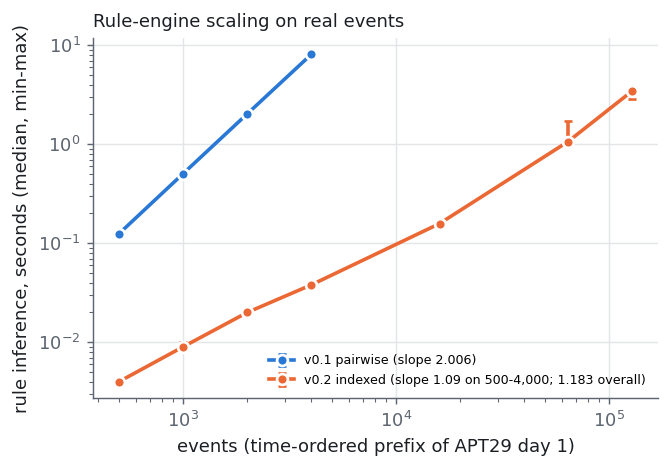
| B4 scale | Throughput and rule-engine complexity | - | GitHub-hosted runner; median and IQR of 5 runs, 3 per scaling point |
| B5 live auditd | Does a real kernel capture reconstruct end-to-end? | scripted benign sequence | 7 assertions in CI; Clopper-Pearson (consistency, not accuracy) |
| C ATLAS | Do ATLAS's published numbers follow from its release, and does its model re-run? | authors' released counts, outputs and model.h5 |
recomputation; evaluate.py re-run; TF 2.3 model re-run diffed against the release |
| C2 REVENANT under ATLAS | How does REVENANT score under ATLAS's own harness? | ATLAS malicious-entity labels, authors' evaluate.py |
attack; bootstrap over the 10 attacks, Wilson on pooled counts, exact sign tests |
Fairness rules: baselines see the same fused, de-duplicated events as REVENANT (B1) and the same event budget (B2); the strongest baseline in B1 (PID-then-image-nearest) implements REVENANT's own fallback idea, so it bounds what the rest of the engine adds. Corpus-scale runs happen on GitHub Actions runners, where no endpoint antivirus quarantines captures.
Headline results¶
| Benchmark (public data, ground truth) | REVENANT | Best baseline | Verdict | Source run |
|---|---|---|---|---|
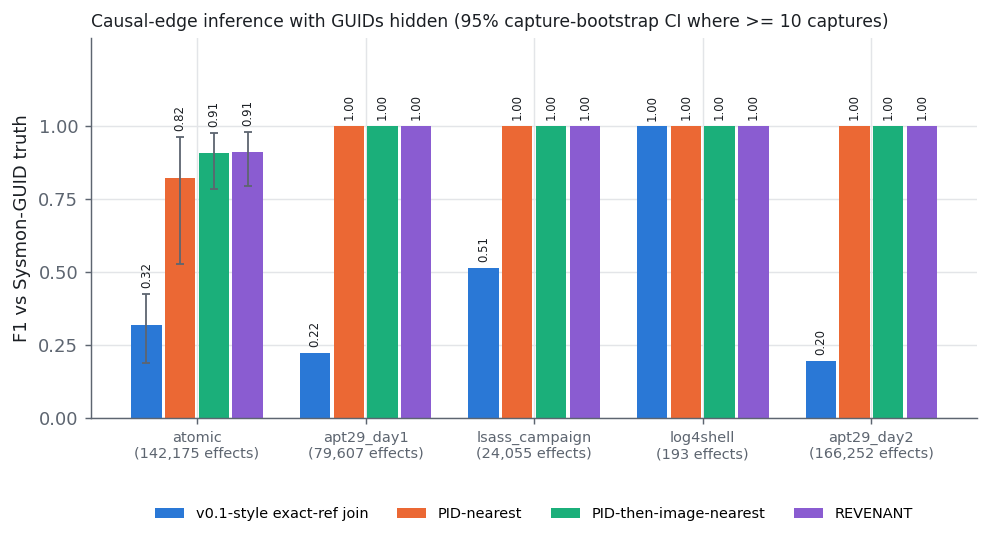
| B1 causal edges, OTRF atomic (120 captures, 102 with scorable effects; Sysmon GUIDs hidden as a proxy for GUID-less sources) | F1 0.910 [0.79, 0.98]; macro 0.931 | PID-then-image-nearest 0.906 [0.78, 0.97]; macro 0.923 | macro difference vs PID-nearest +0.194 [+0.129, +0.266], sign test p=4.6e-07; vs PID-then-image +0.008 [-0.000, +0.025], p=0.289 | 37093169942 |
| B1, APT29 day 1 + day 2, LSASS (7), Log4Shell | F1 0.999-1.000 | PID-nearest 1.000-1.000 | no difference (fewer than 10 captures per corpus: no CI) | 37093169942 |
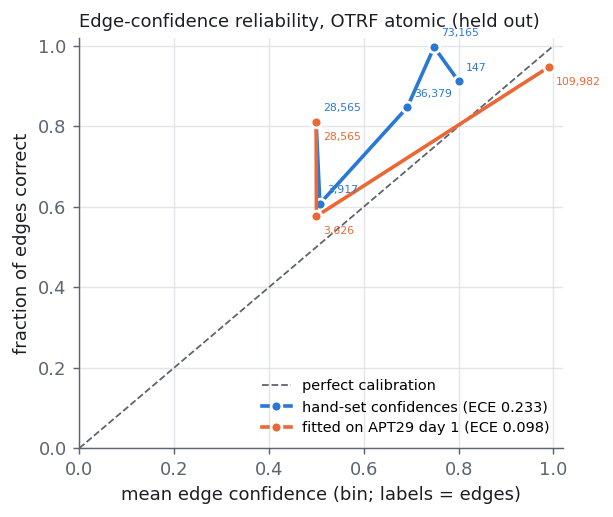
| Edge calibration, fit APT29 -> test atomic | ECE 0.098 [0.011, 0.260], AUROC 0.66 [0.42, 0.94] | hand-set ECE 0.233 [0.179, 0.300] | improved, not solved | 37093169942 |
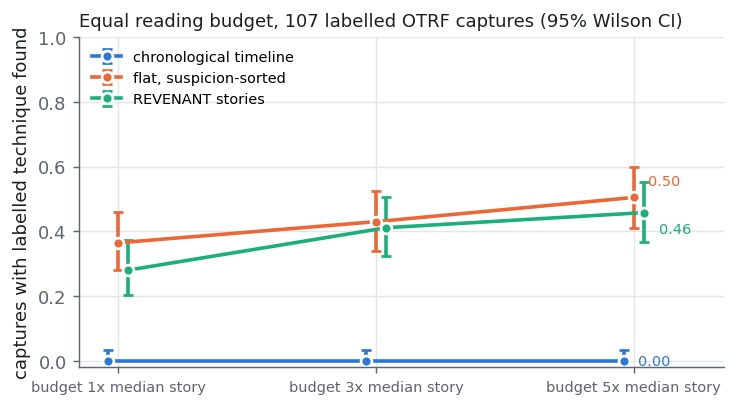
| B2 story ranking, 107 labelled captures, equal budget | hit@1 0.28 [0.20, 0.37] | flat suspicion-sorted 0.36 [0.28, 0.46] | lower, not significant (McNemar p=0.064) | 37093169942 |
| B3 anti-forensics, EVTX-ATTACK-SAMPLES (10 positives) | recall 0.80 [0.49, 0.94], precision 0.25 [0.13, 0.42] | 1102/104 recall 0.30; Sigma-equivalent recall 0.60, precision 0.20 | vs Sigma-equivalent on positives 2/0 discordant, p=0.500 | 37093169942 |
| B3b anti-forensics, OTRF T1562.002 captures (17 positives) | recall 1.00 [0.82, 1.00], precision 0.29 [0.19, 0.42] | 1102/104 recall 0.29; Sigma-equivalent recall 1.00, precision 0.29 | vs Sigma-equivalent on positives 0/0 discordant, p=1.000 | 37093169942 |
C ATLAS paper, authors' release and evaluate.py |
event F1 0.9988, entity F1 0.913; model re-run (TF 2.3) identical predictions on 15/16 test graphs | paper 0.9988 / 0.9376 | recomputed: macro event figures match Table 4's average; per-attack event counts differ for 8 of 10 attacks | 37090608948 |
| C2 REVENANT under the ATLAS protocol (10 attacks) | entity F1 0.556 [0.46, 0.64], event F1 0.574 [0.49, 0.65] | ATLAS (hand-cleaned) 0.913 / 0.9988 | worse on 10/10 attacks (sign test p=0.002) | 37090608948 |
| B5 live auditd capture in CI (scripted benign sequence) | 7/7 chain checks; 25/25 edges agree [0.86, 1.00] | - | consistency check, not accuracy | 37093169673 |
ATLAS rows: each multi-host attack is scored from its h2 folder, where the authors' procedure puts both hosts' outputs (its event totals equal the paper's); M4_h1's release has no cleaned predictions, so evaluate.py stops there with an error. Event-level paper figures come from Table 4 (Avg row, p. 3016) and Table 5 (p. 3017), not the abstract.
Figures¶
All tables¶
Generated by python benchmarks/make_figures.py from results/*.json; CIs are 95%. Each section names the workflow run that produced it.
B1 - causal edges vs Sysmon GUID ground truth¶
Source: results/edges.json, workflow bench-extended run 37093169942 (commit dd482ab).
Sysmon GUIDs are hidden from every method and used as the truth, so this is a proxy for GUID-less sources (Sysmon events keep their PID and image). Baselines run on the same fused, shadow-free events REVENANT sees. CIs resample captures (10,000 reps, seed 7); corpora with fewer than 10 scorable captures report n/a.
| corpus | captures (with effects) | effects | method | precision | recall | F1 [95% CI] | macro F1 [95% CI] |
|---|---|---|---|---|---|---|---|
| otrf_atomic | 120 (102) | 142,175 | v01_exact_ref_join | 0.461 | 0.199 | 0.278 [0.174, 0.356] | 0.3062 [0.258, 0.354] |
| otrf_atomic | 120 (102) | 142,175 | v01_exact_ref_join_fused | 0.783 | 0.199 | 0.317 [0.187, 0.425] | 0.3956 [0.330, 0.461] |
| otrf_atomic | 120 (102) | 142,175 | pid_nearest | 0.930 | 0.720 | 0.812 [0.510, 0.953] | 0.6864 [0.600, 0.766] |
| otrf_atomic | 120 (102) | 142,175 | pid_nearest_fused | 0.942 | 0.729 | 0.822 [0.528, 0.962] | 0.737 [0.649, 0.824] |
| otrf_atomic | 120 (102) | 142,175 | pid_image_nearest_fused | 0.907 | 0.905 | 0.906 [0.785, 0.974] | 0.923 [0.883, 0.958] |
| otrf_atomic | 120 (102) | 142,175 | revenant | 0.910 | 0.910 | 0.910 [0.793, 0.978] | 0.9312 [0.893, 0.963] |
| otrf_apt29_day1 | 1 (1) | 79,607 | v01_exact_ref_join | 0.500 | 0.126 | 0.202 [n/a (1 capture < 10)] | 0.2017 |
| otrf_apt29_day1 | 1 (1) | 79,607 | v01_exact_ref_join_fused | 1.000 | 0.126 | 0.224 [n/a (1 capture < 10)] | 0.2243 |
| otrf_apt29_day1 | 1 (1) | 79,607 | pid_nearest | 1.000 | 1.000 | 1.000 [n/a (1 capture < 10)] | 1.0 |
| otrf_apt29_day1 | 1 (1) | 79,607 | pid_nearest_fused | 1.000 | 1.000 | 1.000 [n/a (1 capture < 10)] | 1.0 |
| otrf_apt29_day1 | 1 (1) | 79,607 | pid_image_nearest_fused | 1.000 | 1.000 | 1.000 [n/a (1 capture < 10)] | 1.0 |
| otrf_apt29_day1 | 1 (1) | 79,607 | revenant | 1.000 | 1.000 | 1.000 [n/a (1 capture < 10)] | 1.0 |
| otrf_lsass_campaign | 7 (7) | 24,055 | v01_exact_ref_join | 0.688 | 0.347 | 0.461 [n/a (7 captures < 10)] | 0.4512 |
| otrf_lsass_campaign | 7 (7) | 24,055 | v01_exact_ref_join_fused | 0.997 | 0.347 | 0.514 [n/a (7 captures < 10)] | 0.5284 |
| otrf_lsass_campaign | 7 (7) | 24,055 | pid_nearest | 0.903 | 0.903 | 0.903 [n/a (7 captures < 10)] | 0.8591 |
| otrf_lsass_campaign | 7 (7) | 24,055 | pid_nearest_fused | 1.000 | 1.000 | 1.000 [n/a (7 captures < 10)] | 1.0 |
| otrf_lsass_campaign | 7 (7) | 24,055 | pid_image_nearest_fused | 1.000 | 1.000 | 1.000 [n/a (7 captures < 10)] | 1.0 |
| otrf_lsass_campaign | 7 (7) | 24,055 | revenant | 0.999 | 0.999 | 0.999 [n/a (7 captures < 10)] | 0.9985 |
| otrf_log4shell | 1 (1) | 193 | v01_exact_ref_join | 1.000 | 0.995 | 0.997 [n/a (1 capture < 10)] | 0.9974 |
| otrf_log4shell | 1 (1) | 193 | v01_exact_ref_join_fused | 1.000 | 0.995 | 0.997 [n/a (1 capture < 10)] | 0.9974 |
| otrf_log4shell | 1 (1) | 193 | pid_nearest | 1.000 | 1.000 | 1.000 [n/a (1 capture < 10)] | 1.0 |
| otrf_log4shell | 1 (1) | 193 | pid_nearest_fused | 1.000 | 1.000 | 1.000 [n/a (1 capture < 10)] | 1.0 |
| otrf_log4shell | 1 (1) | 193 | pid_image_nearest_fused | 1.000 | 1.000 | 1.000 [n/a (1 capture < 10)] | 1.0 |
| otrf_log4shell | 1 (1) | 193 | revenant | 1.000 | 1.000 | 1.000 [n/a (1 capture < 10)] | 1.0 |
| otrf_apt29_day2 | 1 (1) | 166,252 | v01_exact_ref_join | 0.512 | 0.109 | 0.180 [n/a (1 capture < 10)] | 0.1798 |
| otrf_apt29_day2 | 1 (1) | 166,252 | v01_exact_ref_join_fused | 1.000 | 0.109 | 0.197 [n/a (1 capture < 10)] | 0.1967 |
| otrf_apt29_day2 | 1 (1) | 166,252 | pid_nearest | 1.000 | 1.000 | 1.000 [n/a (1 capture < 10)] | 1.0 |
| otrf_apt29_day2 | 1 (1) | 166,252 | pid_nearest_fused | 1.000 | 1.000 | 1.000 [n/a (1 capture < 10)] | 1.0 |
| otrf_apt29_day2 | 1 (1) | 166,252 | pid_image_nearest_fused | 1.000 | 1.000 | 1.000 [n/a (1 capture < 10)] | 1.0 |
| otrf_apt29_day2 | 1 (1) | 166,252 | revenant | 1.000 | 1.000 | 1.000 [n/a (1 capture < 10)] | 1.0 |
Ablation (one component removed)¶
| corpus | variant | F1 [95% CI] | macro F1 [95% CI] |
|---|---|---|---|
| otrf_atomic | full engine | 0.910 [0.793, 0.978] | 0.9312 [0.893, 0.963] |
| otrf_atomic | without image-only fallback rules | 0.826 [0.534, 0.965] | 0.7449 [0.657, 0.824] |
| otrf_atomic | without image in the process key | 0.906 [0.786, 0.975] | 0.9232 [0.883, 0.958] |
| otrf_atomic | without PID-reuse (termination) guard | 0.910 [0.793, 0.978] | 0.9312 [0.893, 0.963] |
| otrf_atomic | without Sysmon/4688 fusion | 0.848 [0.680, 0.930] | 0.6836 [0.617, 0.748] |
| otrf_apt29_day1 | full engine | 1.000 n/a | 1.0 n/a |
| otrf_apt29_day1 | without image-only fallback rules | 1.000 n/a | 0.9998 n/a |
| otrf_apt29_day1 | without image in the process key | 1.000 n/a | 1.0 n/a |
| otrf_apt29_day1 | without PID-reuse (termination) guard | 1.000 n/a | 1.0 n/a |
| otrf_apt29_day1 | without Sysmon/4688 fusion | 0.993 n/a | 0.9931 n/a |
| otrf_lsass_campaign | full engine | 0.999 n/a | 0.9985 n/a |
| otrf_lsass_campaign | without image-only fallback rules | 0.999 n/a | 0.9983 n/a |
| otrf_lsass_campaign | without image in the process key | 1.000 n/a | 1.0 n/a |
| otrf_lsass_campaign | without PID-reuse (termination) guard | 1.000 n/a | 0.9993 n/a |
| otrf_lsass_campaign | without Sysmon/4688 fusion | 0.793 n/a | 0.7072 n/a |
| otrf_log4shell | full engine | 1.000 n/a | 1.0 n/a |
| otrf_log4shell | without image-only fallback rules | 1.000 n/a | 1.0 n/a |
| otrf_log4shell | without image in the process key | 1.000 n/a | 1.0 n/a |
| otrf_log4shell | without PID-reuse (termination) guard | 1.000 n/a | 1.0 n/a |
| otrf_log4shell | without Sysmon/4688 fusion | 1.000 n/a | 1.0 n/a |
| otrf_apt29_day2 | full engine | 1.000 n/a | 1.0 n/a |
| otrf_apt29_day2 | without image-only fallback rules | 1.000 n/a | 0.9999 n/a |
| otrf_apt29_day2 | without image in the process key | 1.000 n/a | 1.0 n/a |
| otrf_apt29_day2 | without PID-reuse (termination) guard | 1.000 n/a | 1.0 n/a |
| otrf_apt29_day2 | without Sysmon/4688 fusion | 0.998 n/a | 0.9981 n/a |
Paired comparisons over captures (OTRF atomic)¶
Per-capture F1 differences: macro difference with a paired capture bootstrap, exact sign test and Wilcoxon signed-rank test; micro (pooled-effect) difference with a paired capture bootstrap.
| comparison | macro F1 diff [95% CI] | better / worse / tied captures | sign test p | Wilcoxon p | micro F1 diff [95% CI] |
|---|---|---|---|---|---|
| revenant vs pid_nearest_fused | +0.194 [+0.129, +0.266] | 29 / 2 / 71 | 4.6e-07 | 2e-06 | +0.088 [+0.005, +0.300] |
| revenant vs pid_image_nearest_fused | +0.008 [-0.000, +0.025] | 6 / 2 / 94 | 0.289 | 0.109 | +0.004 [+0.000, +0.018] |
| revenant vs revenant_no_fallback | +0.186 [+0.122, +0.258] | 32 / 1 / 69 | 7.9e-09 | 9.8e-07 | +0.084 [+0.002, +0.294] |
| revenant vs revenant_no_image_in_key | +0.008 [-0.000, +0.024] | 5 / 2 / 95 | 0.453 | 0.219 | +0.004 [-0.000, +0.017] |
| revenant vs revenant_no_termination_guard | +0.000 [-0.000, +0.000] | 4 / 2 / 96 | 0.688 | 0.438 | +0.000 [-0.000, +0.000] |
| revenant vs revenant_no_fusion | +0.248 [+0.183, +0.315] | 45 / 0 / 57 | 5.7e-14 | 1e-08 | +0.062 [+0.027, +0.162] |
otrf_atomic: the 3 largest captures hold 56% of the effects; without them micro F1 is 0.8593 (REVENANT) vs 0.805 (PID-nearest).
Per effect type (F1, with n):
| corpus | effect | n | PID-nearest | PID-then-image | REVENANT |
|---|---|---|---|---|---|
| otrf_atomic | dns_query | 195 | 0.753 | 0.908 | 0.913 |
| otrf_atomic | file_delete | 707 | 0.803 | 0.916 | 0.916 |
| otrf_atomic | file_read | 557 | 0.826 | 0.890 | 0.890 |
| otrf_atomic | file_time_change | 329 | 0.905 | 0.994 | 0.994 |
| otrf_atomic | file_write | 2,435 | 0.809 | 0.966 | 0.968 |
| otrf_atomic | network_connect | 285 | 0.780 | 0.947 | 0.951 |
| otrf_atomic | pipe | 738 | 0.676 | 0.919 | 0.920 |
| otrf_atomic | process_access | 35,660 | 0.838 | 0.838 | 0.841 |
| otrf_atomic | process_start | 750 | 0.663 | 0.663 | 0.680 |
| otrf_atomic | registry_set | 100,512 | 0.818 | 0.929 | 0.935 |
| otrf_atomic | remote_thread | 7 | 0.923 | 0.923 | 1.000 |
| otrf_apt29_day1 | dns_query | 72 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day1 | file_delete | 367 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day1 | file_read | 179 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day1 | file_time_change | 205 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day1 | file_write | 1,283 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day1 | network_connect | 467 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day1 | pipe | 225 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day1 | process_access | 15,553 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day1 | process_start | 327 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day1 | registry_set | 60,927 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day1 | remote_thread | 2 | 1.000 | 1.000 | 1.000 |
| otrf_lsass_campaign | dns_query | 18 | 1.000 | 1.000 | 0.944 |
| otrf_lsass_campaign | file_delete | 569 | 1.000 | 1.000 | 0.997 |
| otrf_lsass_campaign | file_read | 105 | 1.000 | 1.000 | 1.000 |
| otrf_lsass_campaign | file_time_change | 194 | 1.000 | 1.000 | 1.000 |
| otrf_lsass_campaign | file_write | 6,617 | 1.000 | 1.000 | 1.000 |
| otrf_lsass_campaign | network_connect | 14 | 1.000 | 1.000 | 1.000 |
| otrf_lsass_campaign | pipe | 910 | 1.000 | 1.000 | 1.000 |
| otrf_lsass_campaign | process_access | 2,617 | 1.000 | 1.000 | 0.995 |
| otrf_lsass_campaign | process_start | 645 | 1.000 | 1.000 | 1.000 |
| otrf_lsass_campaign | registry_set | 12,364 | 1.000 | 1.000 | 0.999 |
| otrf_lsass_campaign | remote_thread | 2 | 1.000 | 1.000 | 1.000 |
| otrf_log4shell | dns_query | 1 | 1.000 | 1.000 | 1.000 |
| otrf_log4shell | file_delete | 2 | 1.000 | 1.000 | 1.000 |
| otrf_log4shell | file_write | 2 | 1.000 | 1.000 | 1.000 |
| otrf_log4shell | network_connect | 1 | 1.000 | 1.000 | 1.000 |
| otrf_log4shell | pipe | 1 | 1.000 | 1.000 | 1.000 |
| otrf_log4shell | process_access | 1 | 1.000 | 1.000 | 1.000 |
| otrf_log4shell | process_start | 1 | 1.000 | 1.000 | 1.000 |
| otrf_log4shell | registry_set | 184 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day2 | dns_query | 128 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day2 | file_delete | 478 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day2 | file_read | 177 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day2 | file_time_change | 274 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day2 | file_write | 3,427 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day2 | network_connect | 1,338 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day2 | pipe | 199 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day2 | process_access | 52,405 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day2 | process_start | 366 | 1.000 | 1.000 | 0.997 |
| otrf_apt29_day2 | registry_set | 107,458 | 1.000 | 1.000 | 1.000 |
| otrf_apt29_day2 | remote_thread | 2 | 1.000 | 1.000 | 1.000 |
Edge-confidence calibration¶
Source: results/edges.json, workflow bench-extended run 37093169942 (commit dd482ab).
Per-rule constants fitted on one corpus, tested on another, capped at 0.99 as the loader caps them. Rules seen fewer than 20 times in the fitting corpus are not in its table and keep their hand-set, time-decayed confidence; the 'table rules only' column restricts ECE to the rules the table covers. When every test edge is correct (APT29) ECE only measures how close the constants are to 1.
| test corpus | fitted on | ECE hand-set | ECE fitted (all edges) | ECE fitted (table rules only) | edges left hand-set | Brier | AUROC | test accuracy |
|---|---|---|---|---|---|---|---|---|
| otrf_apt29_day1 | otrf_atomic | 0.274 | 0.040 | 0.040 | 0 | 0.005 | n/a (all correct) | 1.0 |
| otrf_atomic | otrf_apt29_day1 | 0.233 | 0.098 | 0.043 | 32191 | 0.097 | 0.6624 | 0.9102 |
| otrf_atomic | otrf_lsass_campaign | 0.233 | 0.137 | 0.134 | 2341 | 0.126 | 0.674 | 0.9102 |
| otrf_atomic | otrf_log4shell | 0.233 | 0.113 | 0.010 | 71779 | 0.099 | 0.7681 | 0.9102 |
Capture bootstrap on OTRF atomic (102 captures, APT29-fitted table vs hand-set): ECE 0.098 [0.011, 0.260] vs 0.233 [0.179, 0.300] (difference [-0.245, -0.023]); AUROC 0.662 [0.417, 0.939] vs hand-set 0.768 [0.568, 0.946].
Selective prediction (keep only the highest-confidence edges; precision at a given share of edges kept):
| edges kept | hand-set confidences | APT29-fitted constants | gain [95% CI] |
|---|---|---|---|
| 50% | 0.997 [0.809, 1.000] | 0.947 [0.790, 0.998] | [-0.110, +0.015] |
| 80% | 0.910 [0.796, 0.998] | 0.927 [0.792, 0.998] | [-0.018, +0.066] |
| 90% | 0.910 [0.795, 0.996] | 0.914 [0.794, 0.996] | [-0.009, +0.046] |
| 100% | 0.910 [0.796, 0.979] | 0.910 [0.796, 0.979] | - |
The table REVENANT ships (src/revenant/data/rule_calibration.json, SHA-256 7e353c2c7291…) is refitted in this run on OTRF atomic (102 captures with effects, 142,173 edges). Its ECE on every corpus (held out except atomic), and that of the table shipped before this run:
| corpus | shipped table ECE | held out | previous table ECE |
|---|---|---|---|
| otrf_atomic | 0.005 | no (in-sample) | 0.035 |
| otrf_apt29_day1 | 0.040 | yes | 0.021 |
| otrf_lsass_campaign | 0.034 | yes | 0.019 |
| otrf_log4shell | 0.012 | yes | 0.011 |
| otrf_apt29_day2 | 0.057 | yes | 0.027 |
Story confidence and grades are not calibrated: they are a documented, hand-weighted sum (see Limitations).
B2 - story ranking vs flat timelines (OTRF atomic, ATT&CK labels from metadata)¶
Source: results/stories.json, workflow bench-extended run 37093169942 (commit dd482ab).
Every method gets the same event budget (k x the capture's median story size). The story-unit view gives the flat list exactly as many events as REVENANT's top-k whole stories contain. Note: 'found' uses REVENANT's own ATT&CK heuristics, and the shipped calibration table was fitted on the same captures.
| method | hit@1 [95% CI] | hit@3 [95% CI] | hit@5 [95% CI] | story-unit hit@1 / @3 / @5 | reached | median events read |
|---|---|---|---|---|---|---|
| chronological timeline | 0.000 [0.00, 0.03] | 0.000 [0.00, 0.03] | 0.000 [0.00, 0.03] | 0.000 / 0.019 / 0.019 | 60/107 | 196.5 |
| flat, suspicion-sorted | 0.364 [0.28, 0.46] | 0.430 [0.34, 0.52] | 0.505 [0.41, 0.60] | 0.439 / 0.514 / 0.523 | 60/107 | 0.0 |
| REVENANT stories | 0.280 [0.20, 0.37] | 0.411 [0.32, 0.51] | 0.458 [0.37, 0.55] | 0.411 / 0.477 / 0.495 | 56/107 | 1.0 |
Paired exact McNemar, REVENANT vs flat suspicion-sorted (captures found by REVENANT only / flat only, p):
hit@1: 5/14, p=0.064, hit@3: 7/9, p=0.804, hit@5: 0/5, p=0.062, story_hit@1: 3/6, p=0.508, story_hit@3: 0/4, p=0.125, story_hit@5: 0/3, p=0.250
Verdict at hit@1: lower, not significant (p=0.064).
B3 - anti-forensics on EVTX-ATTACK-SAMPLES (file level)¶
Source: results/antiforensics.json, workflow bench-extended run 37093169942 (commit dd482ab).
278 readable .evtx files, only 10 labelled as log/timestamp tampering by file name, so every interval is wide. Parser: 37,364 records (211.2 records/s on the runner); 58.1% of the 4,846 records in supported channels mapped. The logging_stopped indicator was written after seeing this benchmark's misses, so its before/after gain here is not a held-out estimate (B3b is).
| detector | precision [95% CI] | recall [95% CI] | F1 | TP | FP | FN |
|---|---|---|---|---|---|---|
| 1102/104 query (SIEM baseline) | 0.115 [0.04, 0.29] | 0.300 [0.11, 0.60] | 0.167 | 3 | 23 | 7 |
| Sigma-equivalent (1102/104, Sysmon 2, logging-disable keys, 4719) | 0.200 [0.10, 0.37] | 0.600 [0.31, 0.83] | 0.300 | 6 | 24 | 4 |
| REVENANT 1.1.0 indicators (before logging_stopped) | 0.200 [0.10, 0.37] | 0.600 [0.31, 0.83] | 0.300 | 6 | 24 | 4 |
| REVENANT, all indicators | 0.250 [0.13, 0.42] | 0.800 [0.49, 0.94] | 0.381 | 8 | 24 | 2 |
| REVENANT without log_cleared | 0.714 [0.36, 0.92] | 0.500 [0.24, 0.76] | 0.588 | 5 | 2 | 5 |
| REVENANT logging-tamper indicators only | 0.750 [0.30, 0.95] | 0.300 [0.11, 0.60] | 0.429 | 3 | 1 | 7 |
| REVENANT, high severity only | 0.226 [0.11, 0.40] | 0.700 [0.40, 0.89] | 0.342 | 7 | 24 | 3 |
Exact McNemar tests (REVENANT-only / other-only files, p):
- REVENANT vs 1102/104 query (SIEM baseline), positives: 5/0, p=0.062
- REVENANT vs 1102/104 query (SIEM baseline), all: 6/0, p=0.031
- REVENANT vs Sigma-equivalent (1102/104, Sysmon 2, logging-disable keys, 4719), positives: 2/0, p=0.500
- REVENANT vs Sigma-equivalent (1102/104, Sysmon 2, logging-disable keys, 4719), all: 2/0, p=0.500
- REVENANT vs REVENANT 1.1.0 indicators (before logging_stopped), positives: 2/0, p=0.500
- REVENANT vs REVENANT 1.1.0 indicators (before logging_stopped), all: 2/0, p=0.500
Missed positives: DE_remote_eventlog_svc_crash_byt3bl33d3r_sysmon_17_1_3.evtx, Sysmon_12_DE_AntiForensics_MRU_DeleteKey.evtx
B3b - anti-forensics on OTRF captures labelled T1562.002 (capture level)¶
Source: results/antiforensics_b3b.json, workflow bench-extended run 37093169942 (commit dd482ab).
Positives: the 17 host captures linked by the six OTRF metadata entries mapped to T1562.002 (Disable Windows Event Logging); negatives: 89 labelled atomic captures mapped to neither T1562 nor T1070. Many OTRF captures contain a genuine 1102/104 from the author clearing logs before recording, and benign Sysmon EID 2 events are common, so detector variants are shown separately. These captures were in the development corpus (B1/B2), so this is not a blind test of the older indicators.
| detector | precision [95% CI] | recall [95% CI] | F1 | TP | FP | FN |
|---|---|---|---|---|---|---|
| 1102/104 query (SIEM baseline) | 0.156 [0.07, 0.32] | 0.294 [0.13, 0.53] | 0.204 | 5 | 27 | 12 |
| Sigma-equivalent (1102/104, Sysmon 2, logging-disable keys, 4719) | 0.293 [0.19, 0.42] | 1.000 [0.82, 1.00] | 0.453 | 17 | 41 | 0 |
| REVENANT 1.1.0 indicators (before logging_stopped) | 0.293 [0.19, 0.42] | 1.000 [0.82, 1.00] | 0.453 | 17 | 41 | 0 |
| REVENANT, all indicators | 0.293 [0.19, 0.42] | 1.000 [0.82, 1.00] | 0.453 | 17 | 41 | 0 |
| REVENANT without log_cleared | 0.425 [0.29, 0.58] | 1.000 [0.82, 1.00] | 0.597 | 17 | 23 | 0 |
| REVENANT logging-tamper indicators only | 1.000 [0.78, 1.00] | 0.824 [0.59, 0.94] | 0.903 | 14 | 0 | 3 |
| REVENANT, high severity only | 0.298 [0.20, 0.43] | 1.000 [0.82, 1.00] | 0.460 | 17 | 40 | 0 |
Exact McNemar tests (REVENANT-only / other-only files, p):
- REVENANT vs 1102/104 query (SIEM baseline), positives: 12/0, p=0.00049
- REVENANT vs 1102/104 query (SIEM baseline), all: 26/0, p=3e-08
- REVENANT vs Sigma-equivalent (1102/104, Sysmon 2, logging-disable keys, 4719), positives: 0/0, p=1.000
- REVENANT vs Sigma-equivalent (1102/104, Sysmon 2, logging-disable keys, 4719), all: 0/0, p=1.000
- REVENANT vs REVENANT 1.1.0 indicators (before logging_stopped), positives: 0/0, p=1.000
- REVENANT vs REVENANT 1.1.0 indicators (before logging_stopped), all: 0/0, p=1.000
Metadata-entry level (an entry is found when any of its captures is flagged): baseline_1102_104 3/6 [0.19, 0.81]; sigma_equivalent 6/6 [0.61, 1.00]; revenant_v1_1 6/6 [0.61, 1.00]; revenant 6/6 [0.61, 1.00]; revenant_high_only 6/6 [0.61, 1.00]; revenant_excl_log_cleared 6/6 [0.61, 1.00]; revenant_logging_tamper 6/6 [0.61, 1.00]
Indicator counts, positive captures: {'timestomp_sysmon': 102, 'log_cleared': 5, 'audit_tamper': 95, 'logging_stopped': 1, 'clock_change': 1}; negative captures: {'timestomp_sysmon': 535, 'log_cleared': 48}. Missed positives (all indicators): none
Recall over both label sources combined (27 positives): baseline_1102_104 8/27 [0.16, 0.48]; sigma_equivalent 23/27 [0.68, 0.94]; revenant_v1_1 23/27 [0.68, 0.94]; revenant 25/27 [0.77, 0.98]; revenant_excl_log_cleared 22/27 [0.63, 0.92]; revenant_logging_tamper 17/27 [0.44, 0.78]; revenant_high_only 24/27 [0.72, 0.96]
B4 - scale (APT29 day 1, full capture)¶
Source: results/scale.json, workflow bench-extended run 37093169942 (commit dd482ab).
- Machine: Linux-6.17.0-1022-azure-x86_64-with-glibc2.39, Python 3.12.14.
- 128,101 normalized events from 196,081 raw rows (mapping coverage 65.3%)
- analysis of pre-parsed events (JSON parsing excluded): median 11.916 s (IQR 11.884-12.347 s over 5 runs; 10,750 events/s); median stage times: ingest 1.4 s, fusion 0.5 s, rules 3.6 s, antiforensics 3.6 s, stories 2.7 s
- 93,974 causal edges, 1,475 cross-artefact corroborations, 50 stories, 209 tamper/coverage indicators
- rule engine log-log slope on the common 500-4,000-event range: v0.1 2.006 vs v0.2 1.09; v0.2 over 500-128,101 events: 1.183; v0.1 extrapolated to the full capture: ~8,480 s
B5 - live auditd capture in CI (consistency check)¶
Source: results/live_auditd.json, workflow CI run 37093169673 (commit dd482ab).
63 events; 7/7 chain checks pass; the best story ranks 1 with coverage 0.857, grade HIGH; 25/25 inferred process edges agree with auditd's own pid/ppid (95% Clopper-Pearson [0.863, 1.000]). The parser reads the same fields, so this is an end-to-end regression check, not an independent accuracy measurement.
C - ATLAS reproduction (Alsaheel et al., USENIX Security 2021)¶
Source: results/atlas_repro.json, workflow atlas-repro run 37090608948 (commit 680cfb8).
Paper figures: entity level from abstract (p. 3005) and Table 4, Avg row (p. 3016); event level from Table 4, Avg row (p. 3016); Table 5, ATLAS row (p. 3017); precision also in §6.2.1 (p. 3015). The abstract gives no event-level figure.
| source | entity P / R / F1 | event P / R / F1 |
|---|---|---|
| paper | 0.9106 / 0.9729 / 0.9376 | 0.9988 / 0.9989 / 0.9988 |
| released per-attack counts (Table 4 rows), macro | 0.9106 / 0.9729 / 0.9376 | 0.9988 / 0.9989 / 0.9988 |
| released per-attack counts, pooled (micro) | 0.9040 / 0.9715 / 0.9365 | 0.9989 / 0.9995 / 0.9992 |
authors' evaluate.py re-run on the released outputs (10 attacks, macro) |
0.8786 / 0.9628 / 0.9132 | 0.9988 / 0.9988 / 0.9988 |
Which run scores each attack. Each multi-host attack (M-1..M-6) is scored from its h2 experiment folder, where ATLAS's procedure (README: copy the h1 output into the h2 output folder) makes evaluate.py read both hosts' outputs; its event totals equal the paper's (e.g. M-1: 251,675 events in h2 vs 121,114 in h1). The h1 folders score host 1 alone. In the release, M4_h1's eval_*.json has no cleaned predicted entities (field 0 is empty), so evaluate.py stops there with an error. M4_h1's error: ERROR: Please add the cleaned predicted entities for abstracted and raw logs..
Host-1-only figures (not comparable with the paper; n=9): entity F1 0.9410, event F1 0.9992.
The macro event figures match Table 4's average to 4 decimal places for precision, f1 (recall 0.9988 vs 0.9989), but per-attack event counts equal Table 4 only for S-1, S-2 (2 of 10); the largest difference is M-3 (+220 TP). Entity counts differ for every attack because evaluate.py counts unique graph words, not the spreadsheet's entities.
Released model outputs contain exactly the spreadsheet's event totals for 7/10 attacks.
Model re-run. atlas.py (testing mode, released model.h5, TensorFlow 2.3 in python:3.7-slim, no network) ran on 16/16 test graphs; graph words were identical to the release for 16 and the model's predicted words for 15. Scored by evaluate.py without the authors' manual cleaning (raw predicted words), the re-run gives entity F1 0.523 and event F1 0.9504 (the released raw predictions: 0.4578 / 0.9487); the paper's figures need the hand-cleaned list, which a re-run cannot regenerate.
Differences from the release: M-4 (M4_h1: 306 word predictions differ, max |p diff| 0.995244).
ATLASv2 link (https://uofi.box.com/s/feunur7280afxrfeb0af73recexa73yc, probed 2026-10-03T03:02:35+00:00): HEAD 404, GET 301, HEAD 404. The share link redirects to Box's web app, which serves HTML and rejects HEAD: no file URL is exposed for a scripted, checksum-pinned download, and the stated 160 GB uncompressed exceeds a standard GitHub-hosted runner's disk (14 GB SSD guaranteed).
C2 - REVENANT scored under the ATLAS protocol¶
Source: results/atlas_revenant.json, workflow atlas-repro run 37090608948 (commit 680cfb8).
Symptom-seeded stories over ATLAS's own test logs (labels stripped), entities mapped to ATLAS's label strings (docs/atlas-mapping.md) and scored by the authors' evaluate.py. ATLAS's released predictions were cleaned by hand; REVENANT's are automatic. CIs: bootstrap over the 10 attacks (10,000 reps, seed 7) for macro F1, Wilson on pooled counts.
| method | entity P / R / F1 (macro) | entity F1 [95% CI] | pooled entity P [CI] / R [CI] | event P / R / F1 (macro) | event F1 [95% CI] |
|---|---|---|---|---|---|
| ATLAS (released, hand-cleaned) | 0.879 / 0.963 / 0.913 | [0.890, 0.940] | 0.865 [0.81, 0.90] / 0.959 [0.92, 0.98] | 0.999 / 0.999 / 0.999 | [0.998, 1.000] |
| REVENANT story | 0.436 / 0.843 / 0.556 | [0.456, 0.642] | 0.367 [0.32, 0.41] / 0.830 [0.77, 0.88] | 0.413 / 0.997 / 0.574 | [0.492, 0.654] |
| REVENANT story, no cap | 0.436 / 0.843 / 0.556 | [0.456, 0.642] | 0.367 [0.32, 0.41] / 0.830 [0.77, 0.88] | 0.413 / 0.997 / 0.574 | [0.492, 0.654] |
| BackTracker-style reachability | 0.388 / 0.843 / 0.521 | [0.431, 0.607] | 0.367 [0.32, 0.41] / 0.830 [0.77, 0.88] | 0.307 / 0.997 / 0.459 | [0.378, 0.542] |
| symptom (and its DNS aliases) only | 1.000 / 0.464 / 0.623 | [0.544, 0.698] | 1.000 [0.96, 1.00] / 0.443 [0.38, 0.51] | 1.000 / 0.353 / 0.519 | [0.485, 0.556] |
- REVENANT vs ATLAS, entity F1: mean difference -0.357 [-0.442, -0.283], better on 0/10 attacks, worse on 10 (sign test p=0.002)
- REVENANT vs ATLAS, event F1: mean difference -0.425 [-0.508, -0.349], better on 0/10 attacks, worse on 10 (sign test p=0.002)
- REVENANT vs BackTracker-style reachability, entity F1: mean difference +0.035 [-0.035, +0.101], better on 6/10 attacks, worse on 3 (sign test p=0.508)
- REVENANT vs BackTracker-style reachability, event F1: mean difference +0.115 [+0.072, +0.160], better on 9/10 attacks, worse on 0 (sign test p=0.004)